GPU and NPU compute from Rust—no PyTorch or ROCm SDK installation.
Write GPU kernels in Loom, compile them
inside your application, and run them through HRX.
Add the crate with Cargo; the runtime and compiler download automatically on
first use, with pinned versions and verified hashes. GPU execution and Loom
compilation need no Python environment, HIP headers, or hipcc.
The unified native bundle contains libamdf, Loom, and the executable bridge. It compiles and executes GPU and NPU programs without a vendor SDK or external compiler toolchain. Native libraries download only on first use.
- Build with Cargo: no GPU SDK, C++ compiler, or native-library download at build time.
- Compile and reuse: Loom kernels compile in process and share a verified disk cache across applications.
- Control execution: owned buffers, ordered streams, events, and reusable graphs keep data and work on the device.
- Use the NPU too: compile and run native XDNA programs in process, and coordinate GPU/NPU work through one API.
Tested on AMD Strix Halo (gfx1151), on Linux x86_64. The host supplies the
kernel drivers and compatible system libraries; see requirements and setup.
The qualified NPU target is amd.xdna.strix_halo.17f0_11. Native device admission
rejects other profiles. Ubuntu 26.04 is the distribution baseline.
The package is hrx-rs; Rust imports and the primary CLI use hrx.
Native licenses, source provenance, and rebuild instructions are documented in
THIRD-PARTY.md.
These projects use HRX and Loom on AMD Strix Halo for local generation, computer vision, and vector search. They depend on HRX; HRX has no Cargo dependencies on these model crates. Model-specific pipelines and benchmarks belong in downstream applications.
| Project | What it does |
|---|---|
| hrxdb | Embedded GPU vector database with exact cosine search, batched top-k, and custom scoring over resident collections. |
| h3-hrx | MiniMax H3 video generation with sound, from text, a first frame, or image and audio references. |
| krea2-hrx | Krea 2 Turbo and Raw text-to-image generation with a complete text encoder, diffusion transformer, and VAE pipeline. |
| dinov3-hrx | DINOv3 image embeddings and patch features, with resident weights and reusable execution graphs. |
| arcface-hrx | ArcFace face embeddings with five-point alignment and cosine similarity. |
| scrfd-hrx | SCRFD face detection with bounding boxes, confidence scores, and five facial landmarks. |
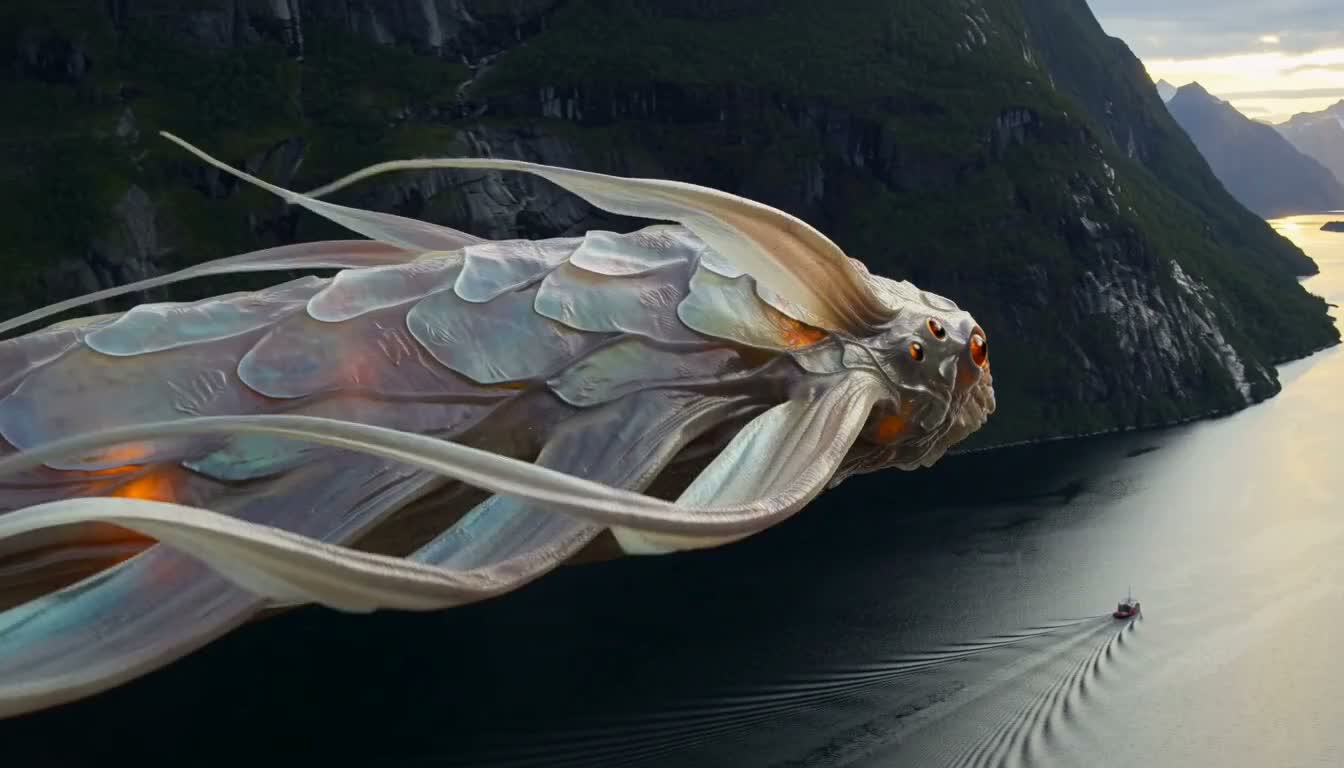
| h3-hrx · video with sound | krea2-hrx · image generation |
|---|---|
 |
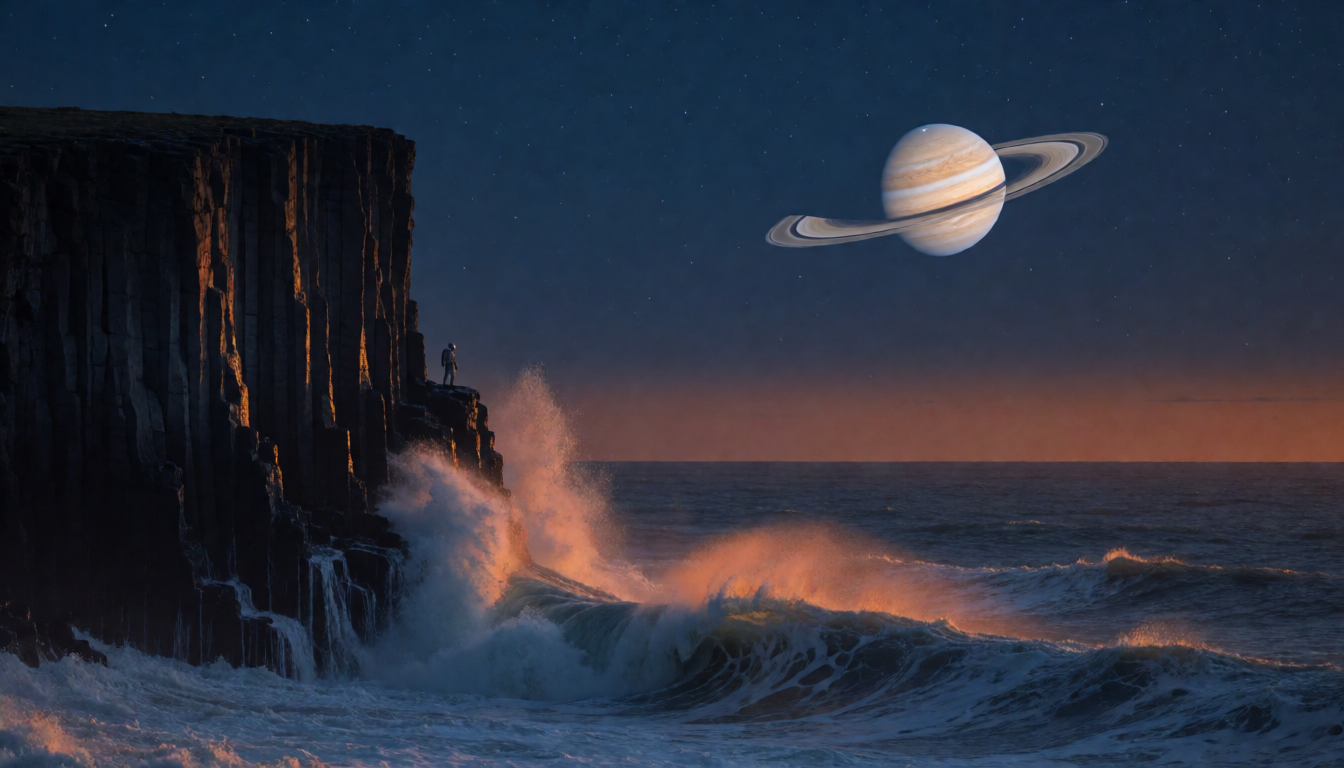 |
| Watch the 768p alien video | Explore the image gallery and prompts |
h3 generates this five-second 768p clip with sound in 35 min 59 s on Strix Halo. Complete native ComfyUI runs took 4 h 3 min 53 s with default attention and 43 min 33 s with built-in Comfy Kitchen INT8 attention: 6.78× and 1.21× h3 end-to-end speedups, respectively. h3 runs without the Python/PyTorch stack. See the full comparison, videos, and memory measurements.
The vision libraries also fit together: SCRFD supplies face landmarks to ArcFace for alignment and embeddings, while DINOv3 produces image vectors that an application can index with hrxdb.
Run independent work on both devices at once:
cargo run --release --features npu --example gpu_npu_parallel -- 16777216 1024 21 trace.jsonThis example combines a GPU vector transform with batched NPU matrix multiplication in one prepared graph. It checks both CPU references, compares sequential and concurrent completion times, and writes a Chrome/Perfetto trace of host-observed device activity. Setup and host data transfers are excluded from the timings; speedup depends on the workload.
The coordinated API is hrx::execution: owned shared buffers, checked kernel
contracts, inferred dependencies, reusable GPU/NPU graphs, and completion handles
that support blocking waits and Rust Future. hrx::gpu exposes the existing
low-level GPU API. Enable npu for native XDNA execution; Cargo builds need no native tools.
execution::Runtime runs at most one region per upload, compute, download and
NPU lane, even across independent graphs. Independent lanes can overlap when
the hardware permits; memory hazards remain ordered across every lane.
Increasing RuntimeOptions::max_submissions raises queue capacity only. The low-level
gpu::Stream::graph API batches independent dispatches and inserts dependency barriers.
See the GPU/NPU guide for the trust boundary, host mapping guards, shared native runtime setup, compiler pinning, and runnable hardware validation. The unified bundle includes both native device backends.
Requires Rust 1.91 or later.
[dependencies]
hrx = { package = "hrx-rs", version = "0.8.9", features = ["npu"] }
fn main() -> hrx::Result<()> {
let mut stream = hrx::Stream::open()?;
let buffer = stream.allocate(4096)?;
stream.upload(buffer.binding(), &[7; 4096])?;
let readback = stream.read(buffer.binding())?;
assert_eq!(readback.wait(&mut stream)?, vec![7; 4096]);
Ok(())
}Device selects a GPU, Stream orders work, and Buffer owns an allocation.
Streams share up to eight native queues per device by default, so native queue
capacity does not limit the number of streams. Each stream stays on one queue to
preserve its order. Assignment is round-robin, without priority or load awareness:
a long kernel or event wait can delay other streams assigned to that queue.
To tune this tradeoff, call device.set_stream_queue_count(count)? before
creating its first stream. The positive count is shared by clones and reopened
handles to the live device; device.stream_queue_count()? reads it. Queues are
created lazily, and an excessive count can still exhaust native queue resources.
See the queue pool measurements for throughput
and latency comparisons, their limitations, and the reproducible benchmark.
A buffer is bound to its device, not to the stream that allocated it: any stream
on that device may use it, and record_event/wait_event order conflicting
access. Unordered cross-stream use yields whichever bytes the device held.
Dispatches, fills and copies take &self; only staging-backed transfers and
synchronization need &mut. Kernel is Clone, retaining the executable.
Transfers, fills, copies and dispatch bindings use View. Borrow a whole buffer
with buffer.binding() and a subregion with view.slice(offset, length)?.
upload queues a transfer through owned staging; upload_blocking waits for it.
Ordinary GPU buffers use cacheable system memory; stream transfers perform the
required host cache maintenance. For direct host pointers, use
allocate_shared with external synchronization, or call Buffer::cache_control
before host reads and after host writes on ordinary allocations.
Events coordinate streams. Stream::graph records work as a dependency graph:
each operation names its predecessors, and &[] starts an independent branch.
Pass branch endings directly to their consumer. join collects dependencies
in an empty node, which adds a native partition and queue barrier. The runtime
can batch independent nodes without intervening barriers; the graph's shape
and GPU resource use determine whether execution overlaps. Loading kernels,
dispatching them, and sharing buffers across streams are unsafe: callers must
validate code, arguments, memory access, and synchronization.
When dependencies follow buffer hazards rather than an application-specific
schedule, use Stream::access_graph. Each dispatch binding declares
read(), write(), or read_write() and HRX infers the minimal byte-range
frontier. BufferPool provides bounded best-fit reuse for temporary device
allocations; a returned PooledBuffer recycles its allocation on drop.
hrx::loom::Compiler compiles Loom in process and caches artifacts.
Compiler::for_stream and Compiler::for_target select and share the matching
compiler profile.
Compiler::compile_all runs a batch across CompilerOptions::workers
workspaces and returns results in request order; Module::compile is blocking,
so a single-threaded caller never reaches that bound on its own. Compiler setup
and source pins are in patches/loom.
Resident inference libraries can use hrx::model::ModelSession instead
of rebuilding the same buffer arena and graph cache. It compiles a trusted batch
of embedded kernels, owns device-local or coherent allocations, infers graph
dependencies from each binding's declared Read, Write, or ReadWrite
access, reuses combined readback storage, and compares graph replay with direct
dispatch. Regions and kernel IDs are session-scoped and checked. Compiling
native source and recording its memory-access contract are explicit unsafe
boundaries; model parsing and shape validation remain application concerns.
For shared-context pipelines, hrx::inference::ModelContext owns the allocation,
compiler and scheduling domain. ModelSession::freeze produces immutable shared
weights/code; ModelDefinition::prepare creates bounded private inference slots.
Owned DeviceTensor views carry checked metadata, producer completions and slot
leases, so downstream consumers cannot observe recycled output storage.
For a composed pipeline, validate each stage with ModelDefinition::fragment
and call ModelFragment::record on the same execution::Graph, passing one
stage's output tensors directly to the next. Prepare that graph once. Adjacent
GPU stages become one native graph without intermediate copies or submissions.
Image normalization, patchification, resize, affine sampling, RGB views and
compositing, similarity fitting and finite-value checks also expose recordable
fragments. PreparedModel::prepare takes a slot
factory returning InferenceGraph { inputs, outputs, graph }: each slot owns
the actual pipeline bindings, including sliced or in-place IO. Host transfer
storage is allocated on first upload/readback and reused thereafter; device-only
pipelines allocate none. Independent slots must not share writable IO.
Audited fragments can opt into reuse_private_scratch: private activation
storage is reused across stages in the same graph, while outputs, inputs and
weights remain distinct. The fragment must initialize every temporary byte it
reads; the graph's memory hazards order reuse after earlier readers. Independent
slots never share this workspace. ModelSlot::submit_host_with publishes packed
host inputs directly into reserved staging without an extra host assembly buffer.
Shared operations need not all execute on the GPU. TensorOps::gather_rows
accepts checked host-selected indices while keeping complete rows on-device.
It preserves dtype bits, duplicates and order, uses bounded power-of-two shape
caches, and retains private output slots through returned tensor views. This
supports CPU sorting/selection between GPU stages without a full tensor readback.
PreparedModel supports device submissions, reusable host staging, capacity
futures and explicit readback. Upload, compute and download lanes share hazard
tracking. Graph::gpu_scoped integrates owned native clients at an audited boundary.
For stream-bound models with borrowed inputs and progress callbacks,
execution::NativeSession reserves the shared compute lane on the calling thread.
Its stage boundary fences errors and panics, quarantines owners on uncertain
completion, and records host-observed latency without copying host inputs.
It uses private storage; tracked-buffer integrations use Graph::gpu_scoped.
It does not turn a synchronous stage into asynchronous inference or split that
stage's native transfers onto separate lanes.
hrx::image provides resident RGB normalization, patchification, and FP32 affine
RGB sampling with black borders and ties-to-even byte rounding. Affine plans
accept one resident image and runtime inverse matrices for multiple crops;
prepared plans and private slots are reused across changing matrices.
PlanCache bounds concurrent shape preparation with idle-only LRU eviction;
the opt-in ResidencyManager adds declared byte budgets and persistent pins.
load_budgeted caches units whose native allocations hold their own charges,
allowing private workspace growth while leased and idle-only LRU eviction.
Passing its budget() to RuntimeOptions::memory_budget charges tracked weights,
scratch and transfer staging against the same ceiling before allocation. Aliases,
queued work and quarantined storage retain those charges. Native storage outside
the coordinated runtime is covered when its stream uses with_memory_budget.
NPU kernels loaded through that runtime also charge their instruction buffers.
NPU storage uses the tracked runtime budget; imported shared storage retains
the backing owner's charge without double counting.
ModelSession::in_context applies that policy during native loading as well;
freezing into the same budget does not charge weights twice. Otherwise adopted
buffers are charged only at adoption. Do not declare the same bytes twice in a
cached resource and its budgeted allocations. Requested buffer extents exclude
native allocator rounding and compiler/code-object memory.
Runtime statistics include transfer bytes and live/peak tracked memory. Optional
bounded traces and completion profiles measure host-observed latency, not GPU
timestamps.
hrx::artifacts contains the common model-file boundary. hf::Resolver checks
the standard Hugging Face cache before downloading and supports pinned revisions,
offline operation, progress policy, and SHA-256 verification. onnx::Model
provides owned graph indexes and checked attributes/tensor decoding without
exposing protobuf types. safetensors::FileView reads or memory maps a file,
indexes checked tensor ranges, and provides page-advice hooks for large models.
These dependencies are always available; they are not split behind features.
Two different things are called the target, and they are chosen independently.
The profile target is hrx::Target — the architecture a device reports and
the one the compiler emits for. It is a bare architecture key such as gfx1151;
Target::new rejects generic names. The source-level target is what Loom
source writes as amdgpu.target<...>, which does accept generic names such as
gfx11-generic and compiles fine under a bare profile. A generic source target
has no low-asm contract, so hand-written asm needs a bare architecture there
too.
GPU execution requires Linux x86_64, the AMD amdgpu/KFD kernel driver,
the system C/C++ runtimes and libatomic, and access to /dev/kfd and the render
device. You do not need a system ROCm SDK or PyTorch installation: HRX supplies
its own pinned native runtime and the Loom compiler.
Install the CLI, including optional NPU support:
cargo install hrx-rs --version 0.8.9 --locked --features npu
hrx prepare
hrx doctor
hrx prepare downloads and verifies the unified archive pinned in
bundle.json. GPU, compiler, and NPU APIs also provision it on first
use. For offline installation, run HRX_OFFLINE=1 hrx prepare native.tar.gz
with the matching archive. Linux drivers, firmware, and permissions remain host
prerequisites. The bundle targets Ubuntu 26.04, requiring glibc 2.43+ and compatible
C/C++ runtimes. See the native setup guide.
| Setting | Purpose |
|---|---|
HRX_RUNTIME_DIR |
Use a trusted local directory of native libraries, bypassing bundle verification |
HRX_BUNDLE_MANIFEST |
Use a local JSON manifest for a mirror or custom bundle |
HRX_OFFLINE |
Disable network provisioning when set |
HRX_AMDF_LIBRARY |
Override the path to libamdf.so |
HRX_FABRIC_LIBRARY |
Override the path to libhrx_fabric.so |
HRX_LOOM_LIBRARY |
Override the path to libloomc.so |
Caches live at $XDG_CACHE_HOME/hrx, or $HOME/.cache/hrx when that is unset,
per the XDG Base Directory specification; a relative XDG_CACHE_HOME is ignored
as the specification requires. The runtime lock lives in $XDG_RUNTIME_DIR.
Compiled kernels go to one cache under that root, shared by every consumer on the
machine. Artifacts are content-addressed — the key covers compiler identity,
source, export, target and canonical configuration, and every hit re-verifies the
bytes against their recorded digest — so there is nothing a per-model location
could distinguish, and two models that compile the same kernel compile it once.
hrx gc [DAYS] evicts runtime bundles bundle.json does not pin and kernels not
read for DAYS (default 30), by access time, so entries written by any release are
dated the same way.
The only optional Cargo feature is npu, enabling NPU execution
and cross-device probes. GPU execution, Loom compilation, downloads and the
hrx CLI are always available; native libraries still load only on first use.
HRX_OFFLINE=1 controls offline provisioning independently of Cargo features.
The CLI's run subcommand launches a compiled kernel and dumps its buffers.
Stream is the execution API; dispatch takes explicit Constants.
cargo test --all-features
cargo clippy --all-features --all-targets -- -D warnings
cargo doc --all-features --no-deps --open
Use scripts/check-feature-matrix.sh for feature checks. See
CHANGELOG.md for API changes and THIRD-PARTY.md
for native distribution status. Original Rust code is MIT licensed; NPU-derived code retains its
upstream licenses.