
Find out if a quantized AI model will run on your GPUs, before you download it.


Try it in your browser · Quick start · What it checks · Accuracy · Docs
A quantized checkpoint can be 40 to 400 GB. You pull it onto your GPU nodes, start the engine, and only then learn that your GPU has no kernel for its format, or that its tensors won't split across your GPUs, or that it doesn't fit. quantpreflight tells you first, from a few hundred KiB of config files and tensor headers.
- Answers in seconds. It reads headers, not weights: 887 KiB for a 38.74 GiB checkpoint.
- Needs no GPU. There's no PyTorch and no CUDA, and no dependencies at all on Python 3.11+. It runs on a laptop or in CI.
- Checks the whole mix. 16 rules cover the model, format, engine, GPU, and GPU count together, because that's where most failures come from.
- Tells you what works. It gives you the GPU count and context length that start, with the
vllm servecommand to run.suggestfinds the quantized versions of a model that run on your GPUs. - Tested on real hardware. It predicted 26 of 27 real vLLM loads on Tesla T4, and it has scanned 505 public models with no crashes. See the results.
- Finds known vulnerabilities.
--engine-versionchecks your vLLM or SGLang version against published advisories. - Fits your workflow. Use the CLI, a GitHub Action, a pre-commit hook, SARIF output, or the browser scanner.
Install it from PyPI. It needs Python 3.10 or newer:
pip install quantpreflightThen name a model and where you plan to run it:
quantpreflight check nvidia/Qwen3-8B-FP4 --gpu H100quantpreflight v0.4.0
Source: nvidia/Qwen3-8B-FP4
Architecture: Qwen3ForCausalLM (safetensors)
Quantization: nvfp4 4-bit g16 nvfp4-pack-quantized
Weights: 5.96 GiB across 2 file(s), 1227 tensors
Headers read: 301.0 KiB (zero weight bytes downloaded)
Target: engine=vllm, gpu=H100, tp=1
Est. VRAM: 8.24 GiB / GPU (weights, runtime, and KV cache)
Findings: 1 (1 critical)
------------------------------------------------------------------------
[1] CRITICAL QPF004: NVFP4 requires Blackwell (sm_100+), target is H100 (sm_90)
Location: config.json
Detail: Checkpoint uses NVFP4 4-bit floating-point quantization, which is not supported on H100 (sm_90).
Fix: Deploy NVFP4 checkpoints on Blackwell GPUs (B200/GB10/RTX5090) or use AWQ/GPTQ/FP8.
Setup: no --tp or context length makes this start.
QPF004 needs a different checkpoint, GPU, or engine.
Find one that works: quantpreflight suggest nvidia/Qwen3-8B-FP4 --gpu H100
So find one that works. suggest scans the quantized versions of the model on Hugging Face and ranks the ones that start:
quantpreflight suggest nvidia/Qwen3-8B-FP4 --gpu H100 --limit 4quantpreflight v0.4.0
Versions of Qwen/Qwen3-8B for vLLM on H100, tp=1:
Setup Model Format Weights Details
ready Qwen/Qwen3-8B unquantized (BF16) 15.26 GiB tp=1, 40960 tokens
ready Qwen/Qwen3-8B-FP8 fp8 8-bit block-fp8 8.79 GiB tp=1, 40960 tokens
ready Qwen/Qwen3-8B-AWQ awq 4-bit g128 gemm 5.68 GiB tp=1, 40960 tokens
blocked nvidia/Qwen3-8B-NVFP4 nvfp4 4-bit g16 nvfp4-pack-quantized 5.96 GiB QPF004
blocked unsloth/Qwen3-8B-unsloth-bnb-4bit bitsandbytes 4-bit nf4 6.97 GiB QPF011
Best pick: Qwen/Qwen3-8B, the highest precision that starts.
Run: vllm serve Qwen/Qwen3-8B
When a setting is all that's wrong, check says which one to change. Here a 32B model is too big for one L4:
Setup: it starts with these changes.
  - Use --tp 2 instead of 1, so the weights fit in memory.
  Fits 32768 tokens per request at tp=2.
  Run:  vllm serve Qwen/Qwen2.5-32B-Instruct-AWQ --tensor-parallel-size 2
On the machine you'll serve from, --gpu auto reads its GPUs and --engine-version auto reads the installed vLLM or SGLang.
It takes a Hugging Face repo ID, a direct URL, a local folder, or a single .safetensors or .gguf file:
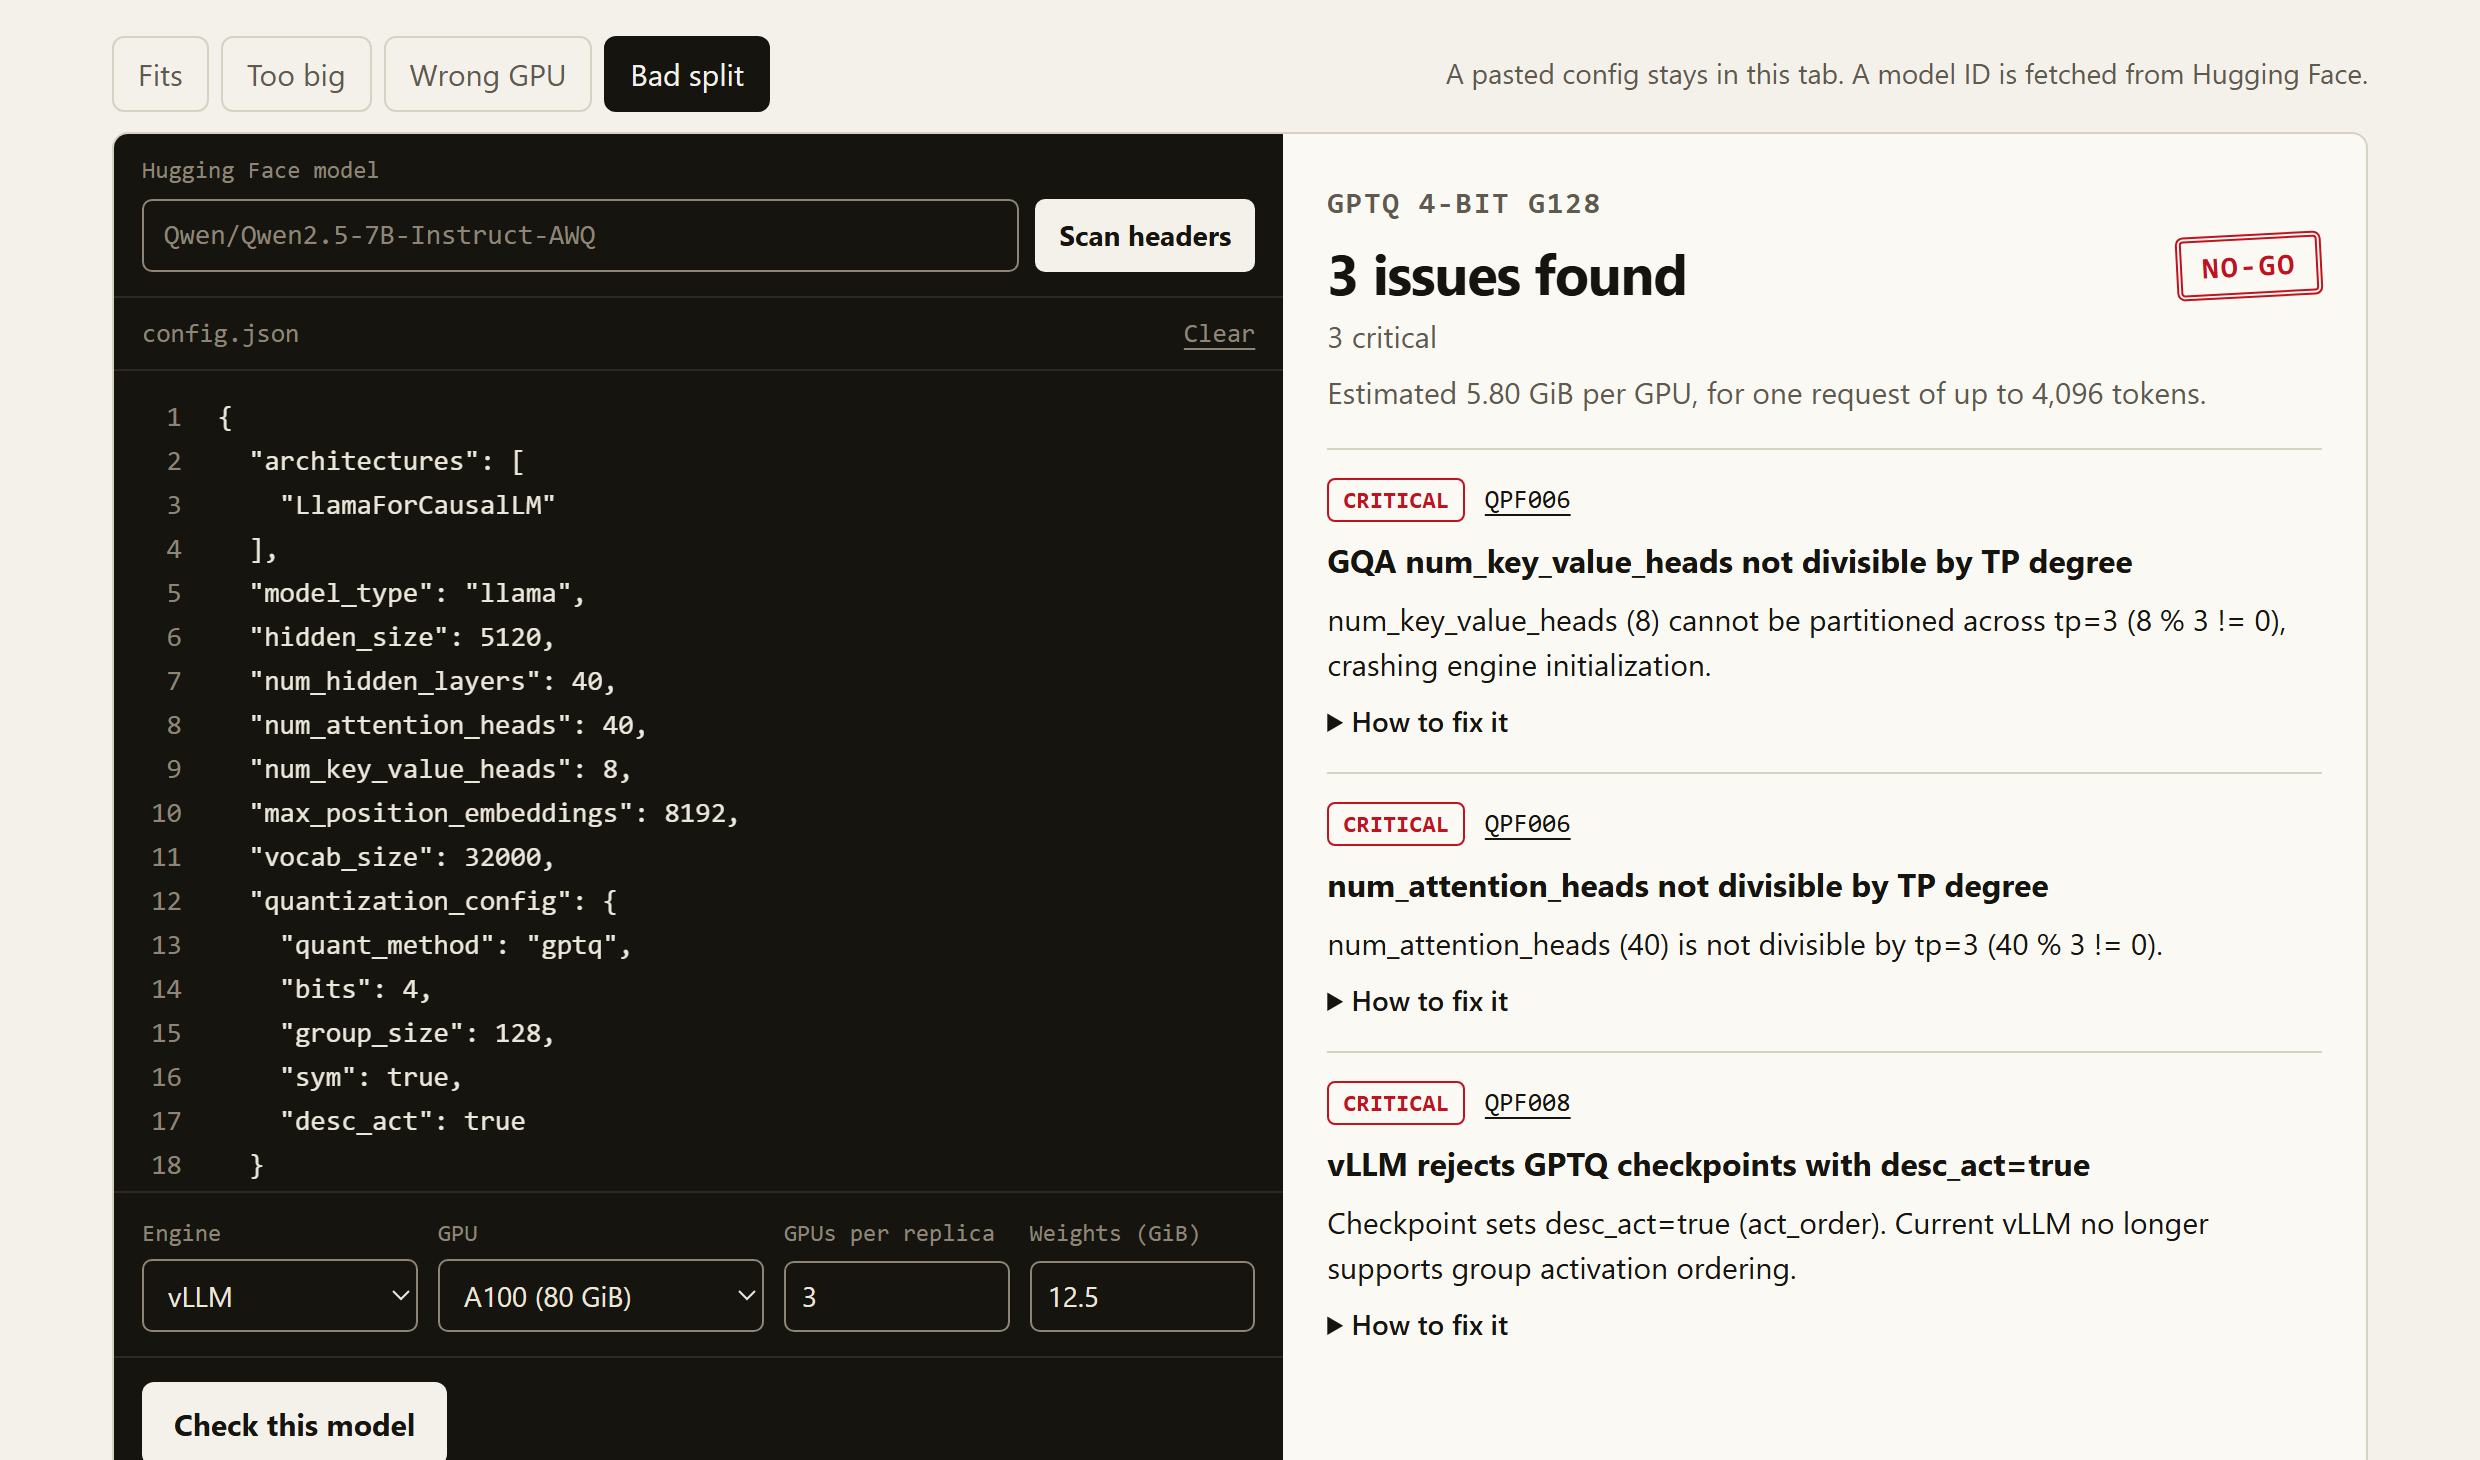
quantpreflight check Qwen/Qwen2.5-7B-Instruct-AWQ --engine vllm --gpu H100 --tp 4
quantpreflight check ./models/deepseek-r1-fp8 --gpu L40S --tp 8
quantpreflight check ./models/llama-3-8b-q4_k_m.gguf --engine llamacpp --gpu L4
Want to see it find problems? This repository has a deliberately broken sample that holds headers only:
git clone https://github.com/layer8labs8/quantpreflight.git
quantpreflight check quantpreflight/tests/fixtures/broken-model --gpu H100 --tp 4
The usage guide covers every option. Set HF_TOKEN to scan gated models.
| Question | Why it matters | Rule |
|---|---|---|
| Were sensitive layers quantized too hard? | Norms and vision towers lose too much at low precision, and a quantized router can hurt quality silently. | QPF001 |
| Can a token fall off the end of the embedding table? | A token ID past the last row ends in a GPU assert. This is the checkpoint-side relative of CVE-2026-115916. | QPF002 |
| Will the model know when to stop? | If the stop token differs between files, it can generate until max_tokens. | QPF003 |
| Does your GPU have the kernels for this format? | NVFP4 needs Blackwell, ModelOpt needs sm_80, block FP8 is limited on sm_89, and FP8 may fail on GPUs without FP8 cores. | QPF004 |
| Does this mix trigger a known silent bug? | Some engine, GPU, and format mixes corrupt output or ignore your flags with no error. | QPF005 |
| Can the heads and experts split across your GPUs? | Attention heads, KV heads, and MoE experts must divide evenly by --tp. | QPF006 |
| Do the shards still fit the kernel after splitting? | Per-GPU sizes must stay multiples of group_size, the 128x64 Marlin tile, and the FP8 block. | QPF007 |
| Does this GPTQ model use desc_act? | vLLM rejects it outright, and other engines pay for extra gathers across GPUs. | QPF008 |
| Is every shard really there? | Missing shards, dangling tensors, duplicates, and wrong MTP draft shapes fail at load. | QPF009 |
| Does the config match the weights? | Packed tensors with no quantization_config, or the reverse, load wrongly or waste memory. | QPF010 |
| Can this engine read this format? | Safetensors on llama.cpp and GGUF on TensorRT-LLM fail to load, and 1-bit or 2-bit GGUF on vLLM or SGLang is often unsupported or slow. | QPF011 |
| Will it fit in GPU memory? | Weights, runtime overhead measured on real GPUs, and the KV cache, with DeepSeek MLA, sliding windows, and Mamba state counted properly. | QPF012 |
| Are the byte offsets in the file sane? | Overlapping, inverted, or truncated spans mean a corrupt or incomplete file. | QPF013 |
| Will loading it run someone else's code? | Pickle weights and trust_remote_code can execute arbitrary code on your host. | QPF014 |
| Does your engine version have known vulnerabilities? | With --engine-version, your vLLM or SGLang version is checked against published advisories. | QPF015 |
| Is the context longer than the model allows? | vLLM refuses a --context-len above max_position_embeddings. | QPF016 |
Run quantpreflight explain QPF006 for the details of any rule.
| Area | Supported |
|---|---|
| Formats | AWQ, GPTQ, Compressed-Tensors, FP8, NVFP4, MXFP4, Marlin, AutoRound, bitsandbytes, BitNet, MLX, GGUF, Safetensors |
| Engines | vLLM, SGLang, TensorRT-LLM, llama.cpp |
| NVIDIA GPUs | T4, A10G, A100-40GB, A100, L4, L40S, RTX4090, H100, H200, B200, RTX5090, GB10 |
| AMD GPUs | MI250X, MI300X, MI325X |
| Model families | Llama, Mistral, Qwen, DeepSeek, Gemma, Phi, GLM, Mamba and hybrids, with a generic fallback for the rest |
- uses: layer8labs8/quantpreflight@v0.4.0
  with:
    target: ./exported-checkpoint
    engine: vllm
    gpu: H100
    tp: "4"
    fail-on: high
The usage guide shows SARIF upload to the Security tab and a pre-commit hook.
Every result here can be reproduced from this repository. The accuracy report has the full tables.
| Check | Result |
|---|---|
| Real vLLM 0.33 loads on Tesla T4 | 26 of 27 predicted correctly |
| Suggested setups on Tesla T4 | 9 of 9 predicted correctly |
| Public Hugging Face models scanned | 505, with 0 crashes |
| Labelled benchmark | 96.9% recall, 100% precision on 132 cases |
| Automated tests | About 7,000, on Linux, Windows, and macOS |
We wrote the benchmark ourselves, so treat it as a regression check. Only T4 GPUs have been tested so far.
Run it before the download. These tools do different jobs:
| Tool | Best at |
|---|---|
| Your engine's startup checks | The final word, once the weights are on the node |
| VRAMScout | Working out how much context fits in free VRAM |
| vramfit | Picking a quantization recipe |
| picklescan and ModelScan | Inspecting what's inside pickle files, which quantpreflight only flags and never opens |
quantpreflight |
Checking format, kernels, sharding, tokens, files, and memory together, before you download |
A scanner finds known problems, not proof. A clean report doesn't mean the model will load or answer well, and a finding may not apply to your exact engine version.
- It never reads weight values, so it can't see NaNs or measure quality loss.
- Its GPU rules were checked on T4 only. Other GPUs rest on vendor docs and engine issues until someone tests them.
- Its compatibility tables can fall behind a new engine release.
- The memory estimate assumes one request at a time unless you pass
--concurrency. Its overhead was fitted on T4. - It only checks your engine version if you pass
--engine-version, and only vLLM and SGLang have advisory data. - The browser scanner reads public Safetensors models or a pasted
config.json. GGUF, gated models, and local folders need the command line.
Does it download the model? No. It reads config files plus the header at the start of each weight file. A scan never fetches weight data.
Do I need a GPU or PyTorch? No. Pass the GPU you plan to use with --gpu, and it checks against a built-in table.
It flagged a model that runs fine. Is that a bug? It might be. Please open a report. False alarms are the most useful feedback we get.
Is my token safe? HF_TOKEN goes only to Hugging Face, and it's removed if a download redirects to another host. See SECURITY.md.
Only Tesla T4 has been checked against real loads so far. If you can run vLLM on another GPU, one run of tools/gpu_check.py shows where the rules are right and where they're wrong. GPU testing explains how, and the help wanted issues list the GPUs we need most.
Most contributions are one small TOML file. Adding a model family or a GPU takes no Python and no GPU. Start from an existing file in architectures/ or hardware/, and see CONTRIBUTING.md.
If this project helped you, I'm really glad. If you'd like to support it, you can send a crypto tip. If not, that's completely okay.