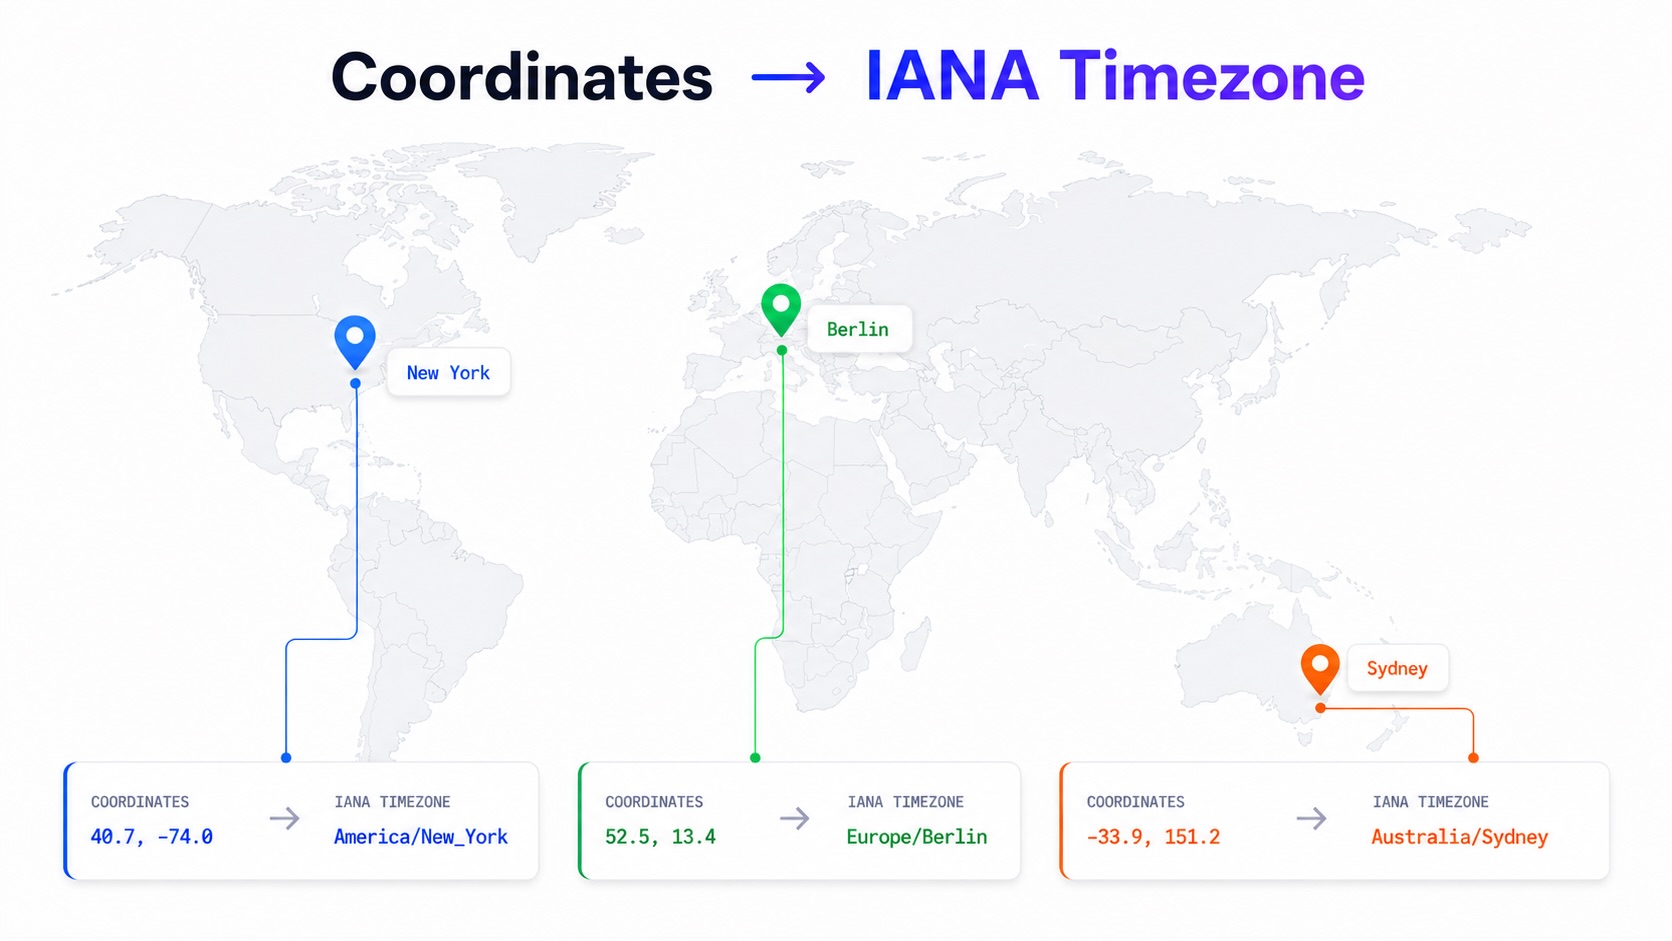
Offline timezone lookup for WGS84 coordinates, with no polygon simplification - so the answer stays correct at timezone borders.





In comparison to other alternatives this package aims at maximum accuracy around timezone borders while offering fast lookup performance and compatibility with many (Python) runtime environments. It combines preprocessed polygon data, H3-based spatial shortcuts, and optional acceleration via Numba or a clang-backed point-in-polygon routine.
pip install timezonefinderThis compiles a small C extension for the point-in-polygon test. The optional Numba extra (pip install timezonefinder[numba]) replaces that extension with a JIT-compiled kernel and takes precedence over it - a dispatch rule, not a promise of more speed. The acceleration path comparison measures all three against each other and is regenerated with every report; check it before adding the extra - which also costs every process more resident memory than the packaged data.
The timezone boundary data is installed automatically as the separate timezonefinder-data distribution, so that a new dataset ships without a new timezonefinder release. Pin it to hold a deployment to one dataset - the release history lists the versions to choose from: pip install timezonefinder "timezonefinder-data==<version>". A dataset update can change the answer for a coordinate, so pin it when a result has to stay reproducible across deployments - result stability covers what can change and what cannot.
# use the global function for convenience:
from timezonefinder import timezone_at

tz = timezone_at(lng=13.358, lat=52.5061)  # 'Europe/Berlin'


# For improved performance and control, reuse one instance for the whole job.
# The context manager releases its coordinate data even if the job raises:
from timezonefinder import TimezoneFinder

with TimezoneFinder(in_memory=True) as tf:
    tz = tf.timezone_at(lng=13.358, lat=52.5061)  # 'Europe/Berlin'

    # Many coordinates at once, one array per axis - ids for a caller that maps
    # them itself, names for one that does not:
    lngs = [13.358, 2.3522]
    lats = [52.5061, 48.8566]
    zone_ids = tf.timezone_ids_at(lngs=lngs, lats=lats)
    names = tf.timezone_names_at(lngs=lngs, lats=lats)
    # ['Europe/Berlin', 'Europe/Paris']
Note: This library uses the full original timezone dataset with all >440 timezone names, providing full localization capabilities and historical timezone accuracy. For applications that prefer a smaller memory footprint, the reduced "timezones-now" dataset is available via the update_data.sh script (cf. Documentation).
A lookup scales the coordinates to 32-bit integers (x 10^7, ~1.1 cm steps), finds the point's H3 hexagon at resolution 4, and reads a precomputed shortcut for that cell. Most cells are covered by a single timezone, so the answer is returned immediately with no geometry touched at all. Only an ambiguous cell falls through to the polygons it lists: bounding-box rejection first, then a ray-casting point-in-polygon test - holes before the outer ring, since holes are smaller and can reject the polygon outright.
The central trade-off: the boundary polygons are never simplified, so border accuracy is limited only by the source dataset. The H3 index is what makes carrying full-resolution geometry affordable.
Since the dataset includes ocean zones, every coordinate on earth matches some timezone - use
timezone_at_land() when you need to tell land from sea.
The dataset also contains genuinely overlapping zones, so a coordinate can match more than one -
timezone_at() picks one of them, and timezones_at() returns all of them.
Hundreds of thousands of lookups per second on a single core for uniformly random query points. The exact figure depends on the acceleration backend, the machine and the dataset version, so the benchmark reports below carry it - each states the configuration it was measured in - rather than this page, which would go stale.
The point-in-polygon routine has three interchangeable backends, selected at import time: a clang-compiled C extension (built automatically when a compiler is available), Numba JIT compilation (preferred when the optional dependency is installed), and pure Python. All three return identical answers - a missing compiler costs speed, never results. Which is fastest is measured, not assumed: see the acceleration path comparison.
- benchmark trend chart - appended to on every push to
master - benchmark reports - lookup, point-in-polygon, initialization and memory
- benchmarking methodology - how these numbers are produced and what they can and cannot tell you
- Architecture - the lookup pipeline, the acceleration backends, and the ceilings this package deliberately does not exceed
- Data Format - binary layouts, coordinate scaling and the H3 index
- Benchmarking Methodology - the measurement design and where every threshold comes from
- Testing philosophy - the tests that exist because a rule needed a failure mode, plus the property-based suite and the version/backend matrix
- How it ships - abi3 wheels, three libc targets, and the checks that stop a broken wheel reaching PyPI
- Alternatives - the trade-offs against
tzfpy, and when to choose it instead - Changelog
Alternative: Need maximum speed at the cost of accuracy? Check out tzfpy - a fast and lightweight alternative based on Rust.
Looking for maintainers. Reach out if you want to contribute!
Contribution guidelines, the development workflow and the testing/benchmarking gates are documented in CONTRIBUTING.md.
timezonefinder is licensed under the MIT license.
The data ships in the separate timezonefinder-data distribution and is licensed under the ODbL license, following the base dataset from evansiroky/timezone-boundary-builder.