
DECODING BRAIN SIGNALS AND BEYOND WITH GENERATIVE AI: INTRODUCING M4 - A FRAMEWORK FOR META-ALIGNED MULTI-MODAL MULTI-TASK LEARNING
IMPORTANT UPDATE: THIS REPO WAS BUILT UPON OPEN SOURCE CODE WHICH WAS PROVEN TO HAVE UNDERLYING ISSUES (see https://github.com/MikeWangWZHL/EEG-To-Text). PLEASE EXERCISE CAUTION WHEN USING THE CODE HERE. FOR THIS REASON, THIS REPOSITORY WILL NOW BE ARCHIVED.
- This repository is currently under development. All code is subject to final changes, and the author does not guarantee that the code is organized in any way, or immediately runnable.This is an official implementation of M4, a universal Meta-Aligned Multi-Modal Multi-Task (4M) framework capable of training any model for the 4M setting with the correct modifications. This current example implementation of M4 is set for the task of decoding EEG signals.
Since the days of Turing, a longstanding goal of artificial intelligence has been to understand the
intricate workings of the human brain. As such, we explore the task of decoding EEG signals
using a 4M paradigm - one that is Meta learned, Multi-Modal, and Multi-task. While state-of-the-art
(SOTA) Large Language Models (LLMs) such as LLaMA-2 and GPT-4 have recently been augmented
with some multimodal capabilities alongside their formidable Natural Language Processing (NLP)
performance, they do not readily fit into a true 4M setting.
Unlike GPT-4 which employs DALL-E 3 in a somewhat plug-and-play fashion, we utilize cross-modal
alignment techniques to more tightly integrate multiple modalities into a unified 4M framework.
Through comprehensive benchmarking, we address alignment method limitations around noisy data,
low-resource tasks, and generalizability. We further assemble a novel EEG analysis dataset by
consolidating several existing ones.
Based on curated data, we develop an encompassing 4M training paradigm and employ it to construct
To set up the environment, run either sh pip_install.sh or the following command:
pip install -q scipy
pip install -q h5py
pip install -q matplotlib
pip install -q torch torchvision torchaudio
pip install -q transformers
pip install -q fuzzy_match
pip install -q nltk
pip install -q rouge
pip install -q diffusers
pip install -q tensorboard
pip install -q tqdm
pip install -q accelerate
pip install -q optuna optuna-dashboard
Our project relies on CUDA at the moment, so please also take time to either modify your code to use the hardware you have available, and/or ensure that your cuda driver and the current pytorch version do not clash. For the code to run with the settings described within the paper, you will require at least 4 x NVIDIA A100 80GB GPUs.
The data of our code is preprocessed and can be loaded via the command sh LoadItemsGdrive.sh. However, the command may not work in some environments, so you may wish to navigate to the DreamDiffusion and/or EEG-To-Text Githubs and follow their instructions there. After that is done, please also run sh preprocess/preprocess.sh to preprocess some of the necessary data.
Below is a list of the tasks that we have implemented:
- EEG-TEXT MATCHING (ETM, Pretrained)
- EEG-IMAGE MATCHING (EIM, Pretrained)
- EEG-TEXT GENERATION (TEXT-GEN)
- EEG-IMAGE GENERATION (IMG-GEN)
- EEG-SENTIMENT CLASSIFICATION (SENT-CLASS)
- EEG-IMAGE CLASSIFICATION (IMG-CLASS)
- Modify the code within the necessary files to suit your needs.
- Run
python3 ./training/pretrain.pyto start the pretraining. - Run
python3 ./training/continue_from_pretrain.pyto start training on the other tasks.
- Modify the code within the necessary files to suit your needs.
- Run
python3 ./training/training.pyto start the pretraining.
- Modify the code within the necessary files to suit your needs.
- Run
python3 ./evaluator/{task_name}.pyto start the pretraining where{task_name}is the task you wish to evaluate.
Below are some of results we present in our paper, which has not yet been released.


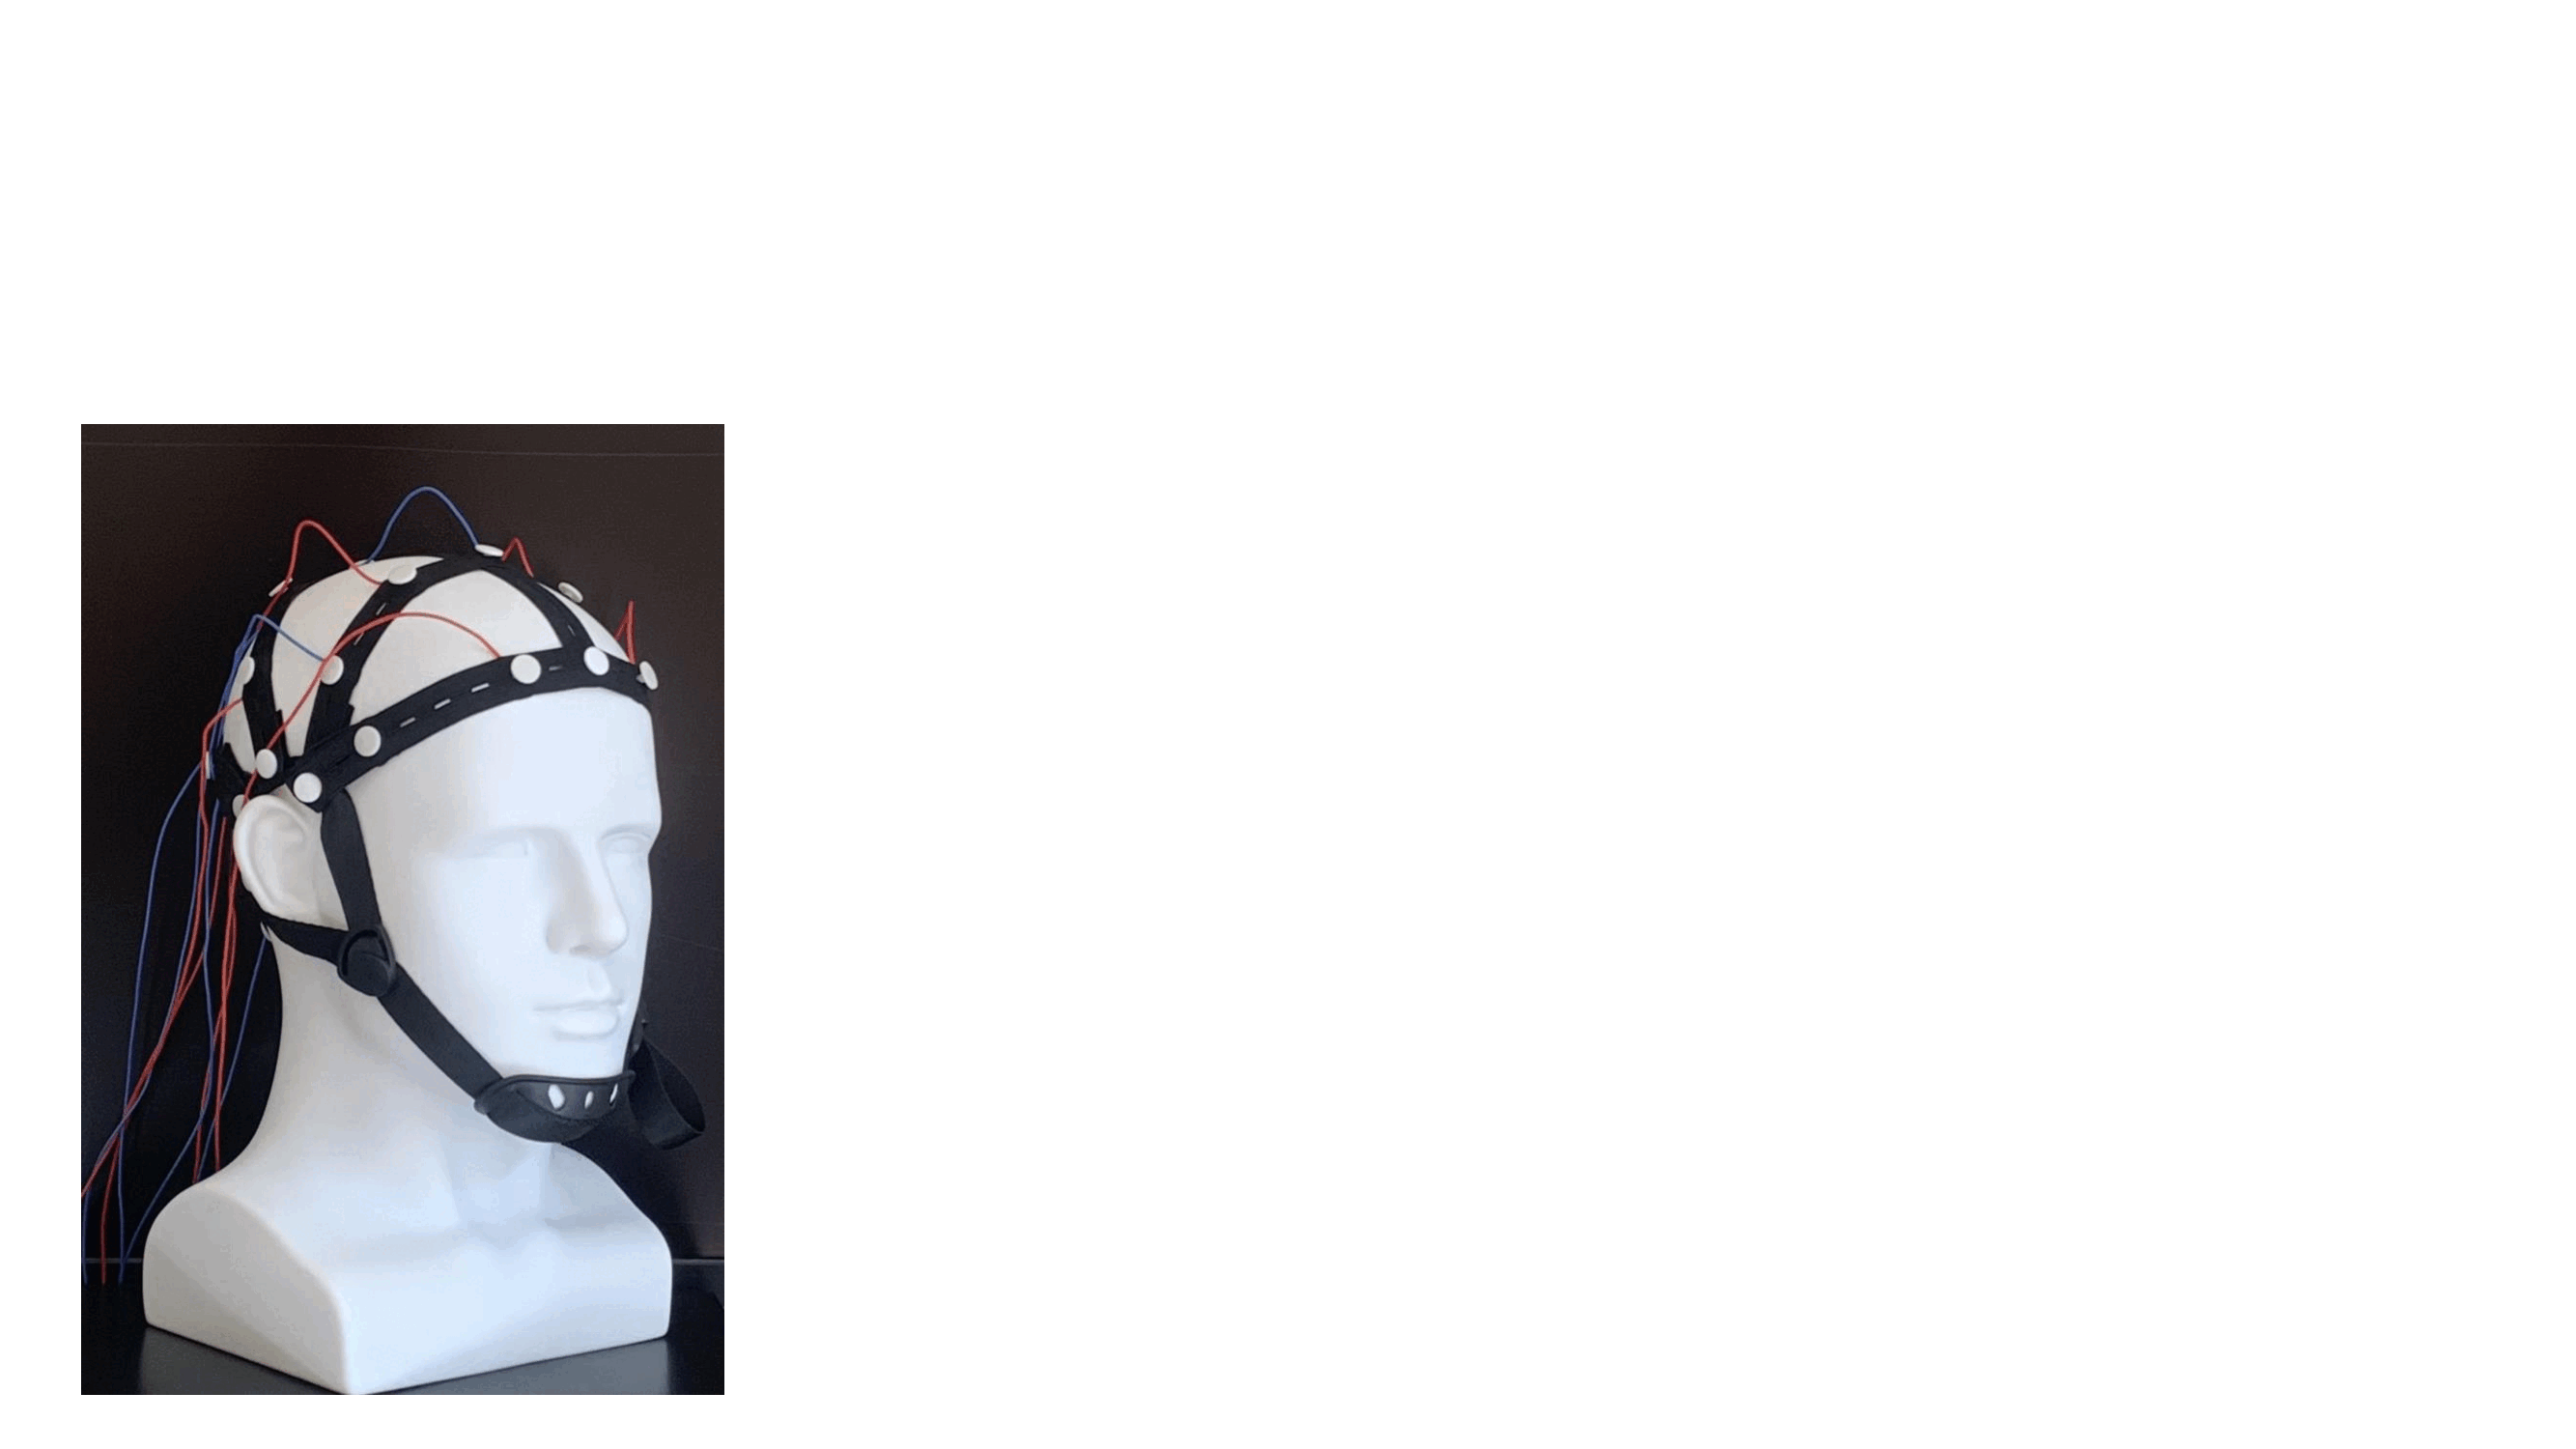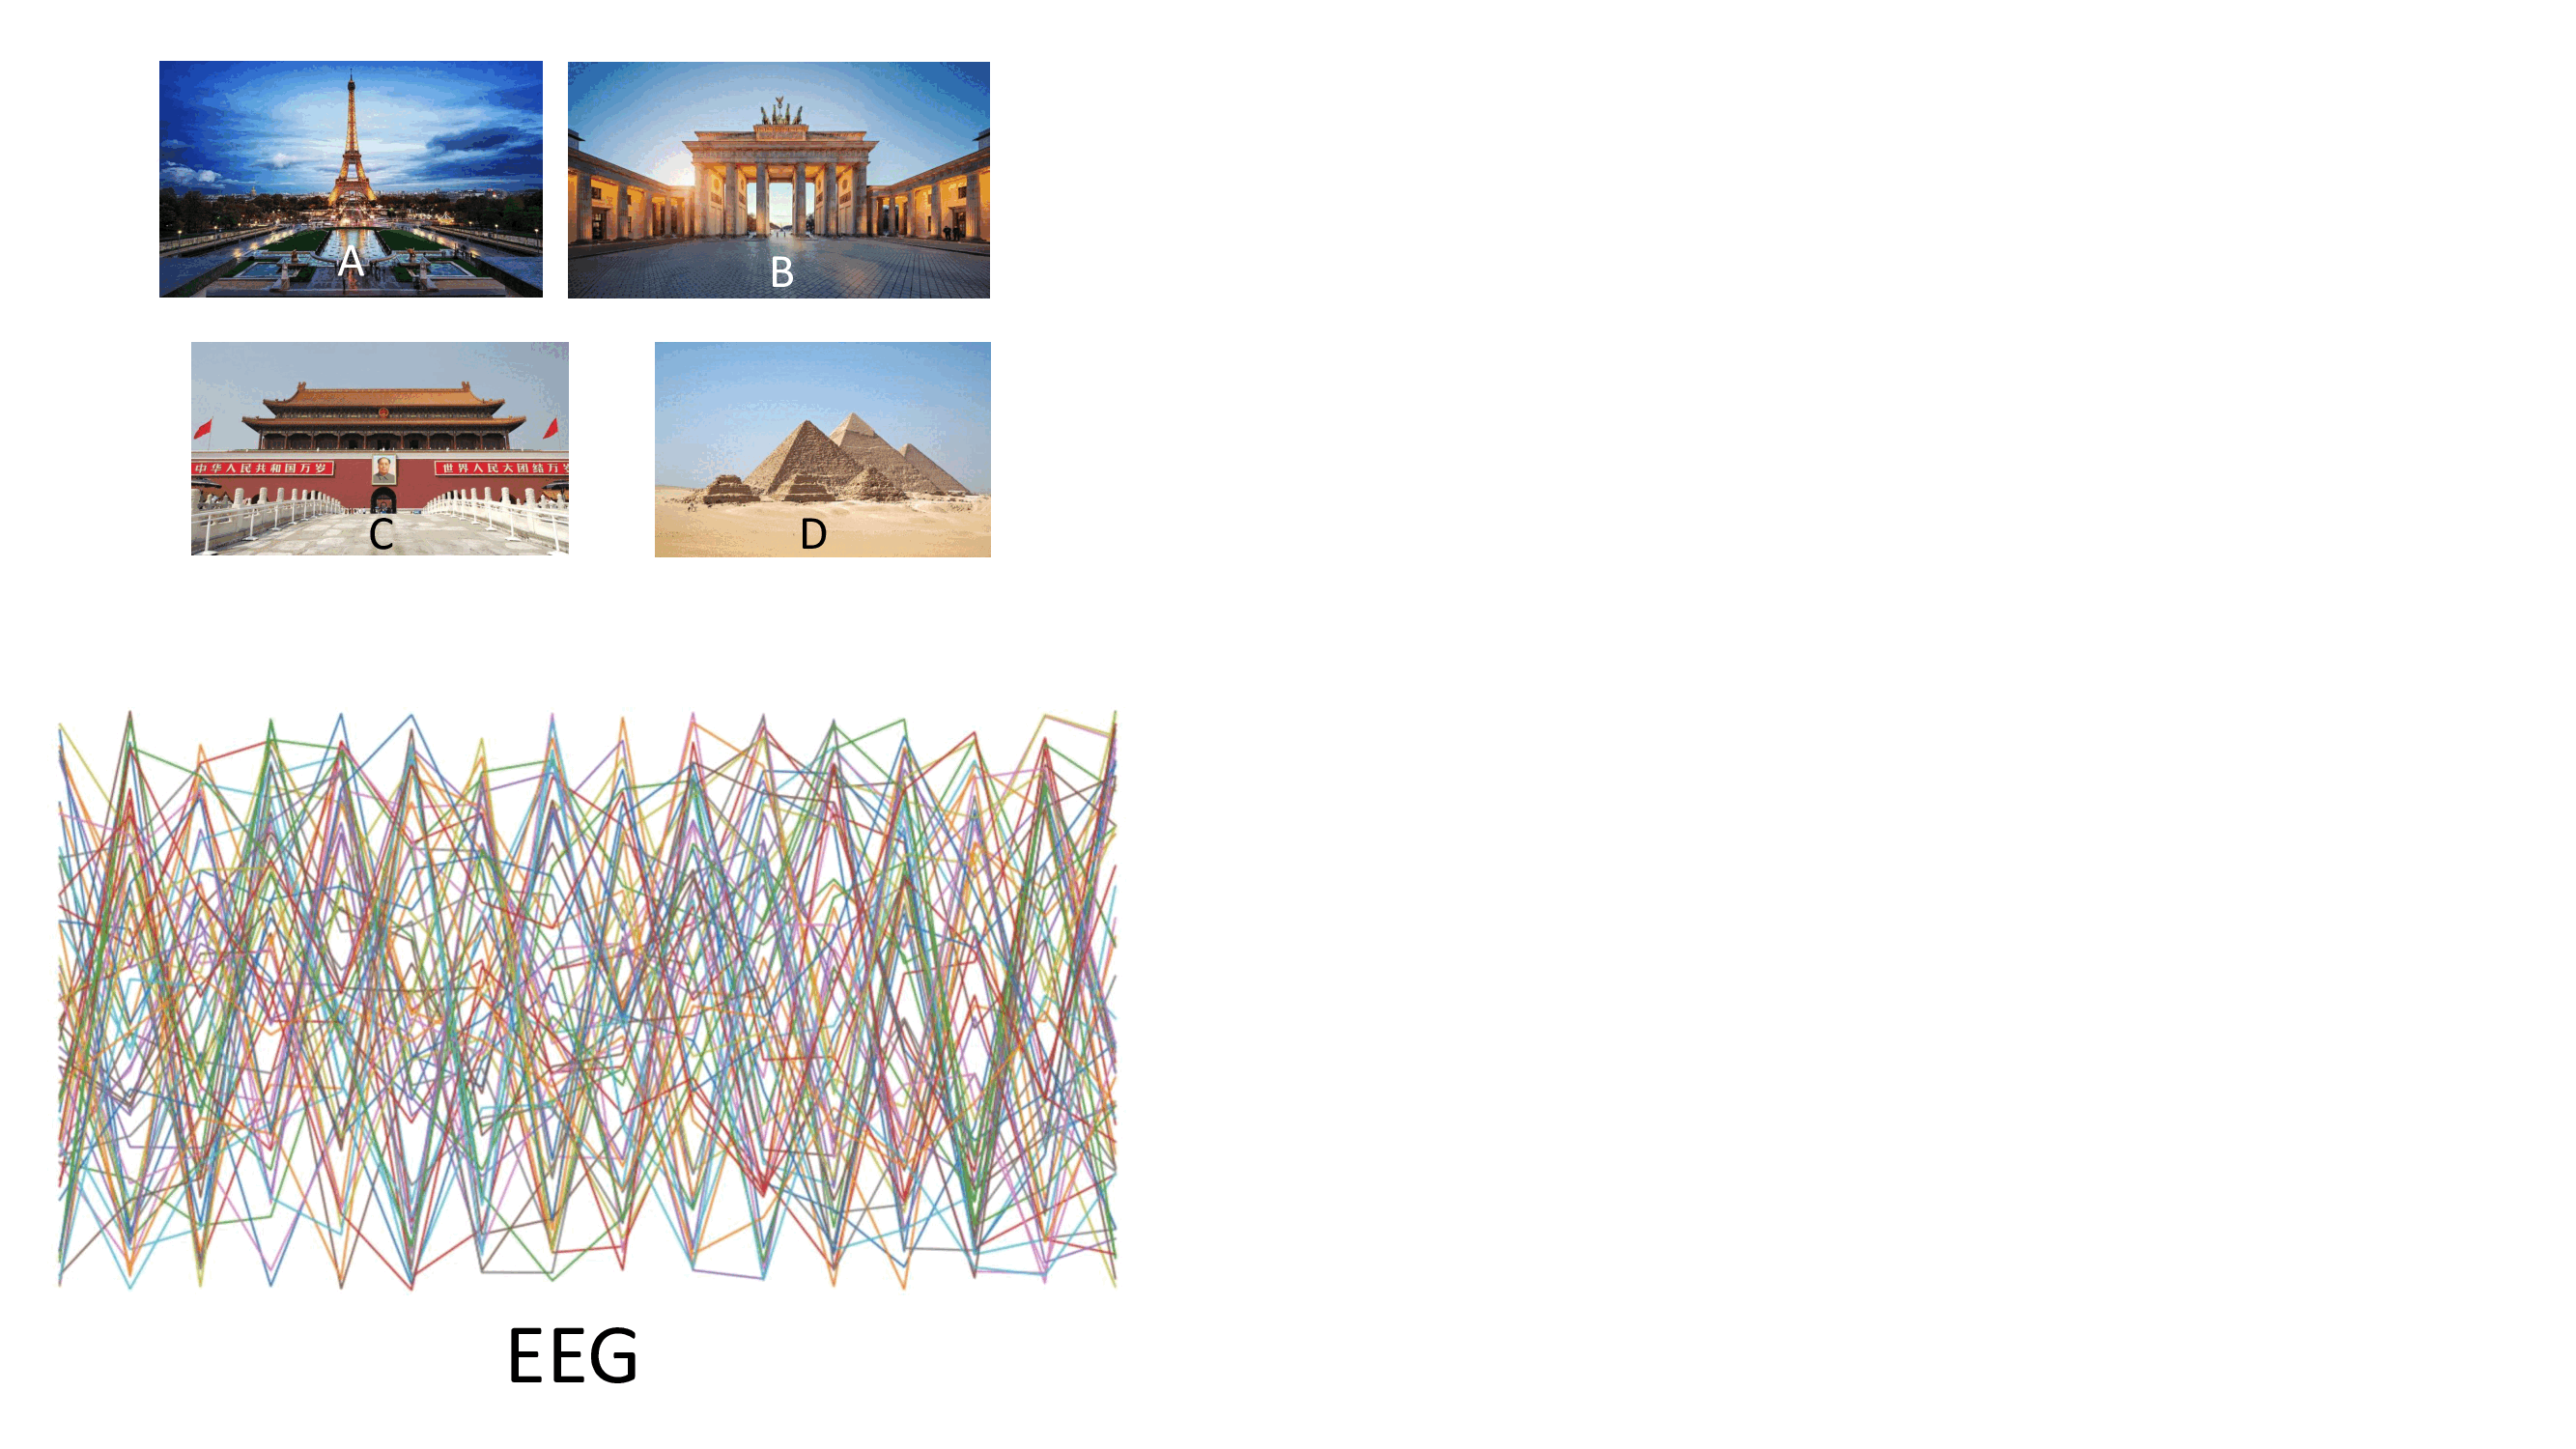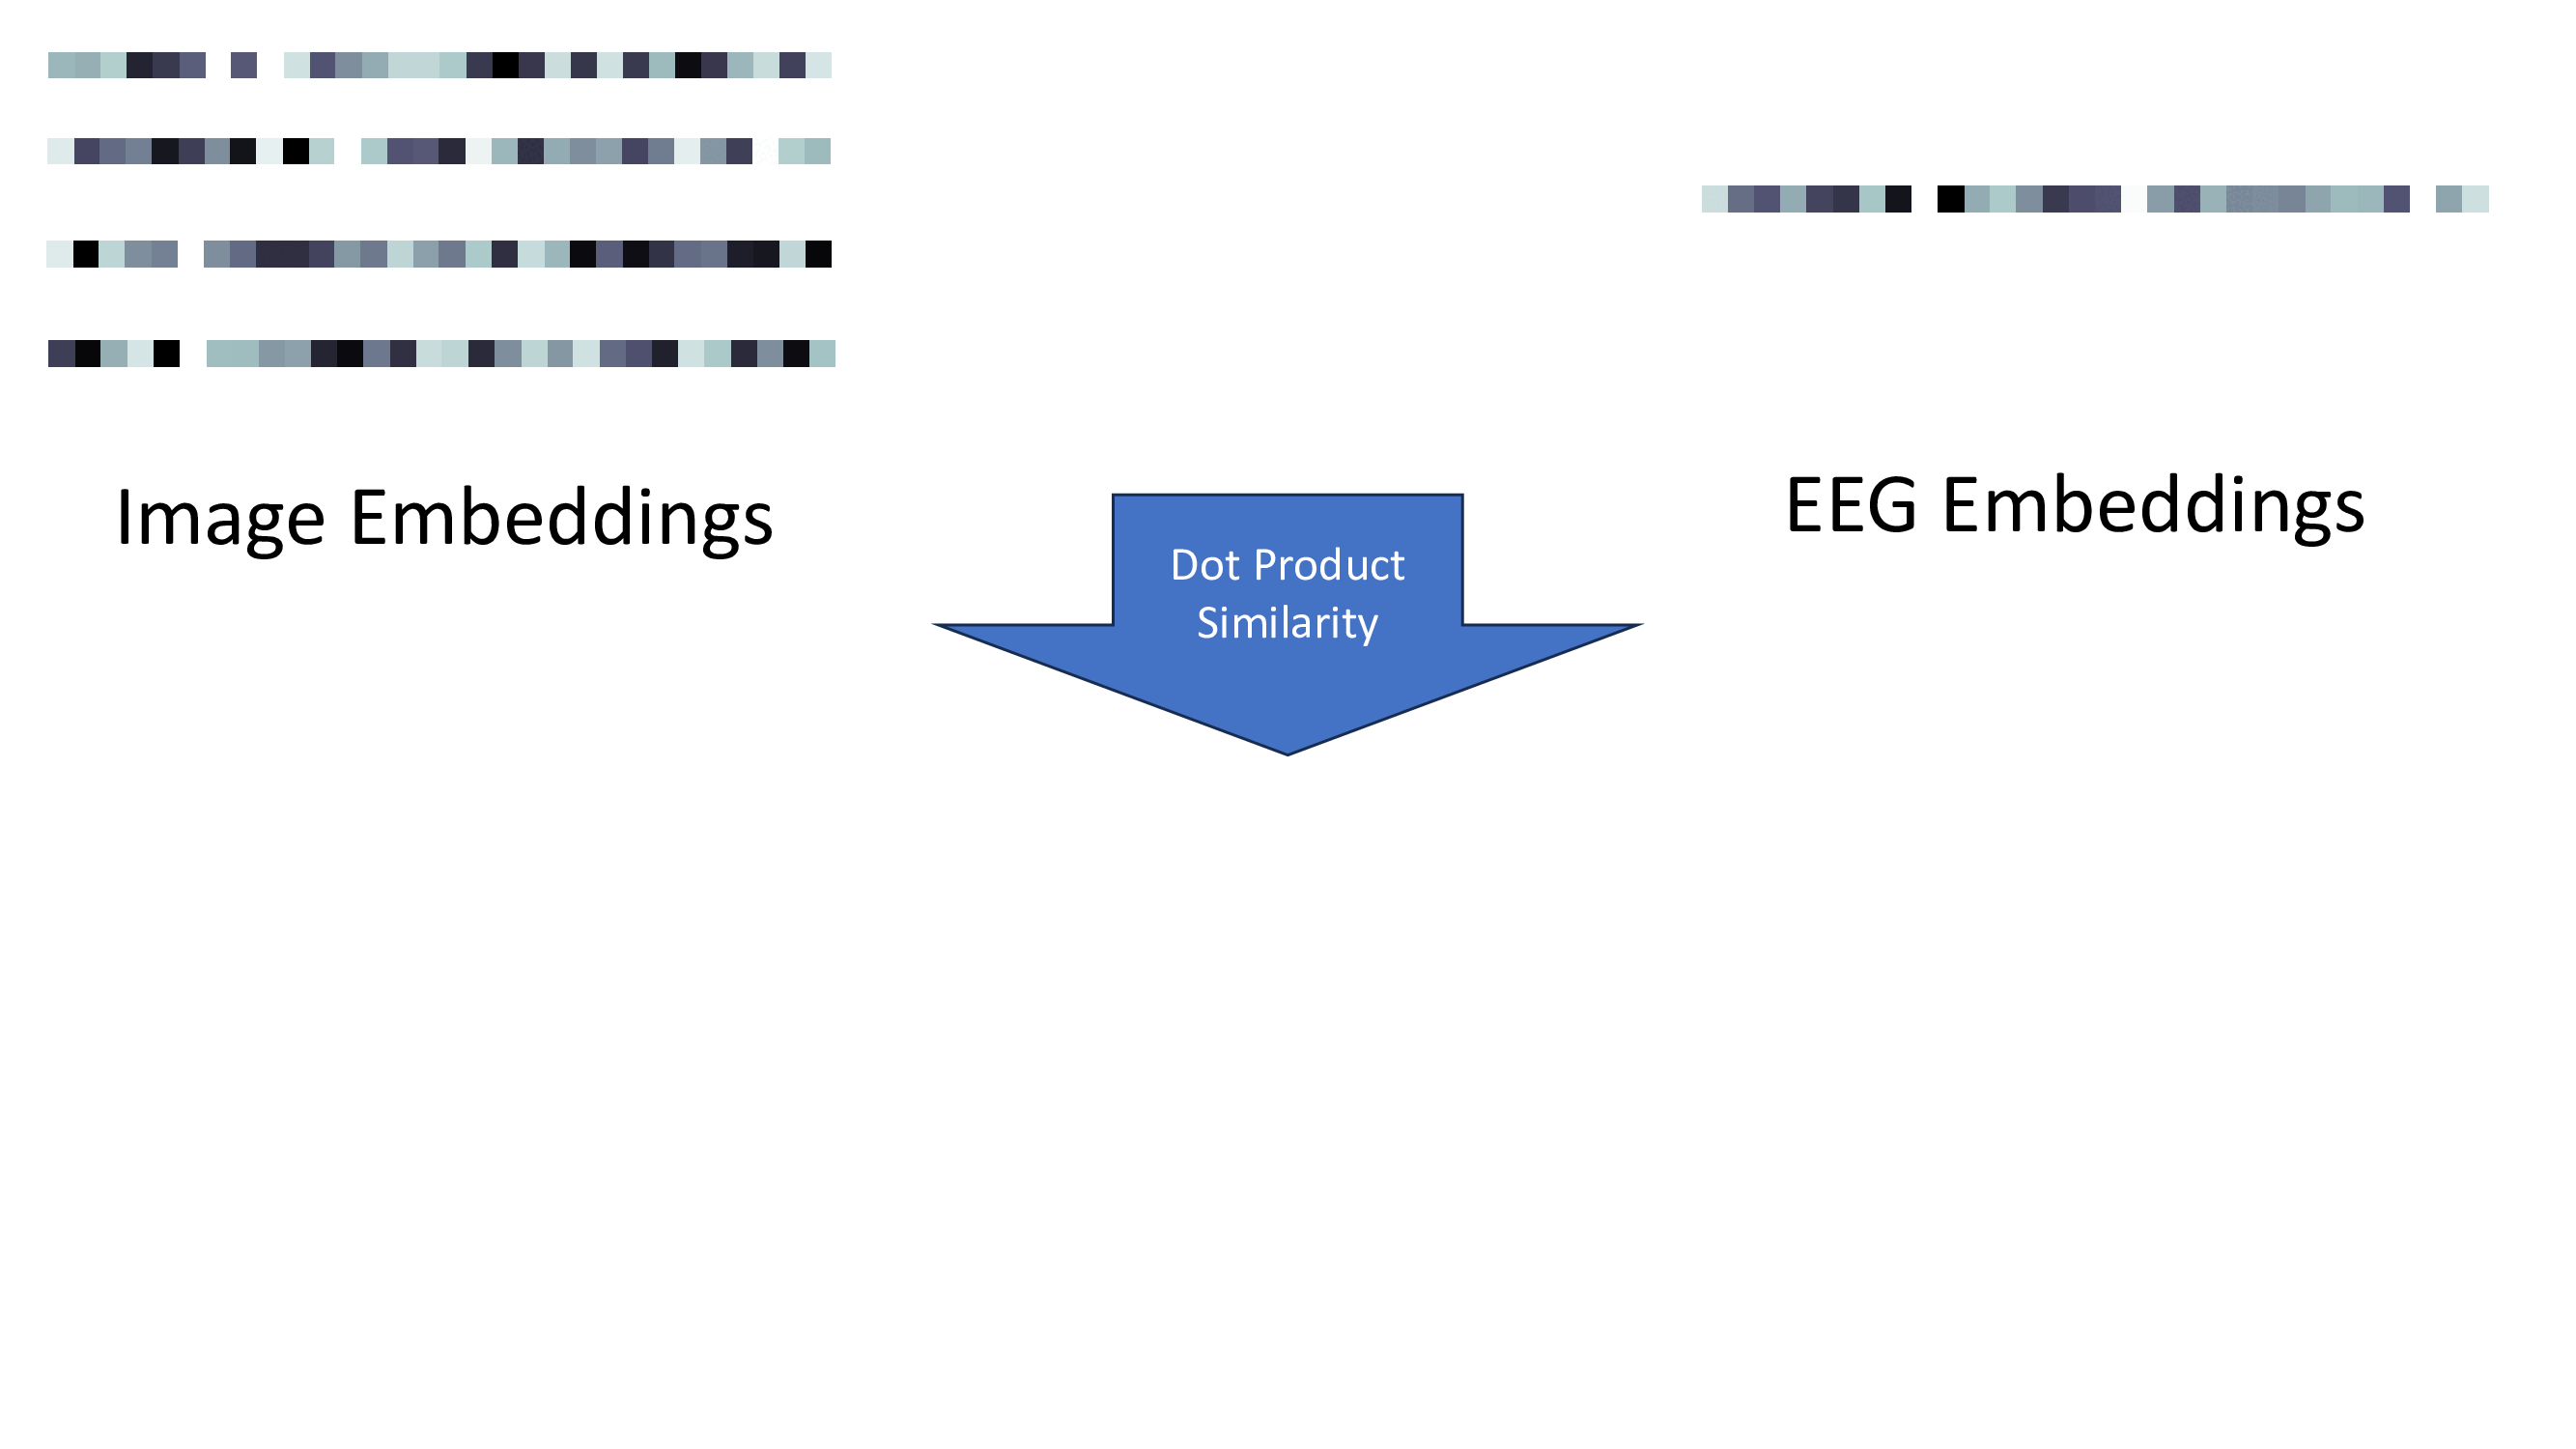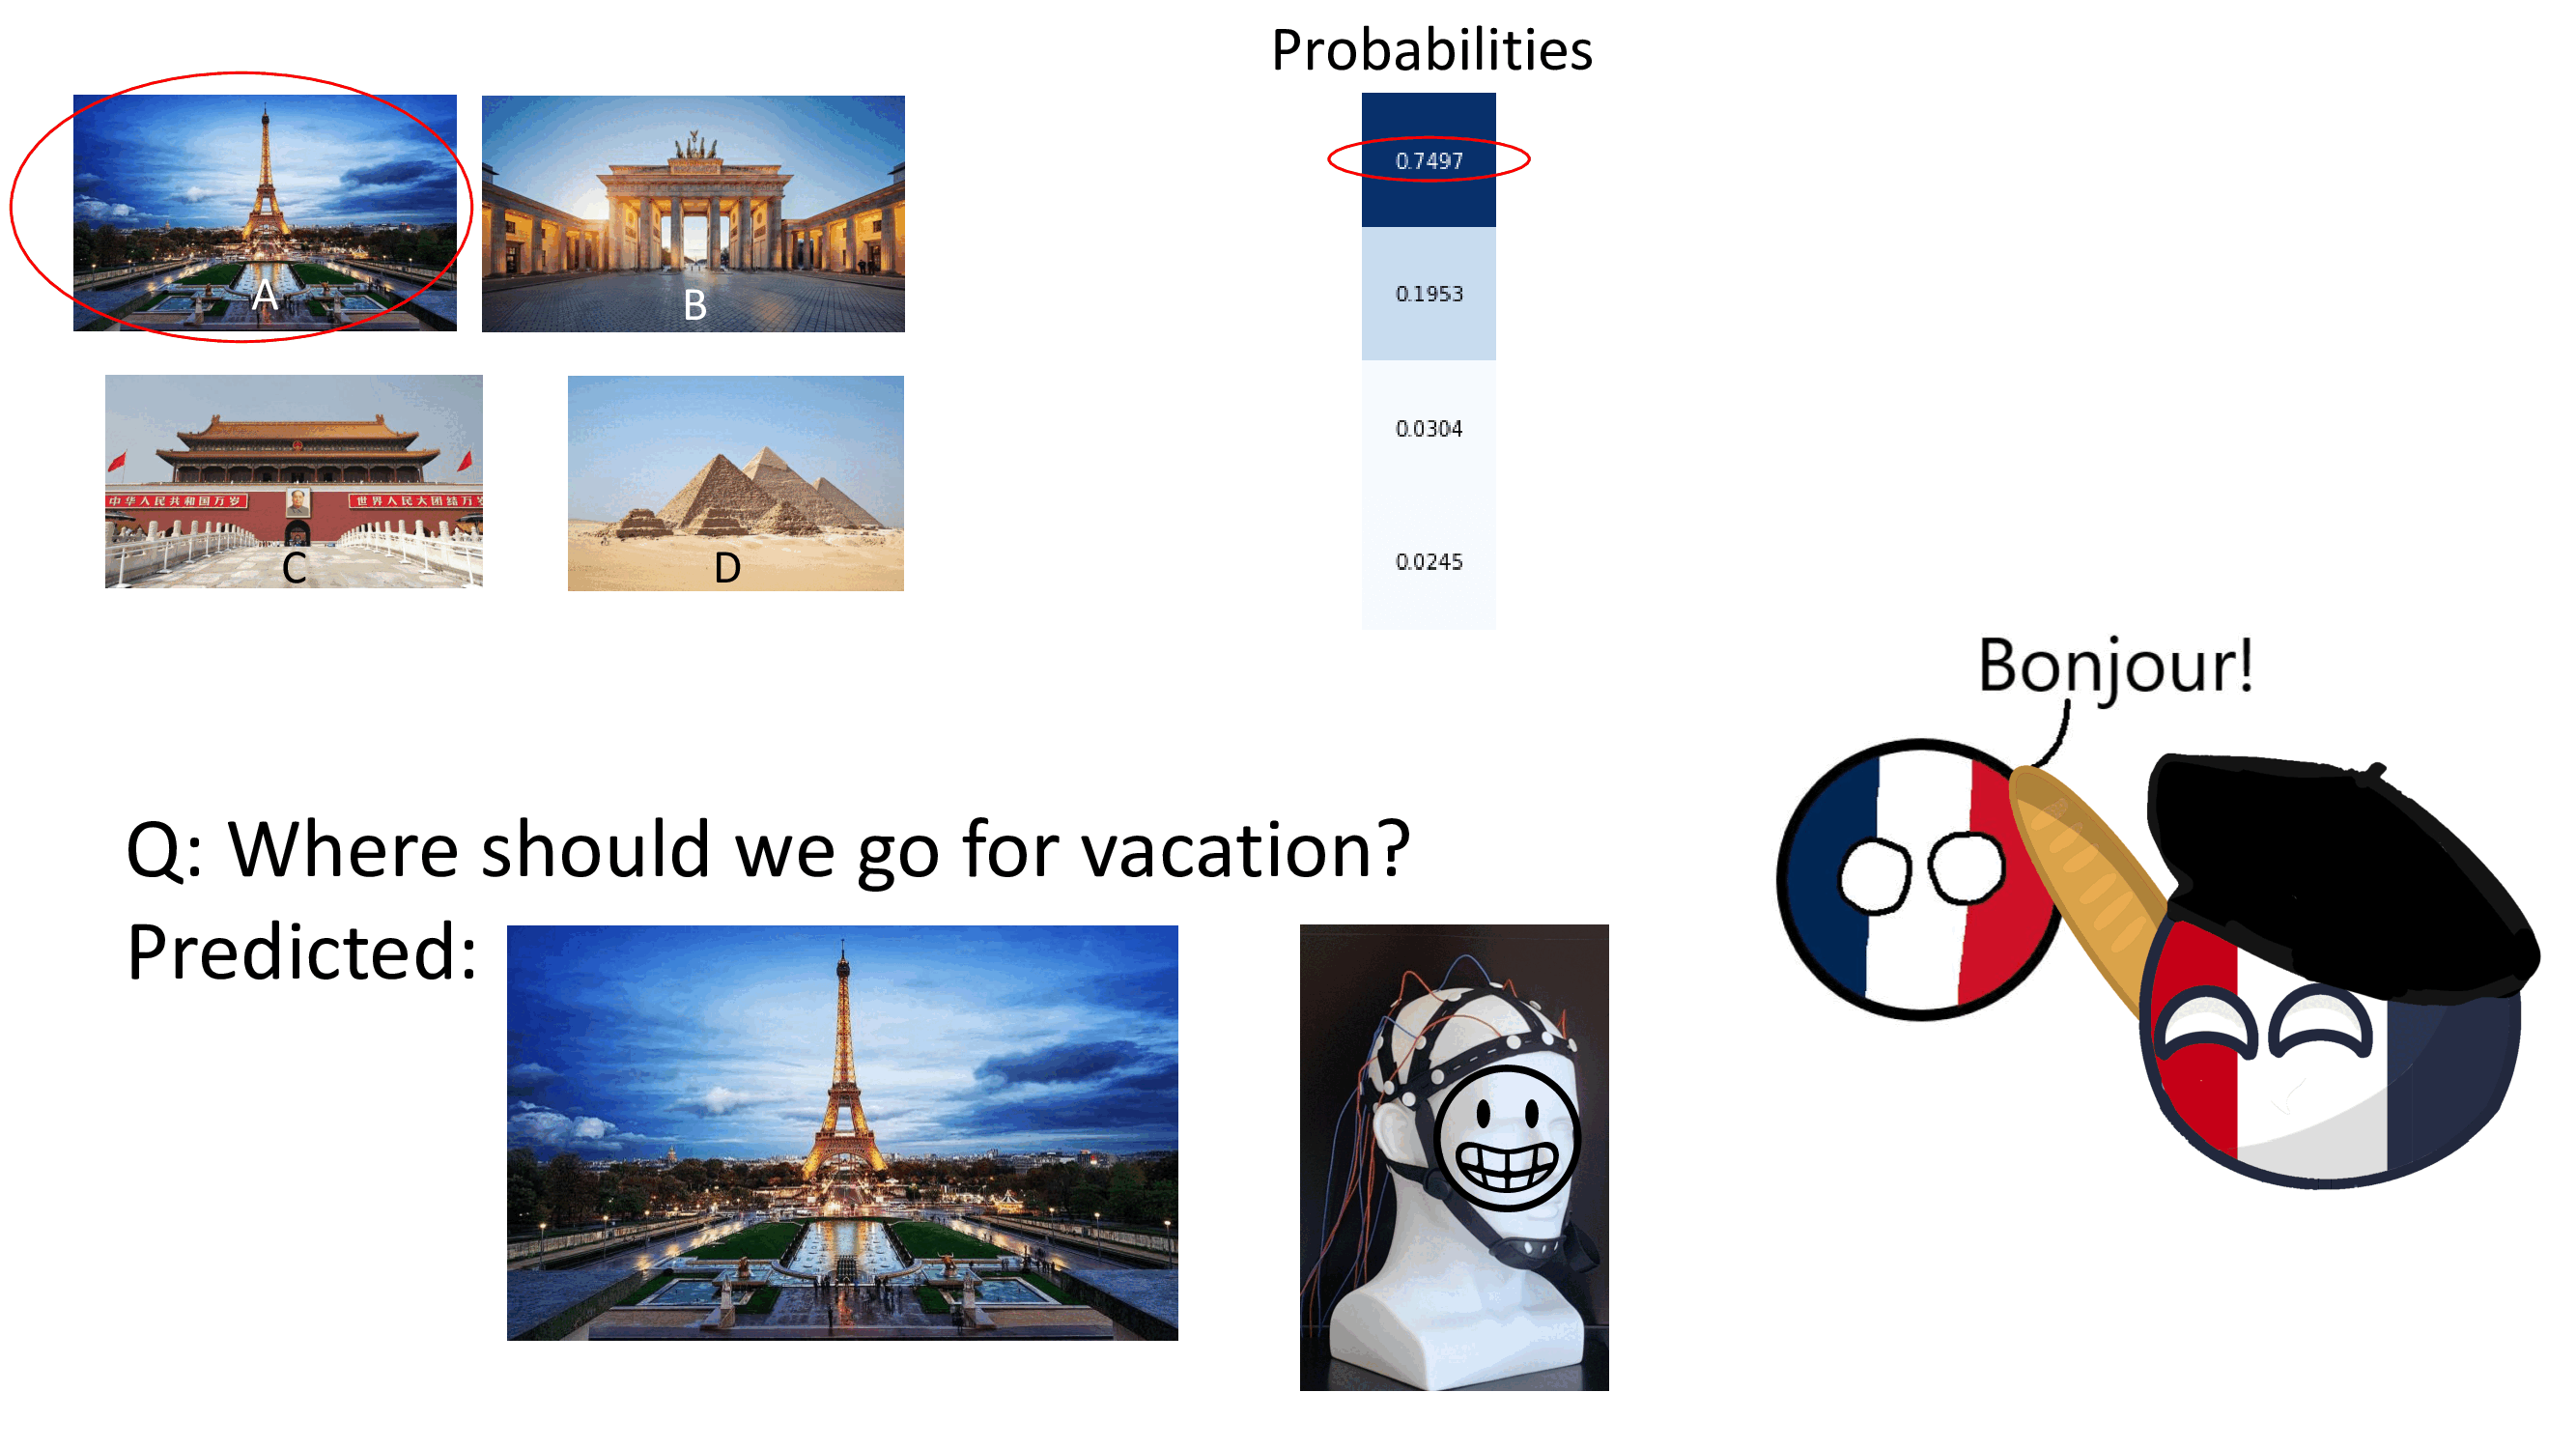
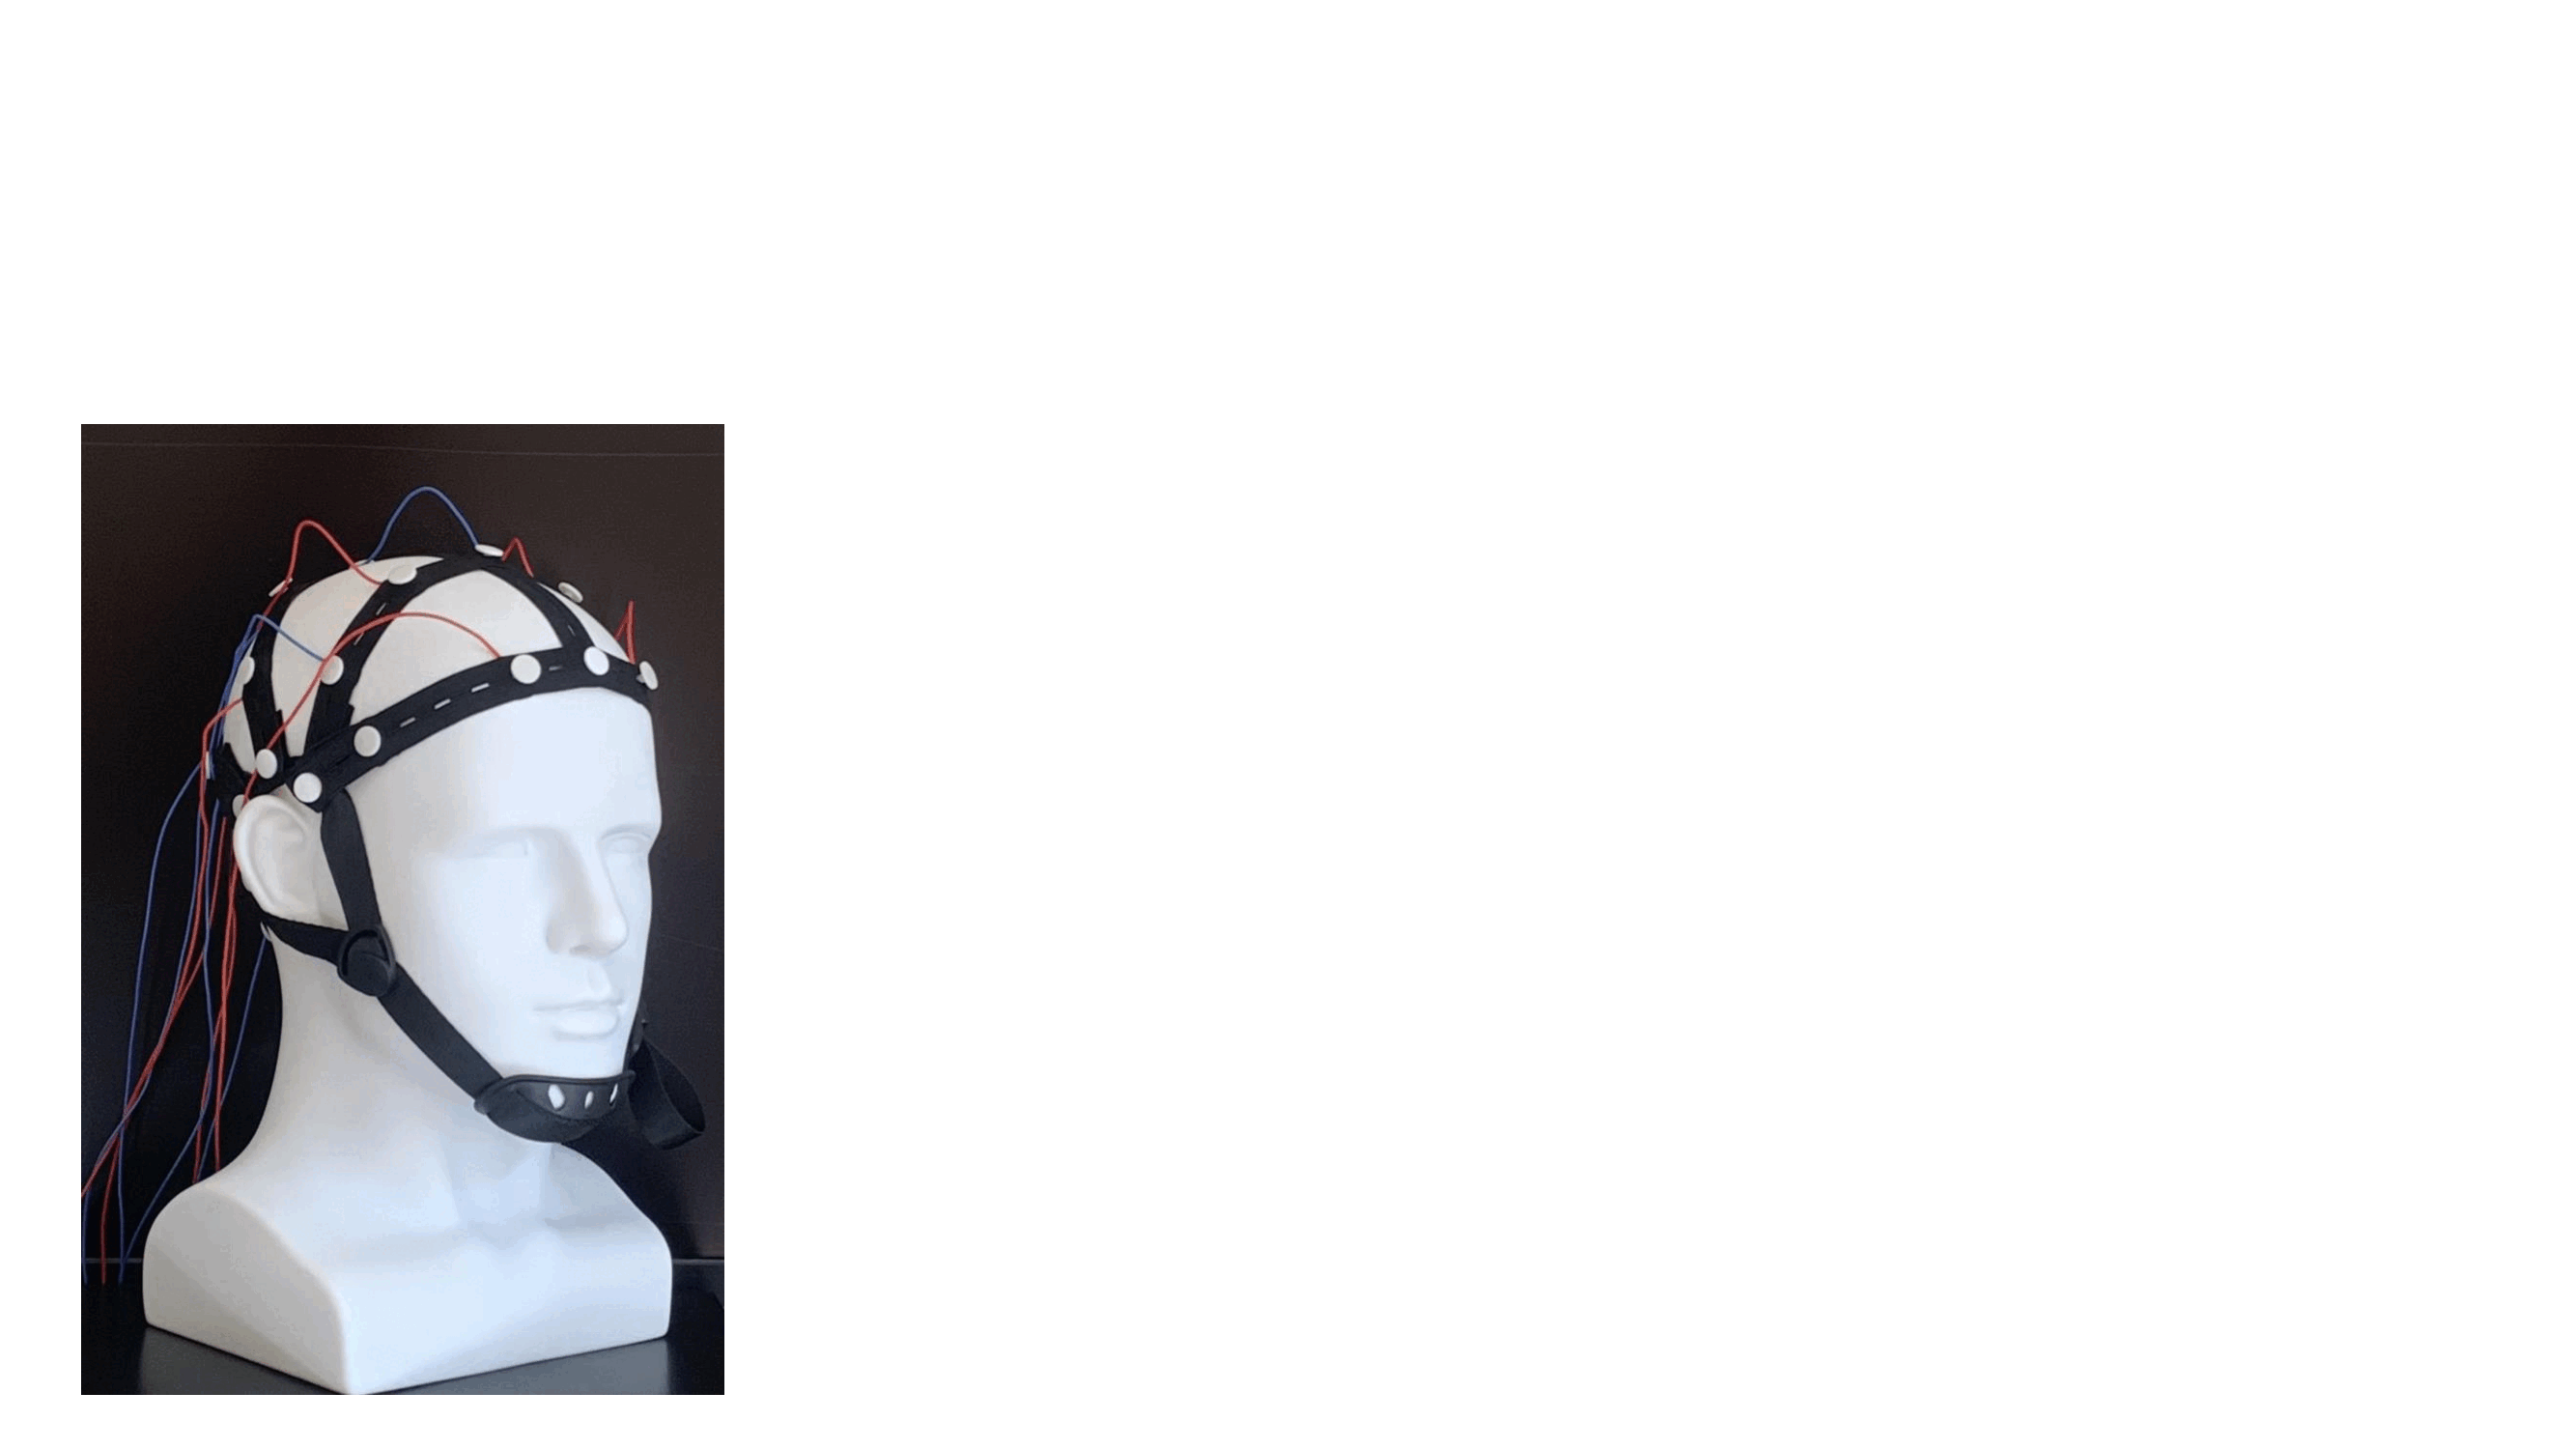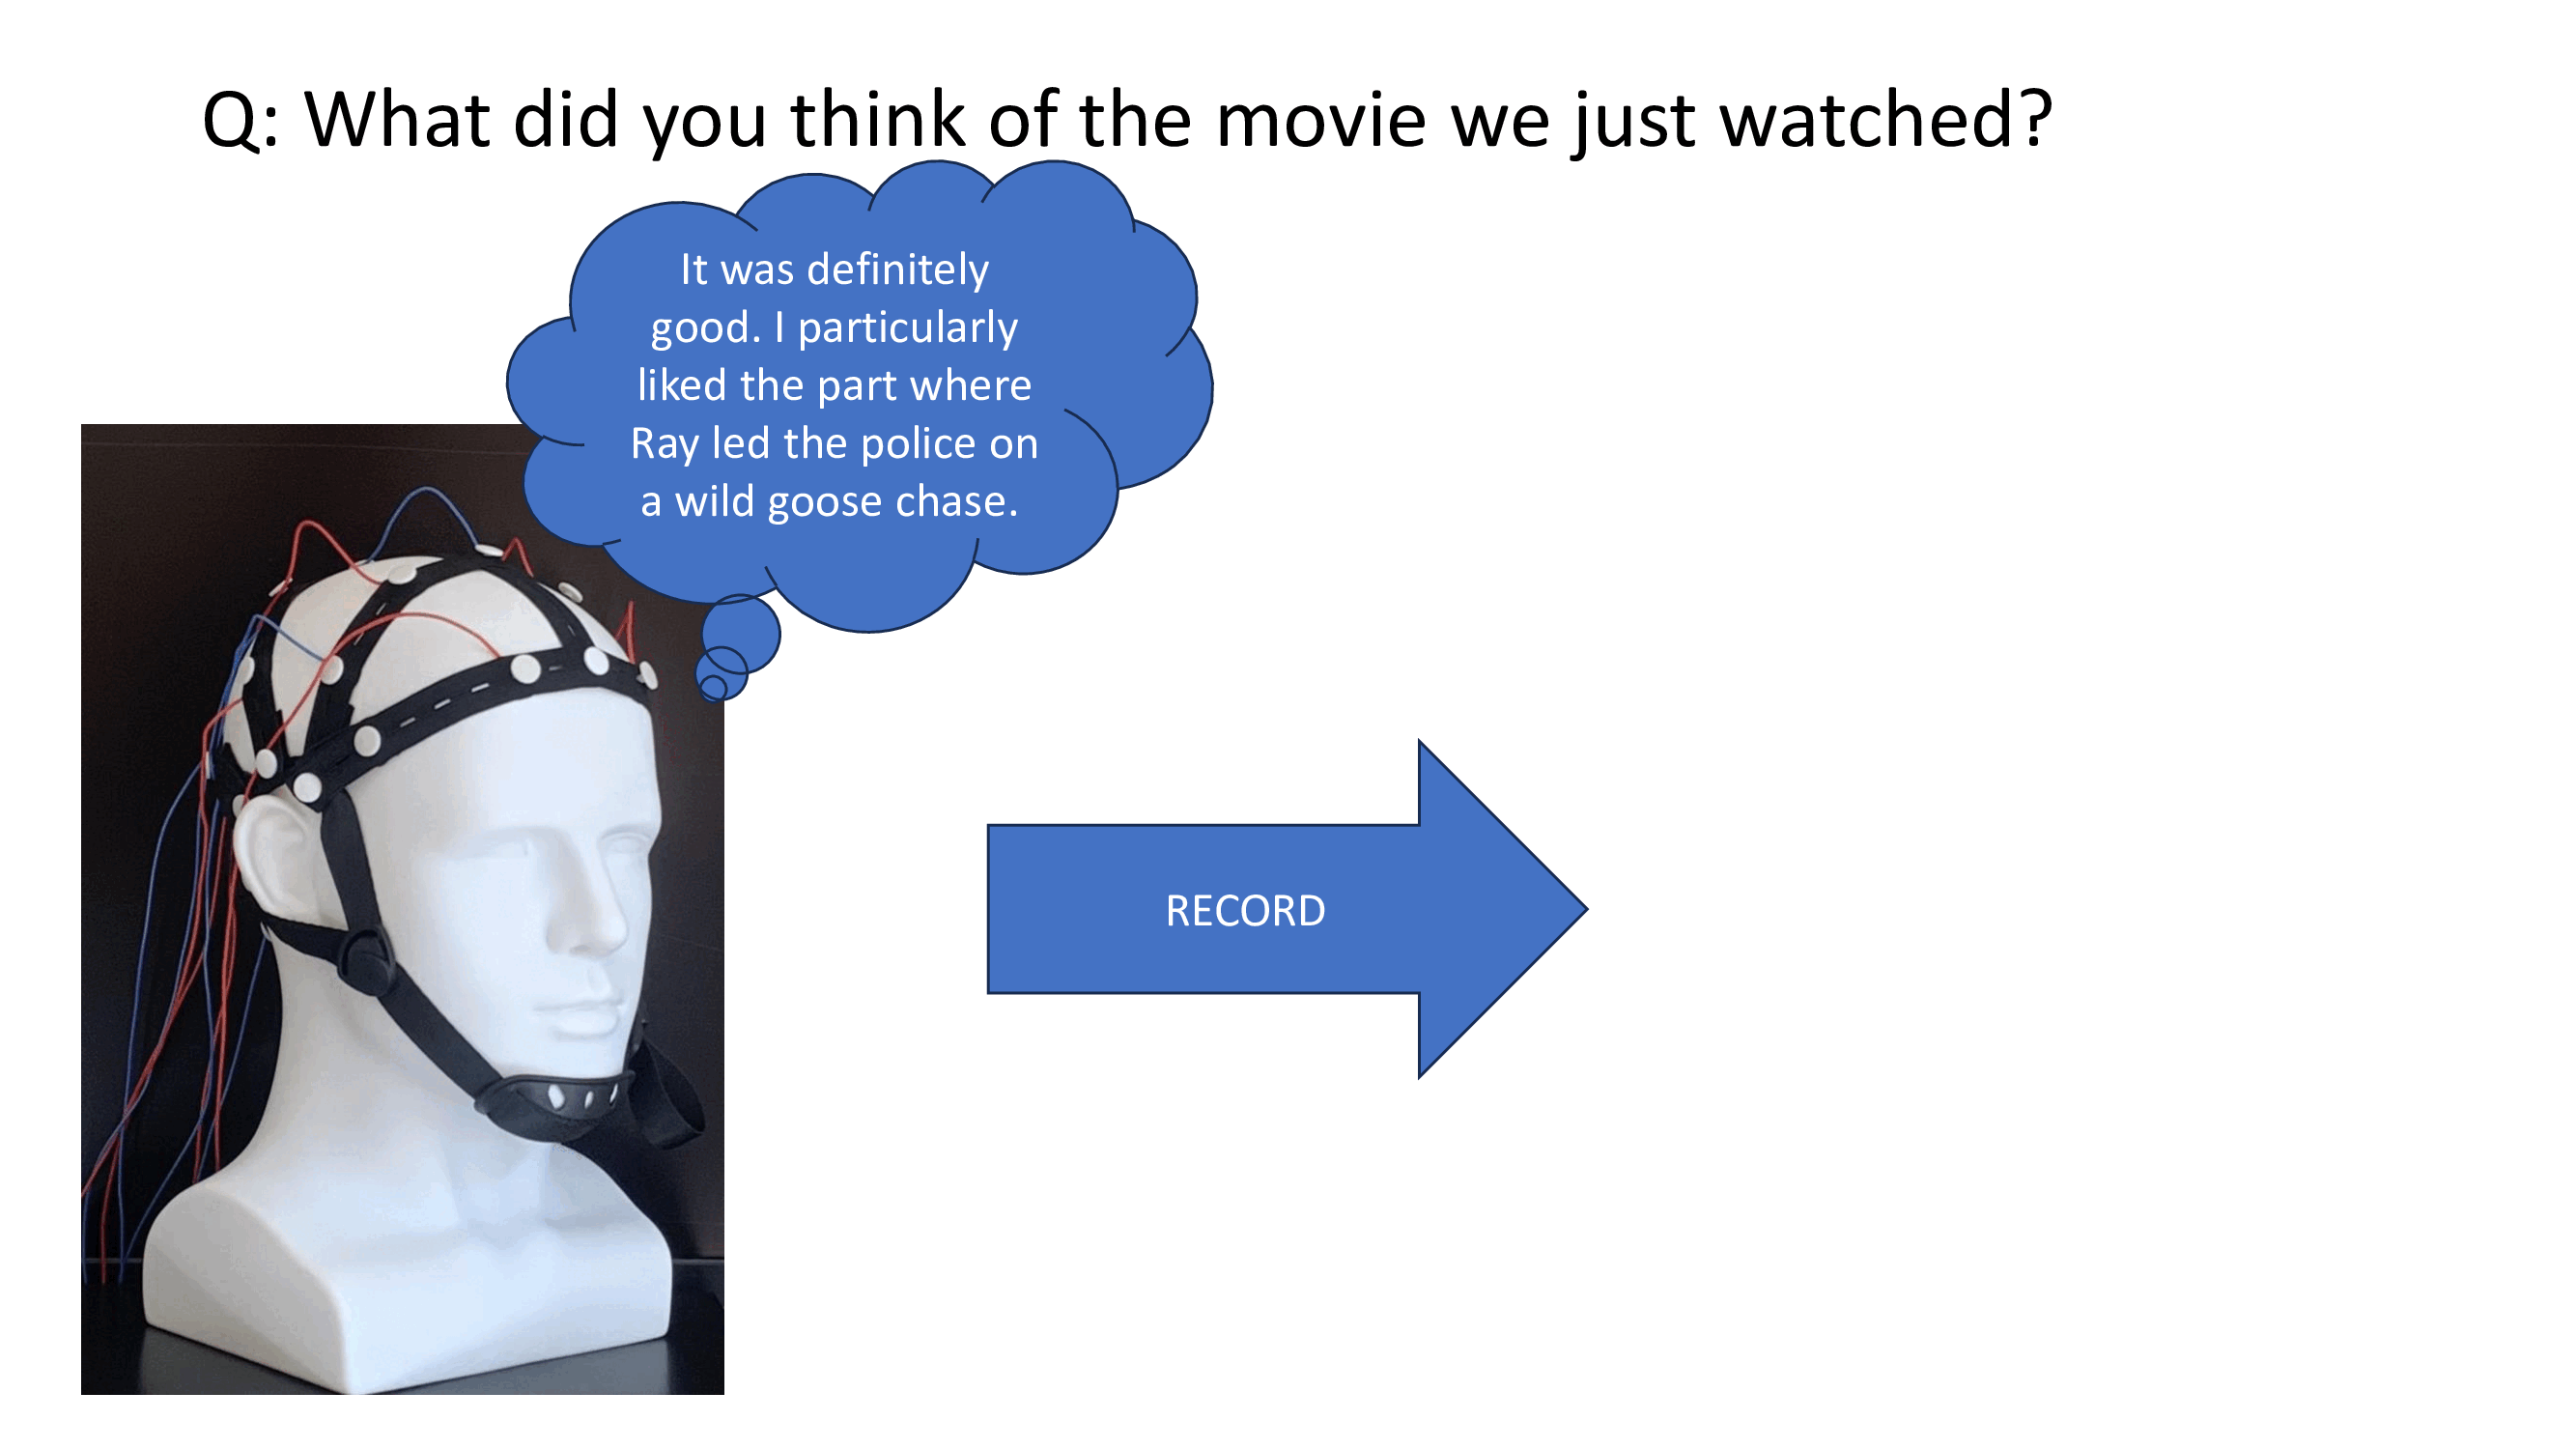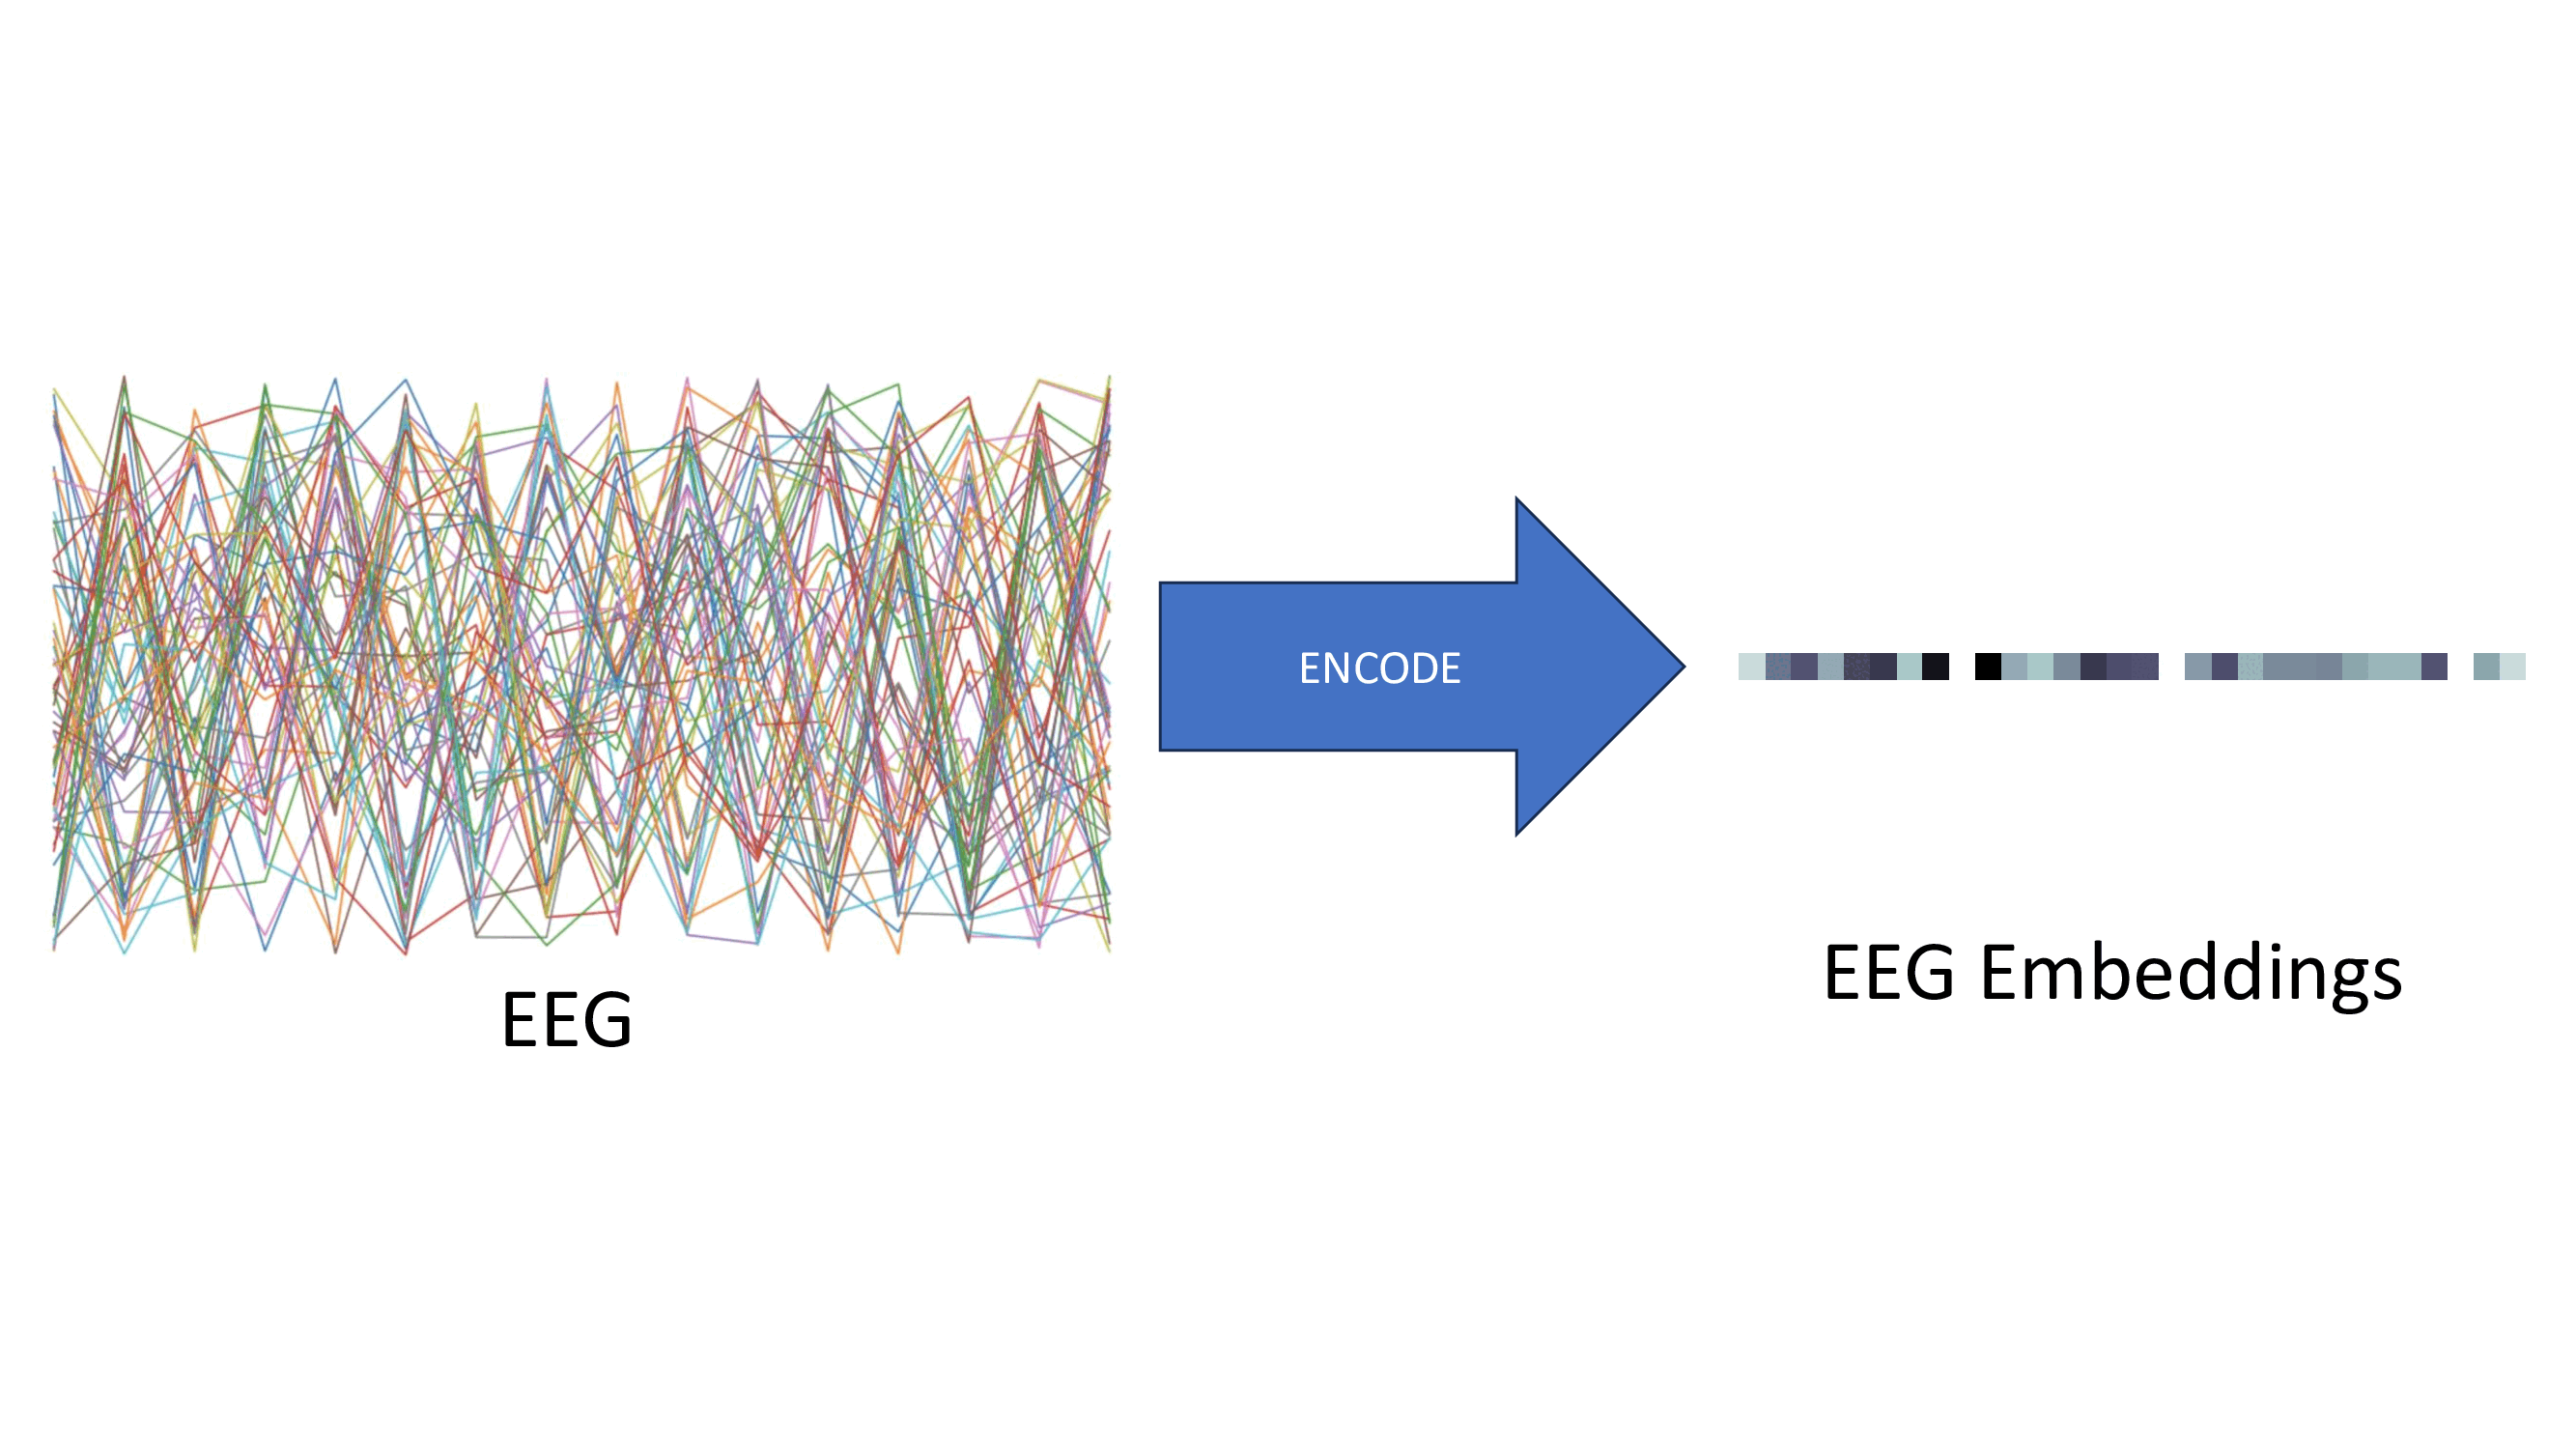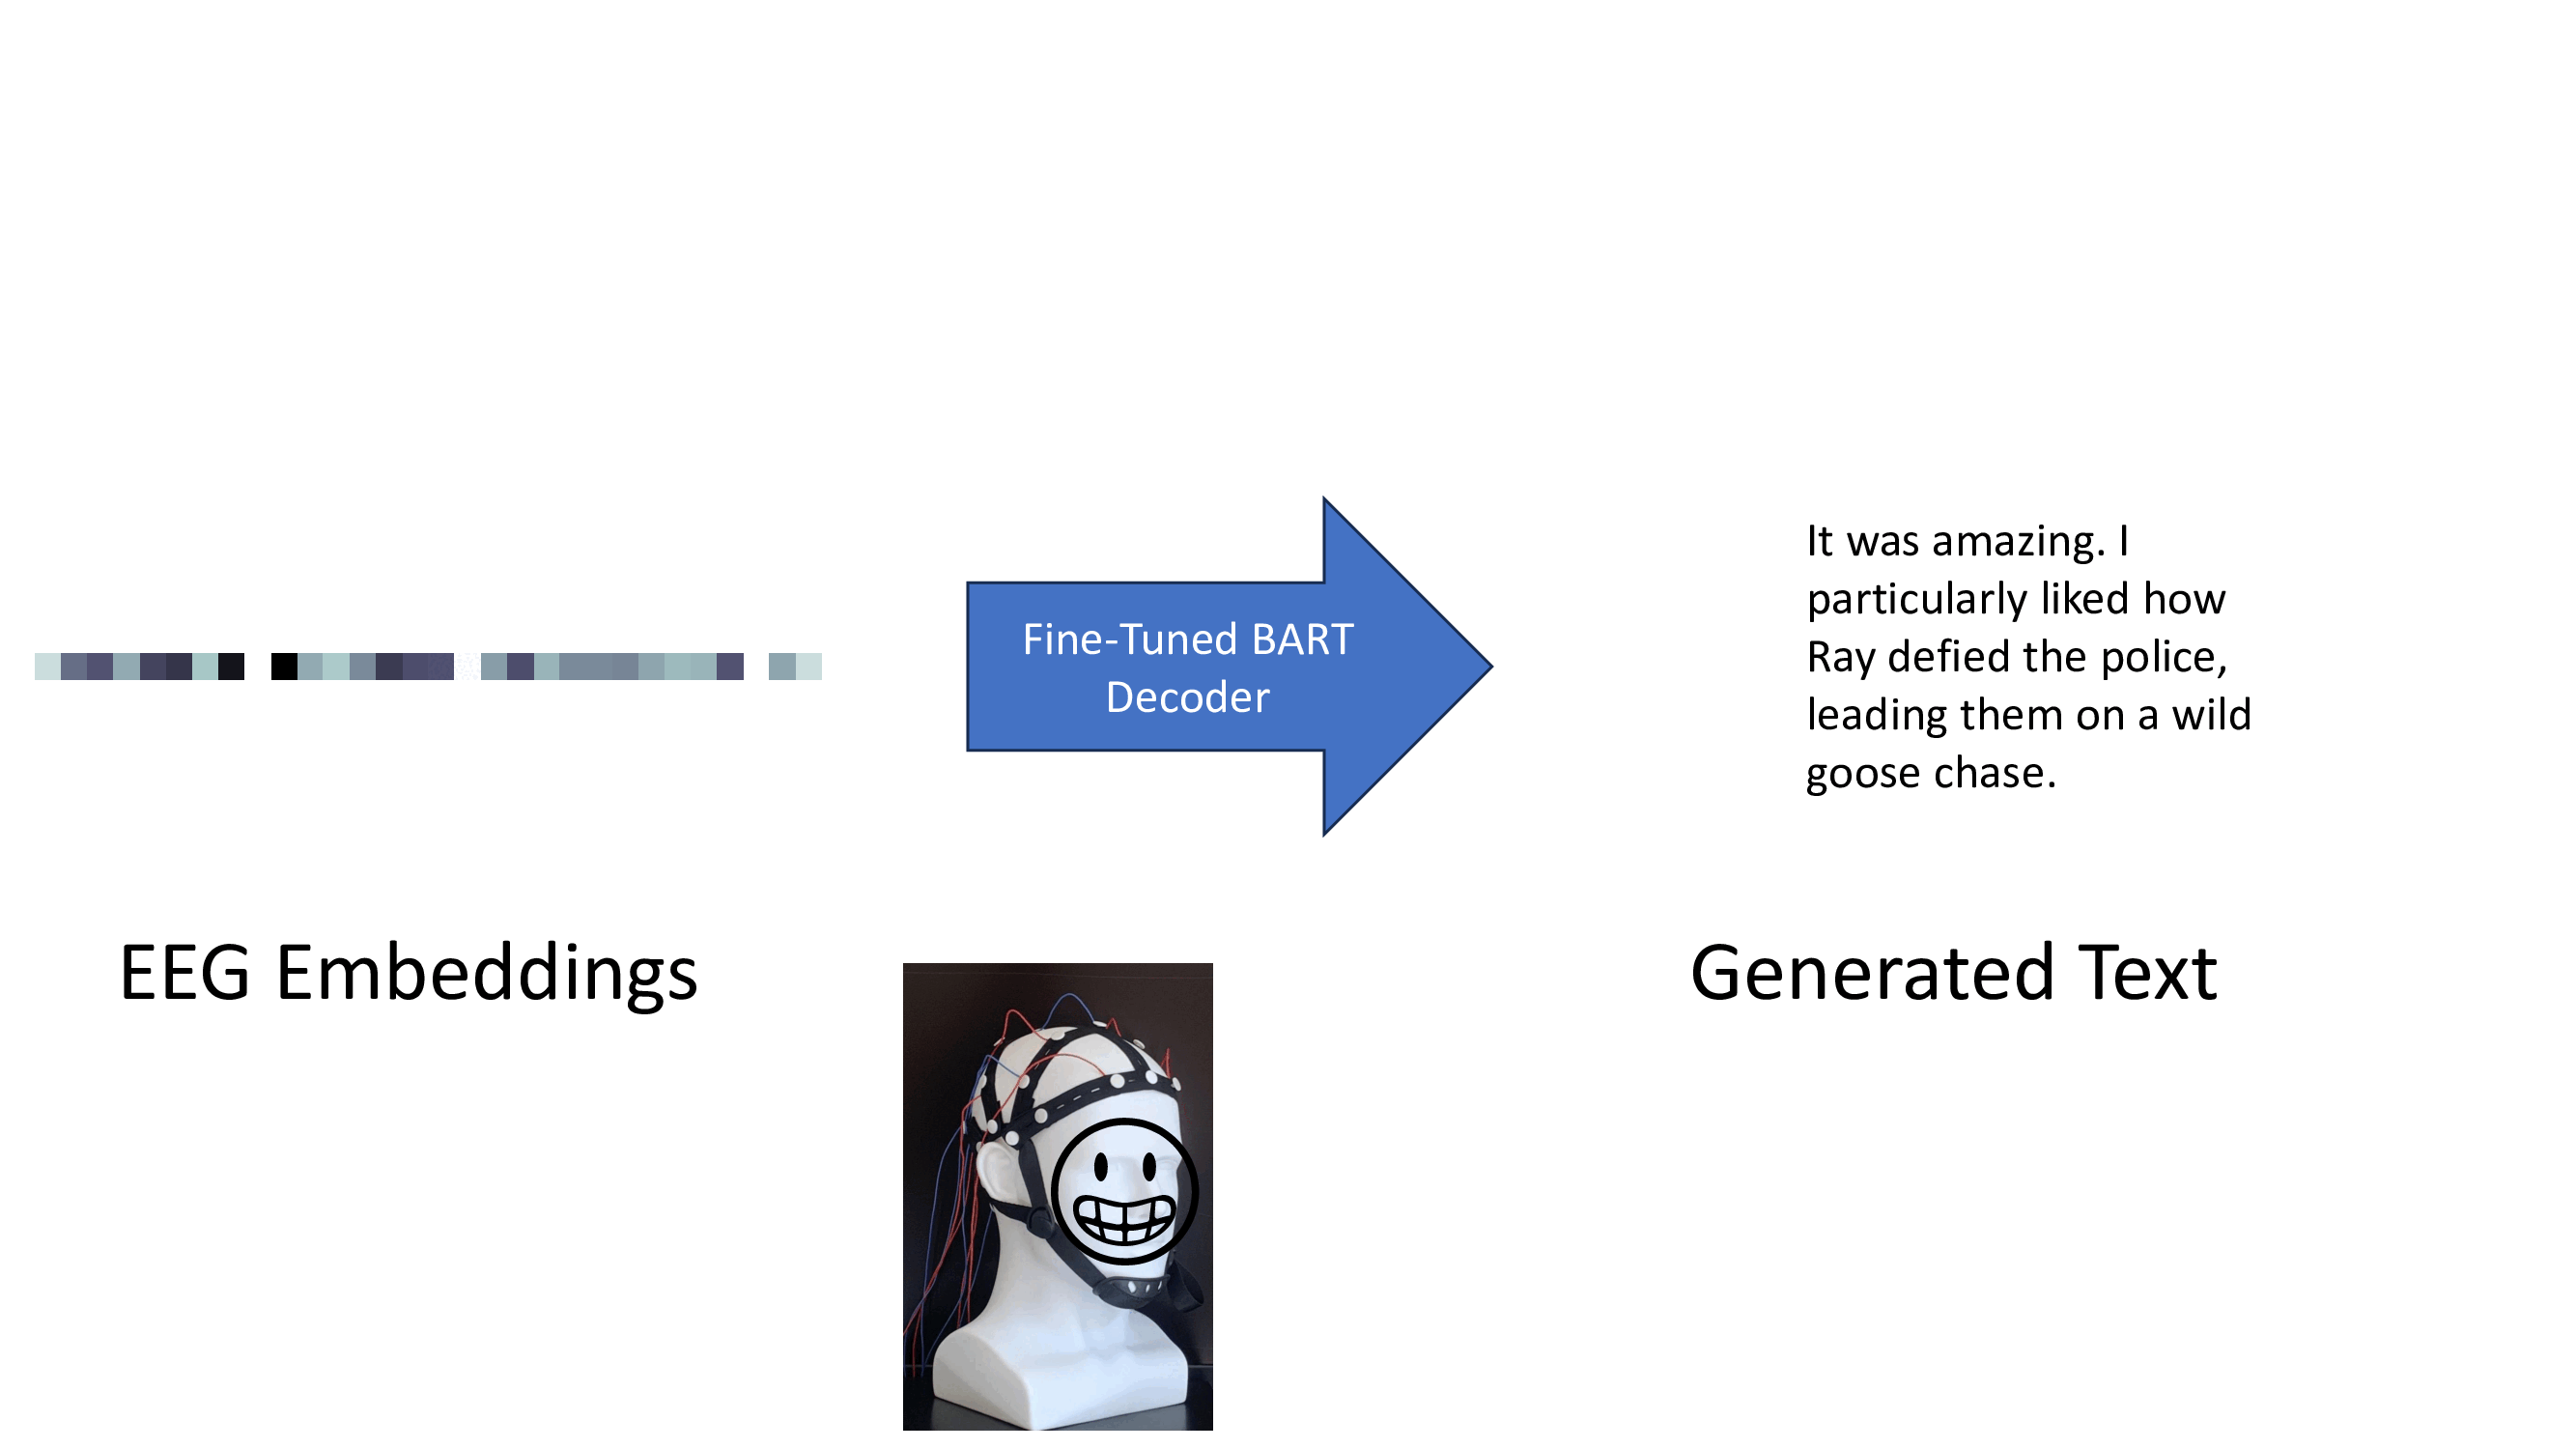
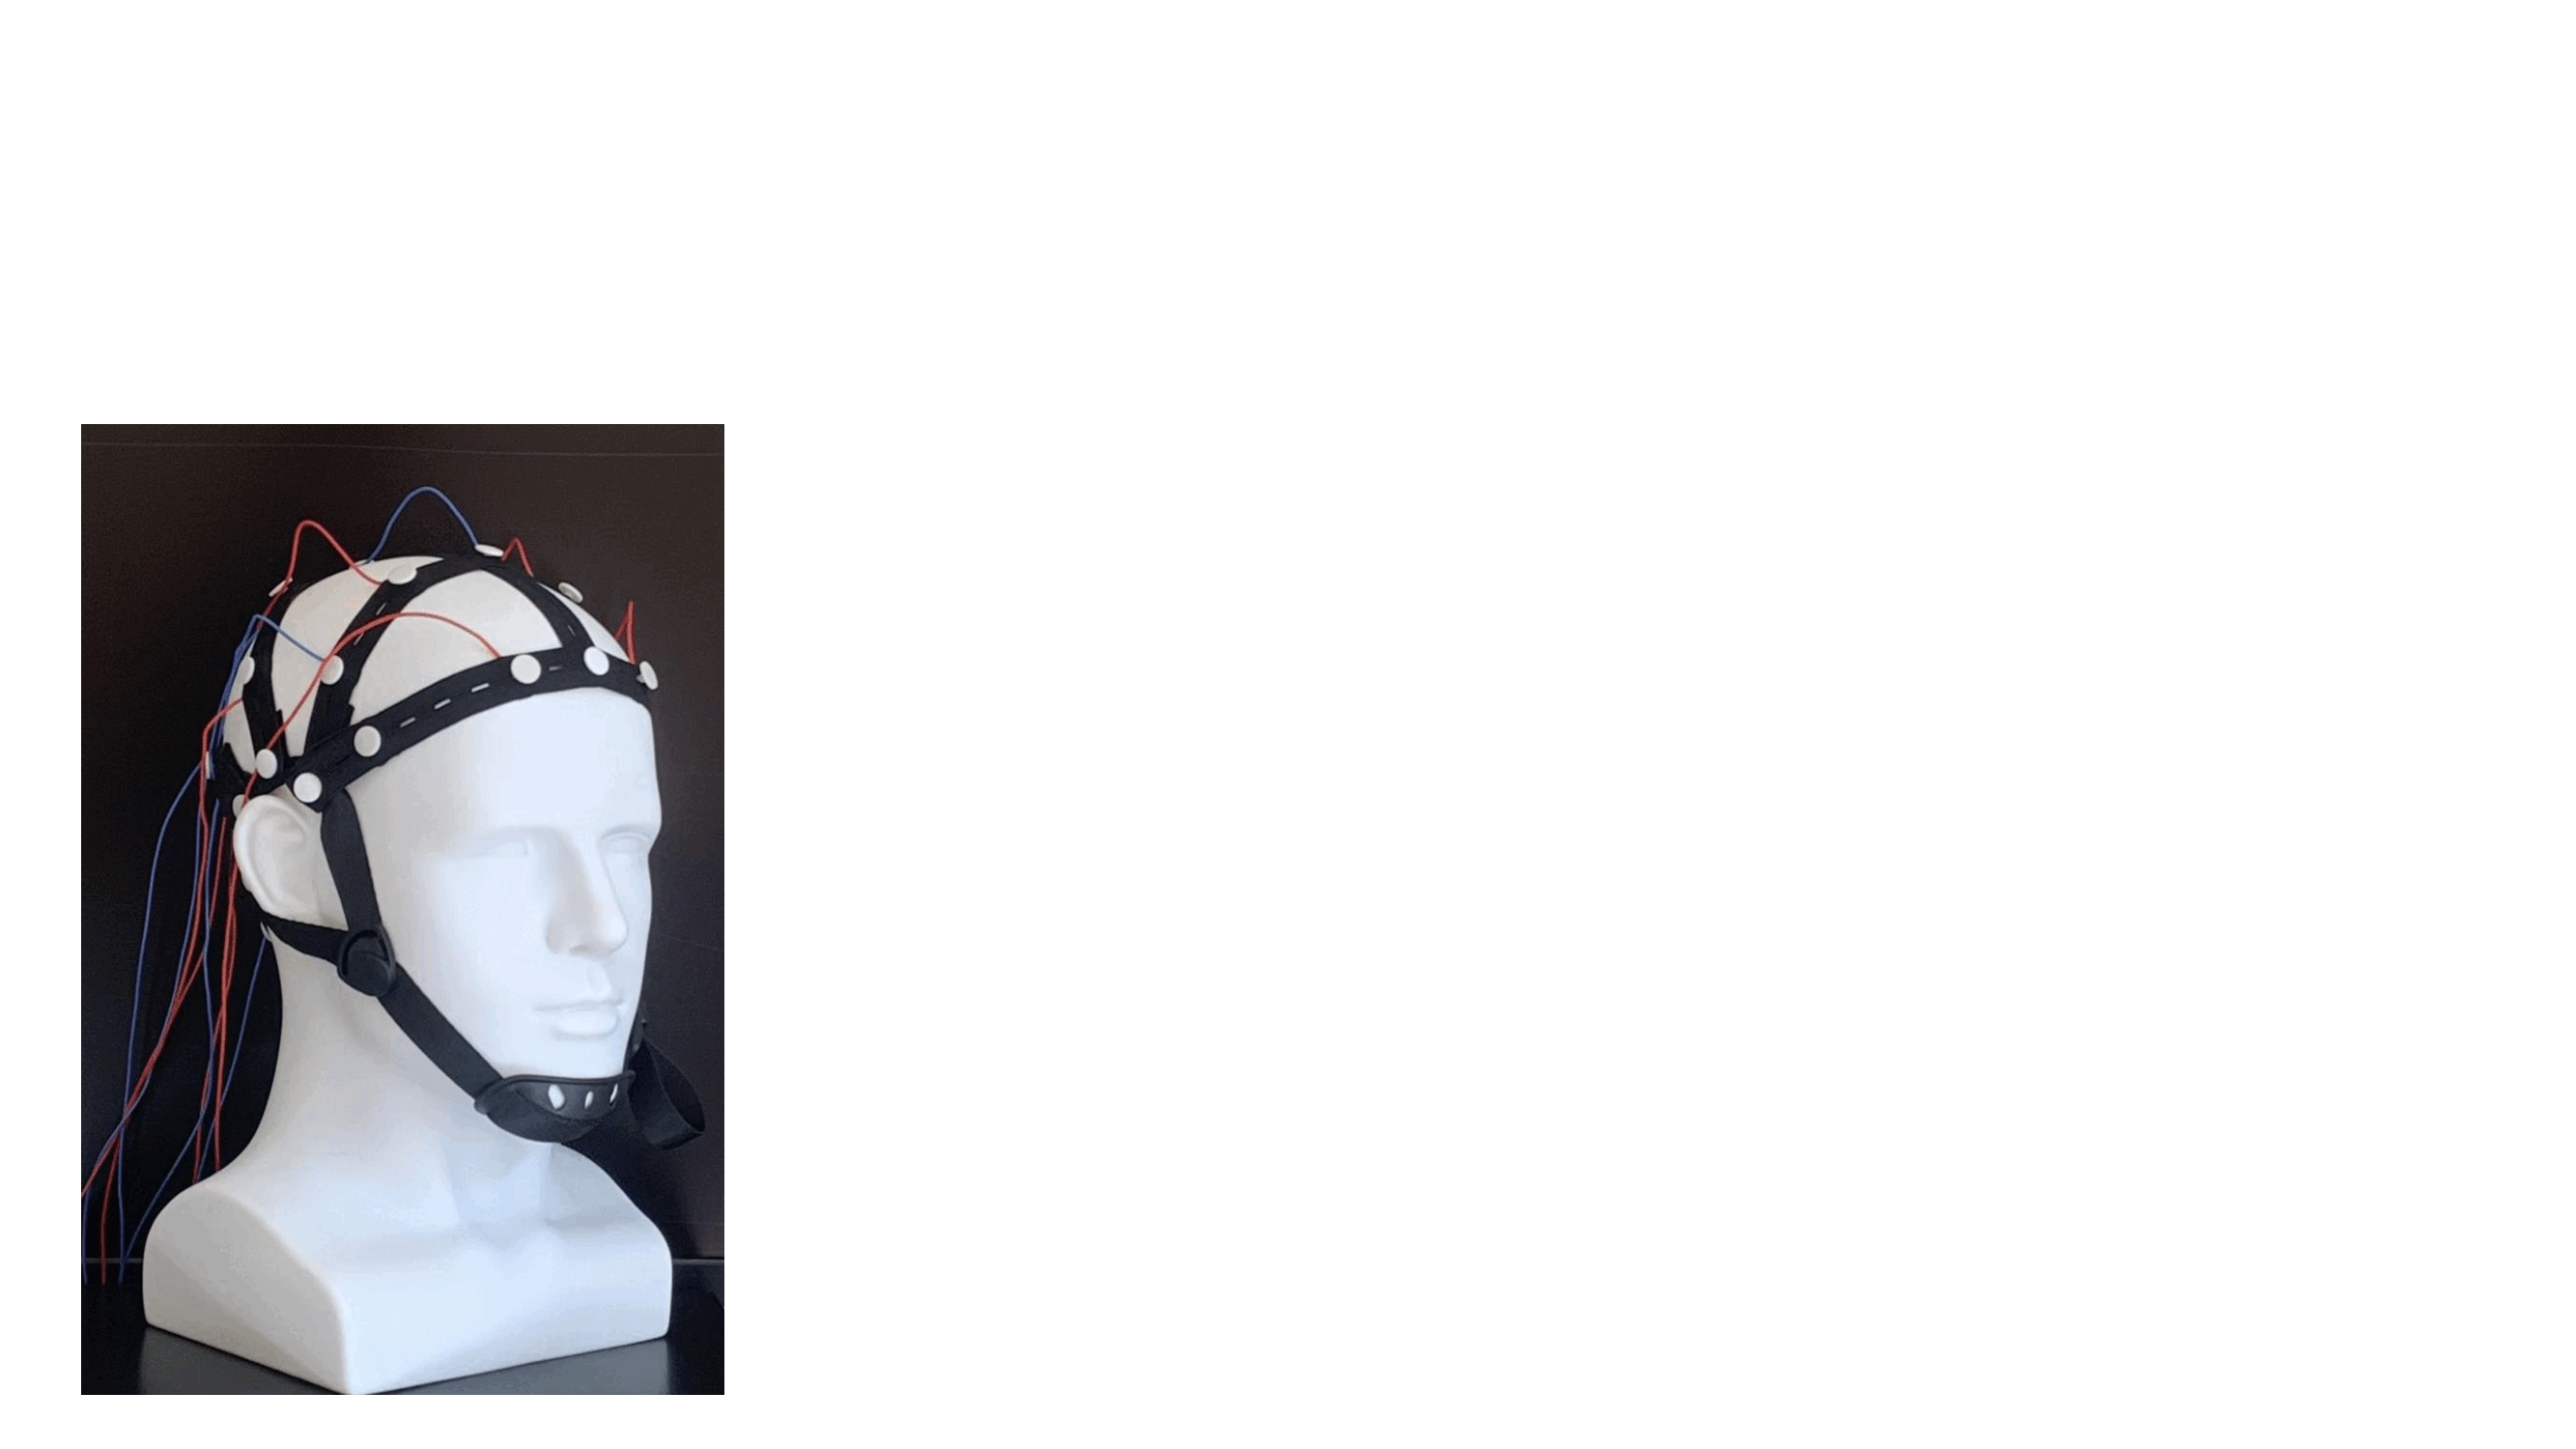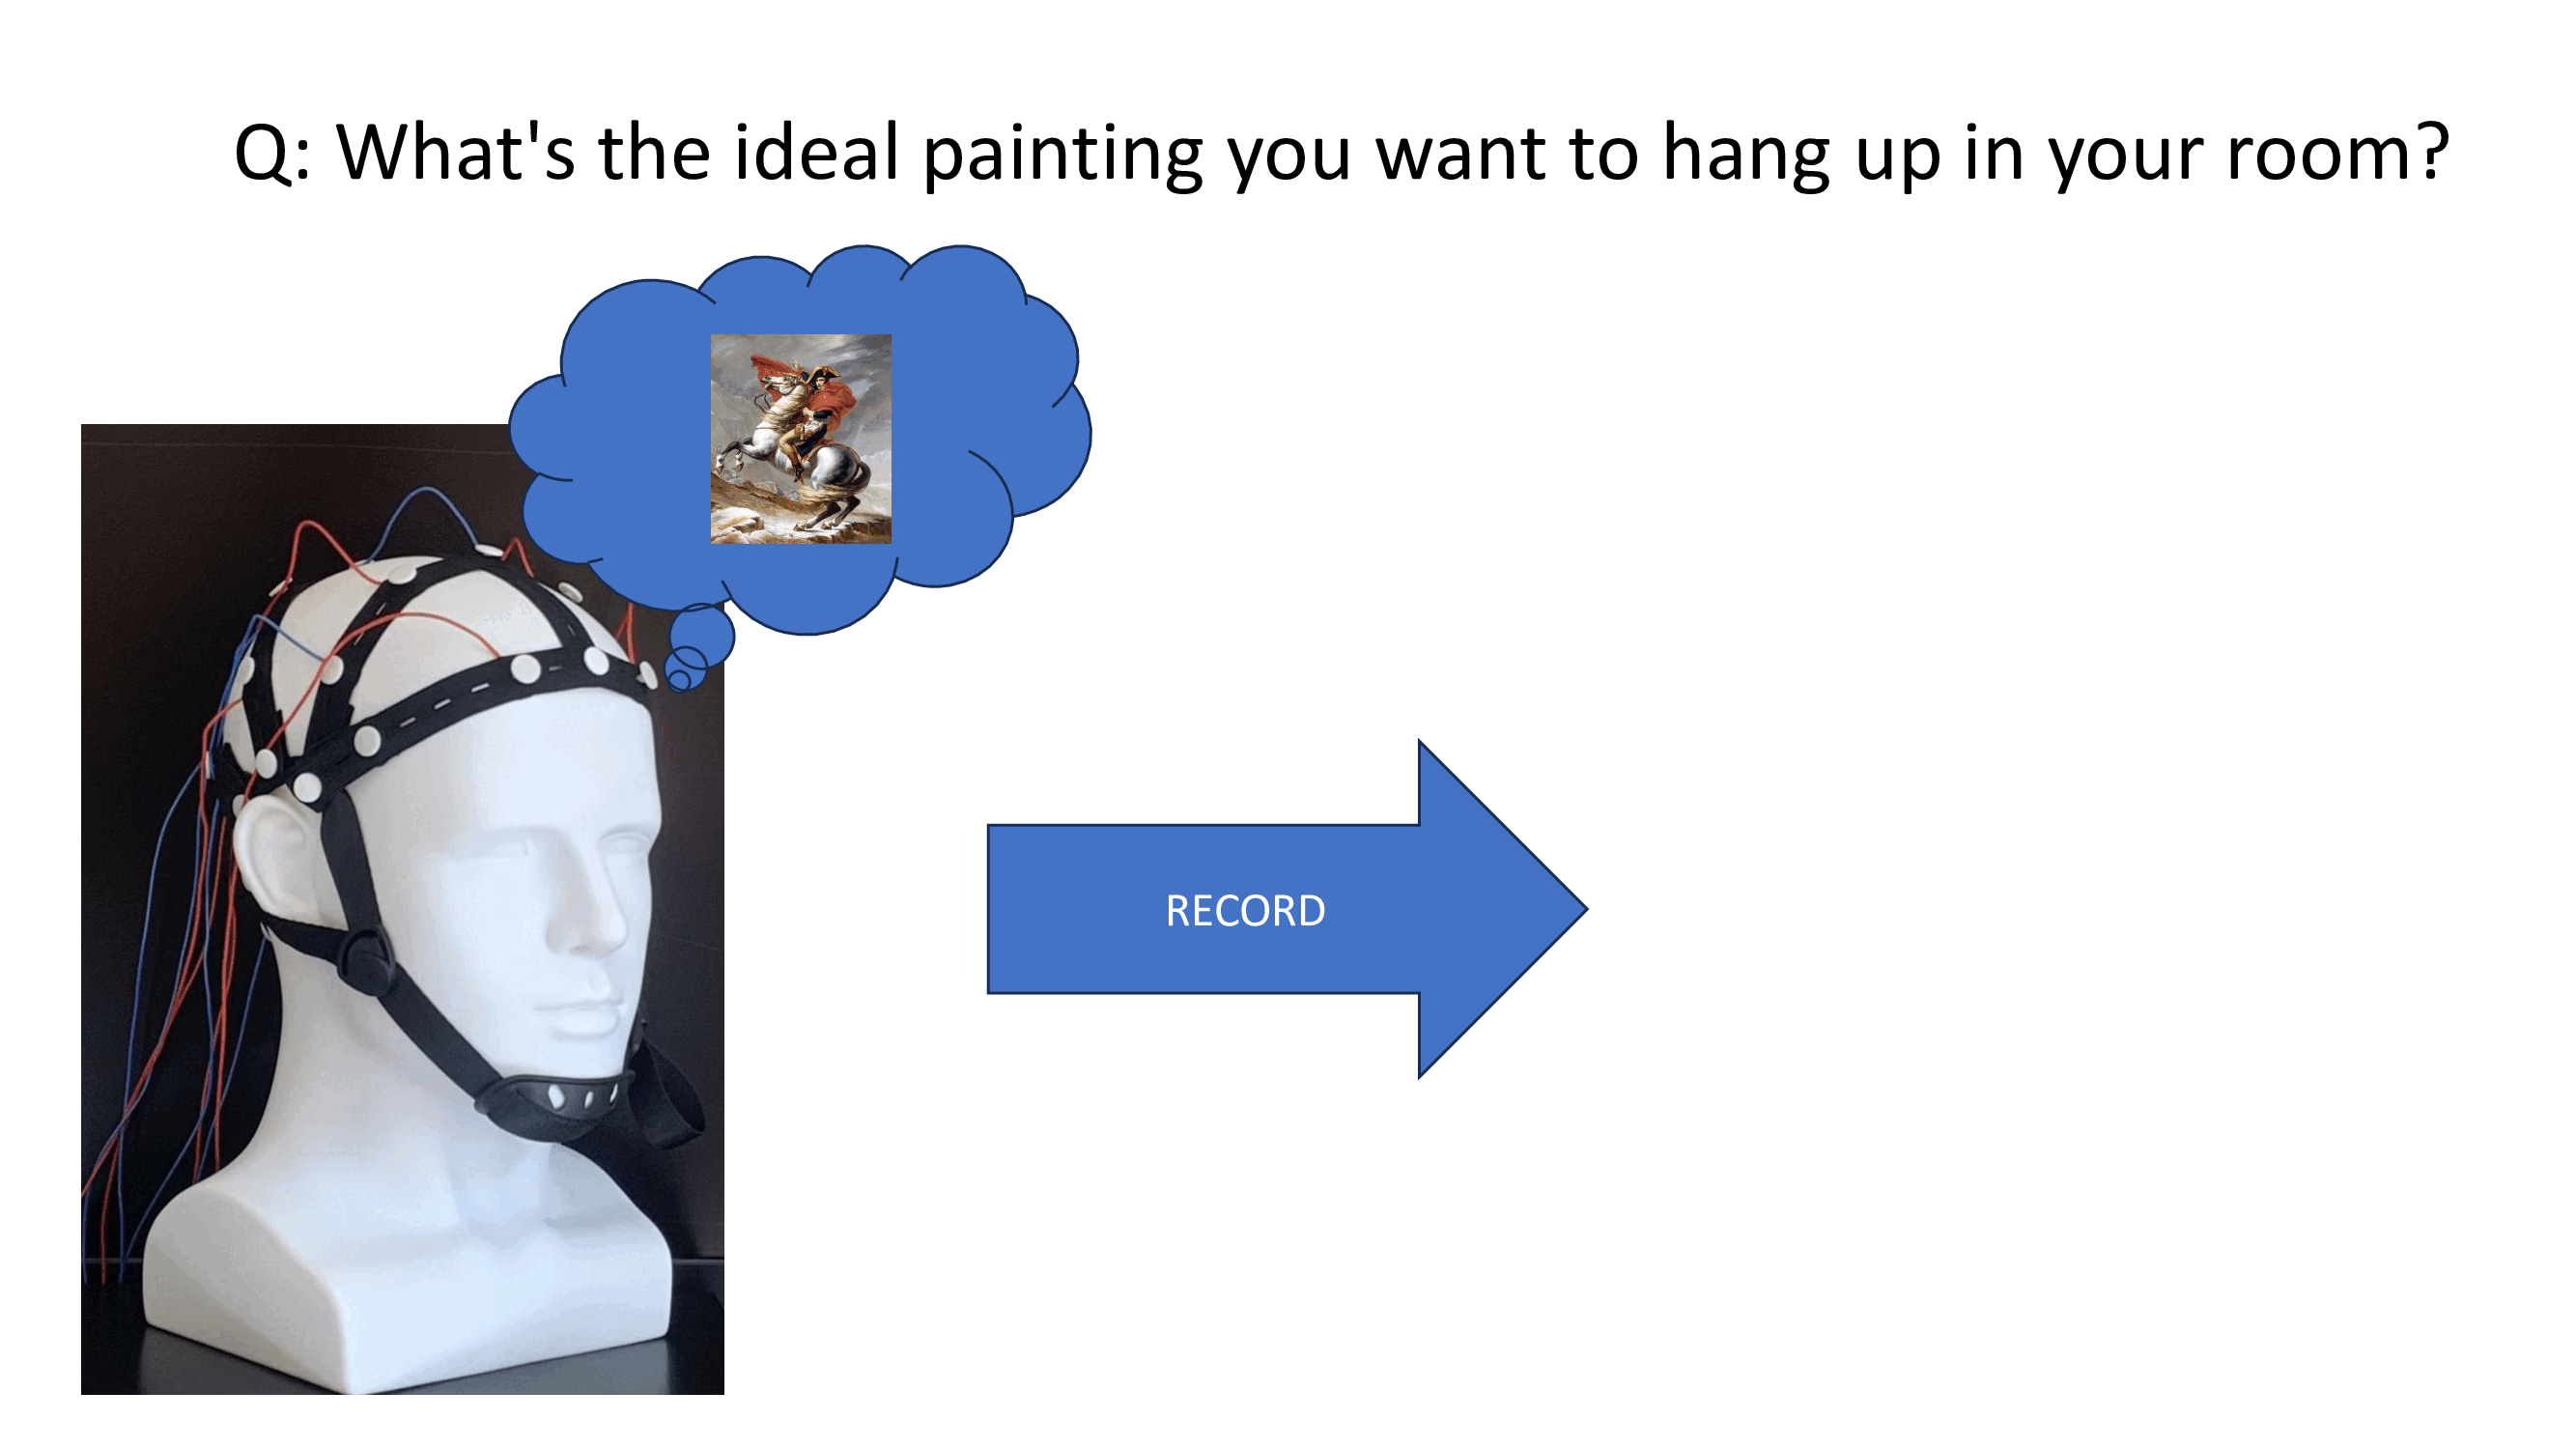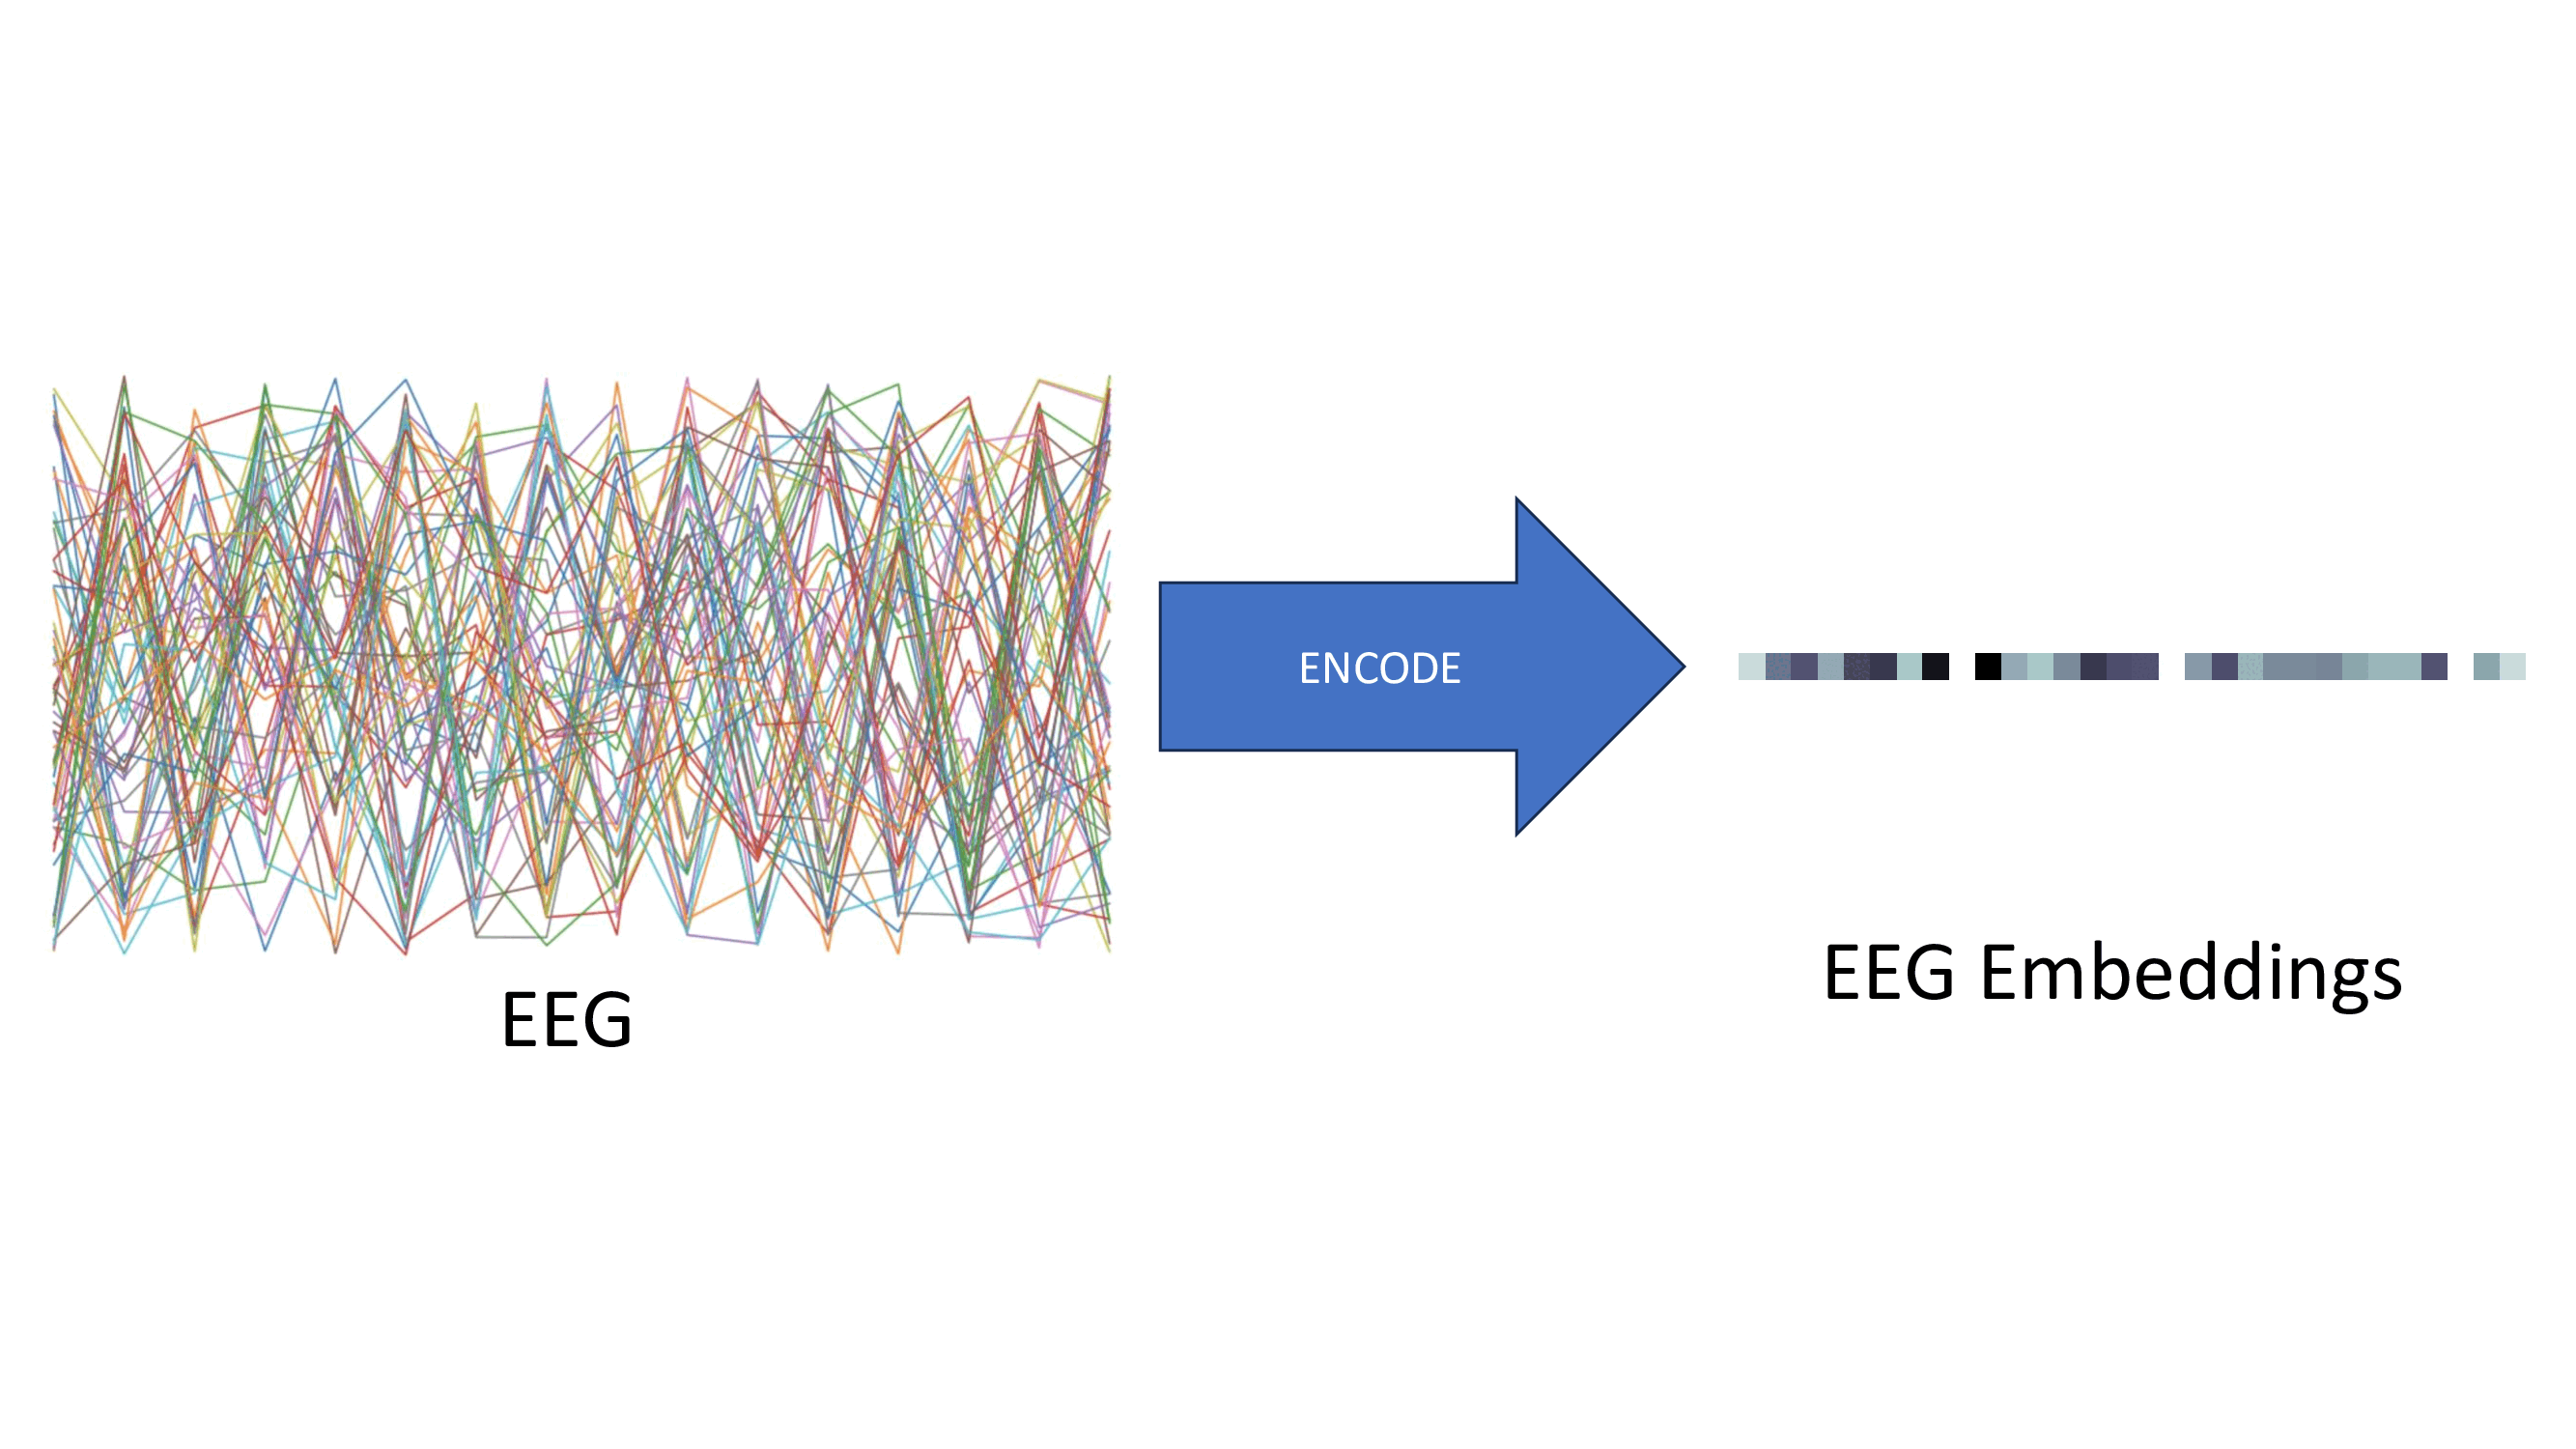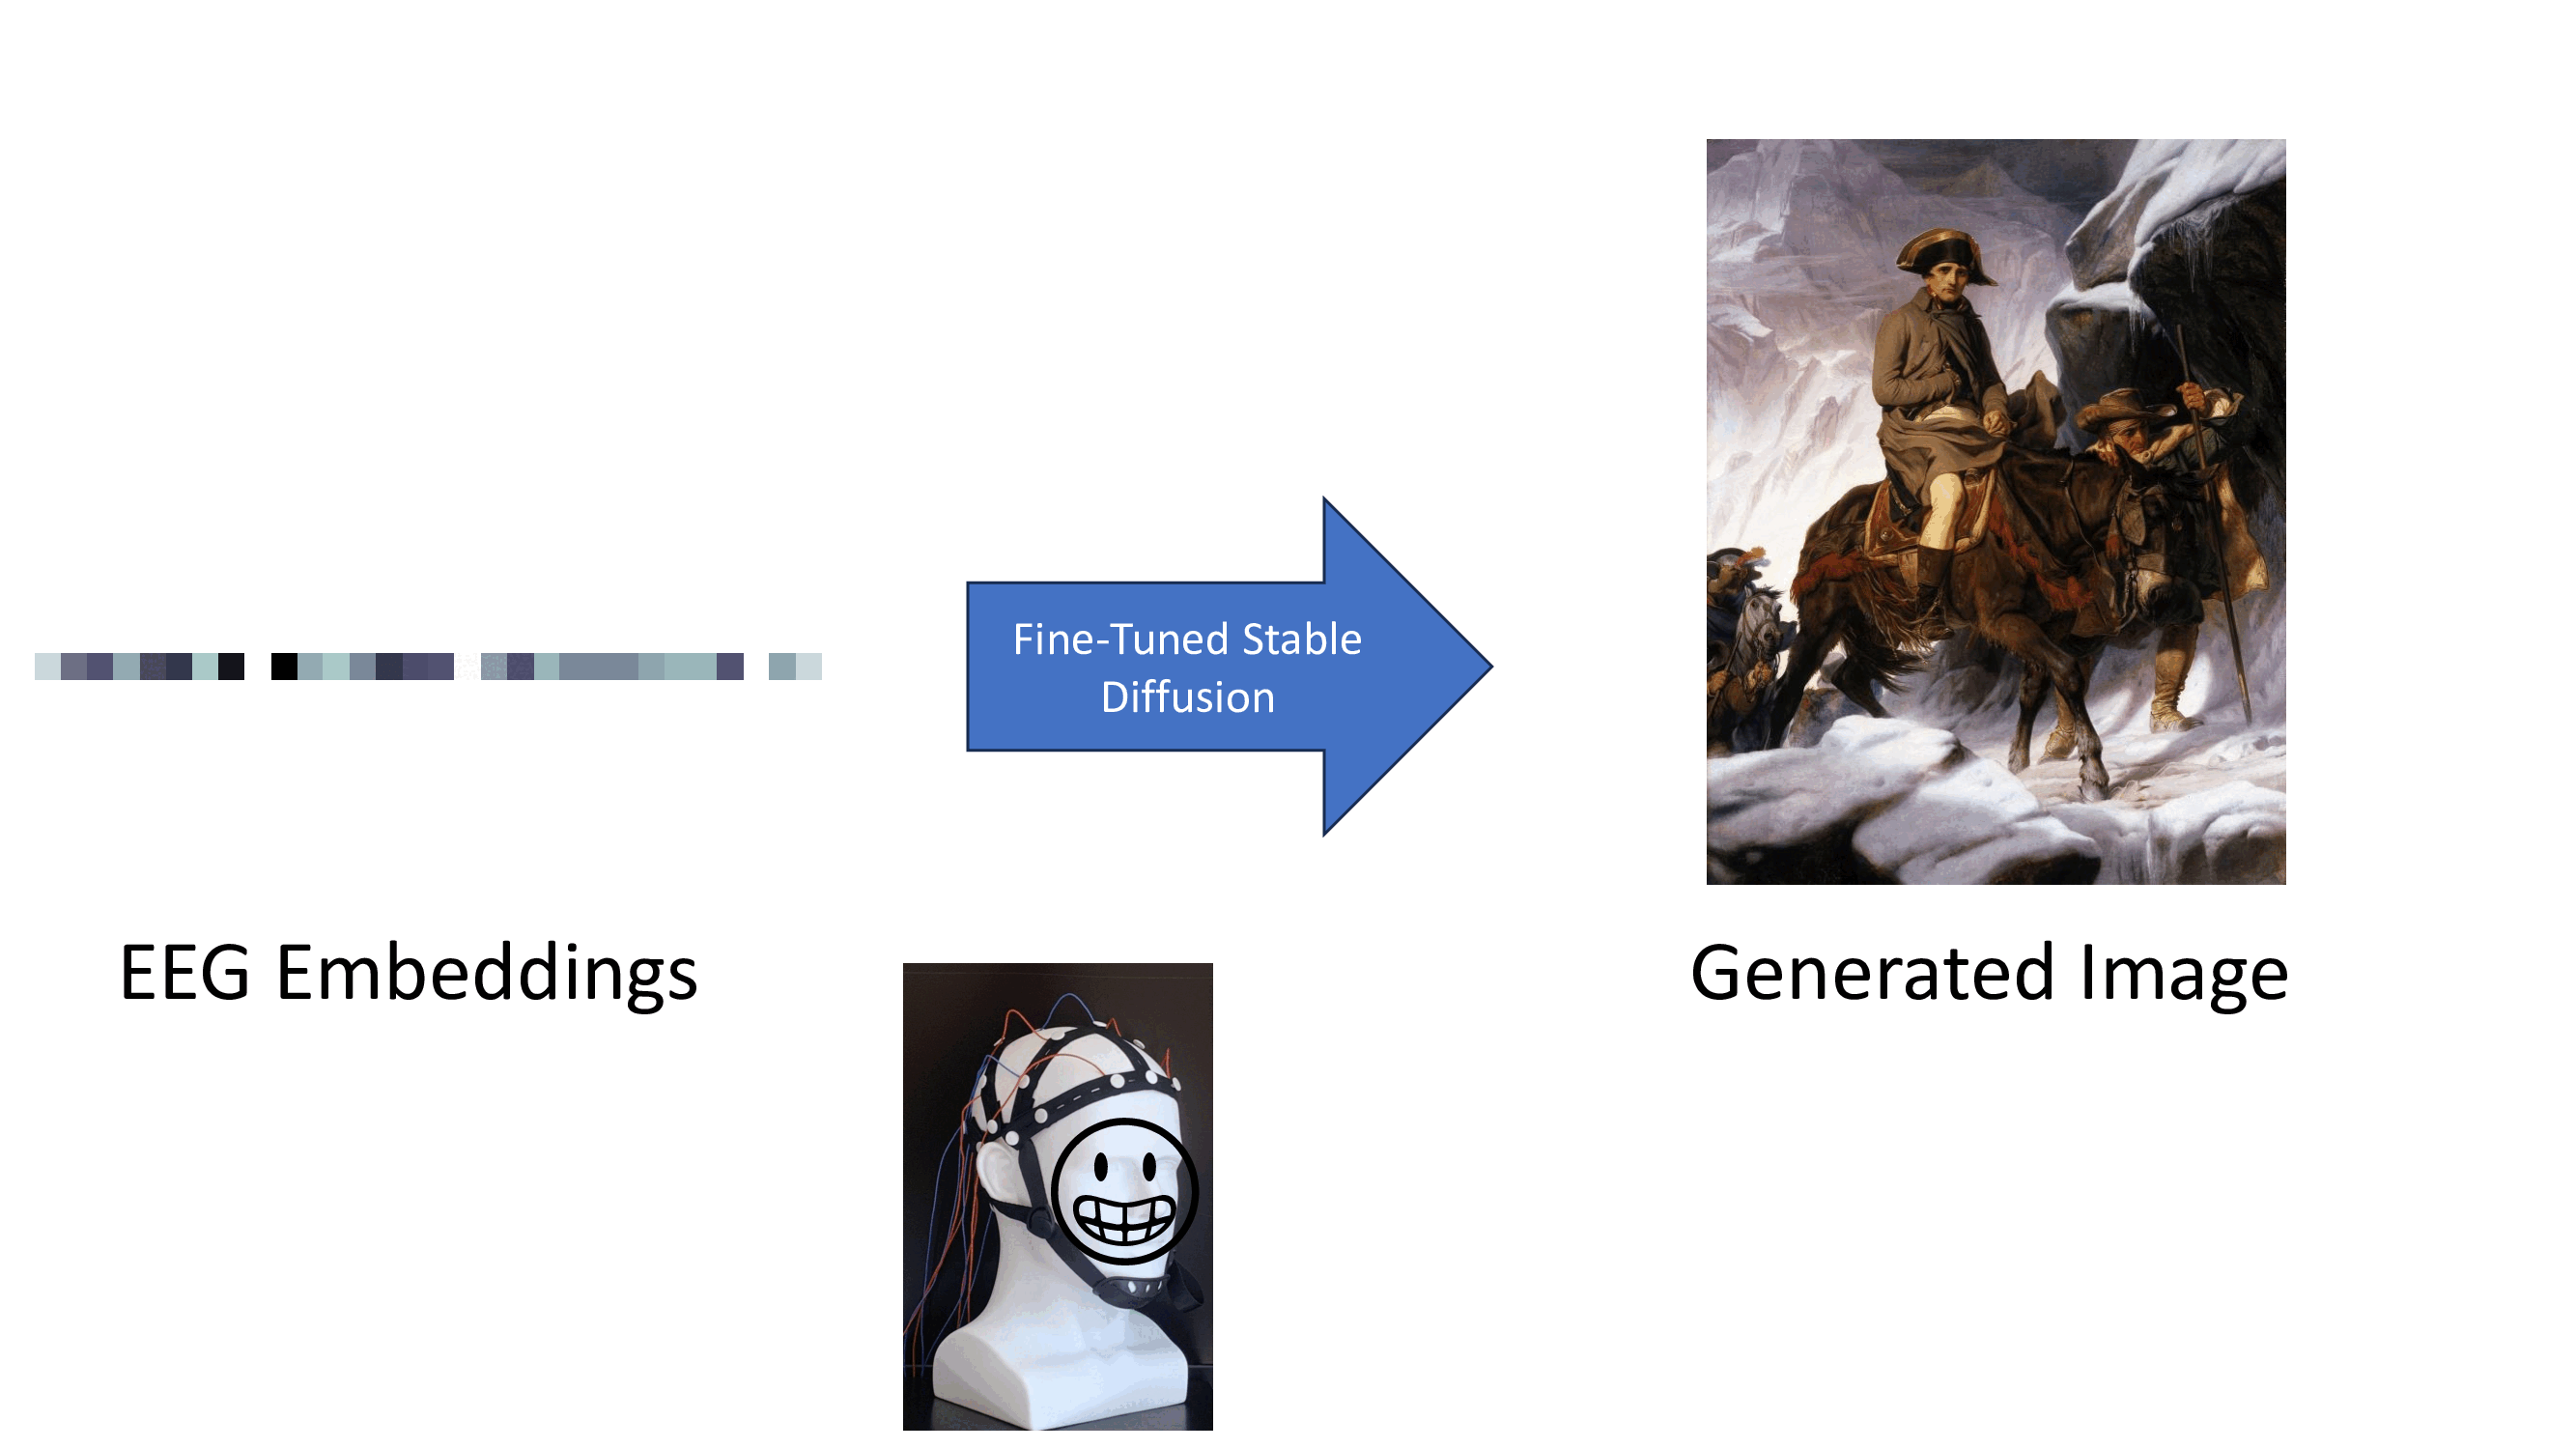
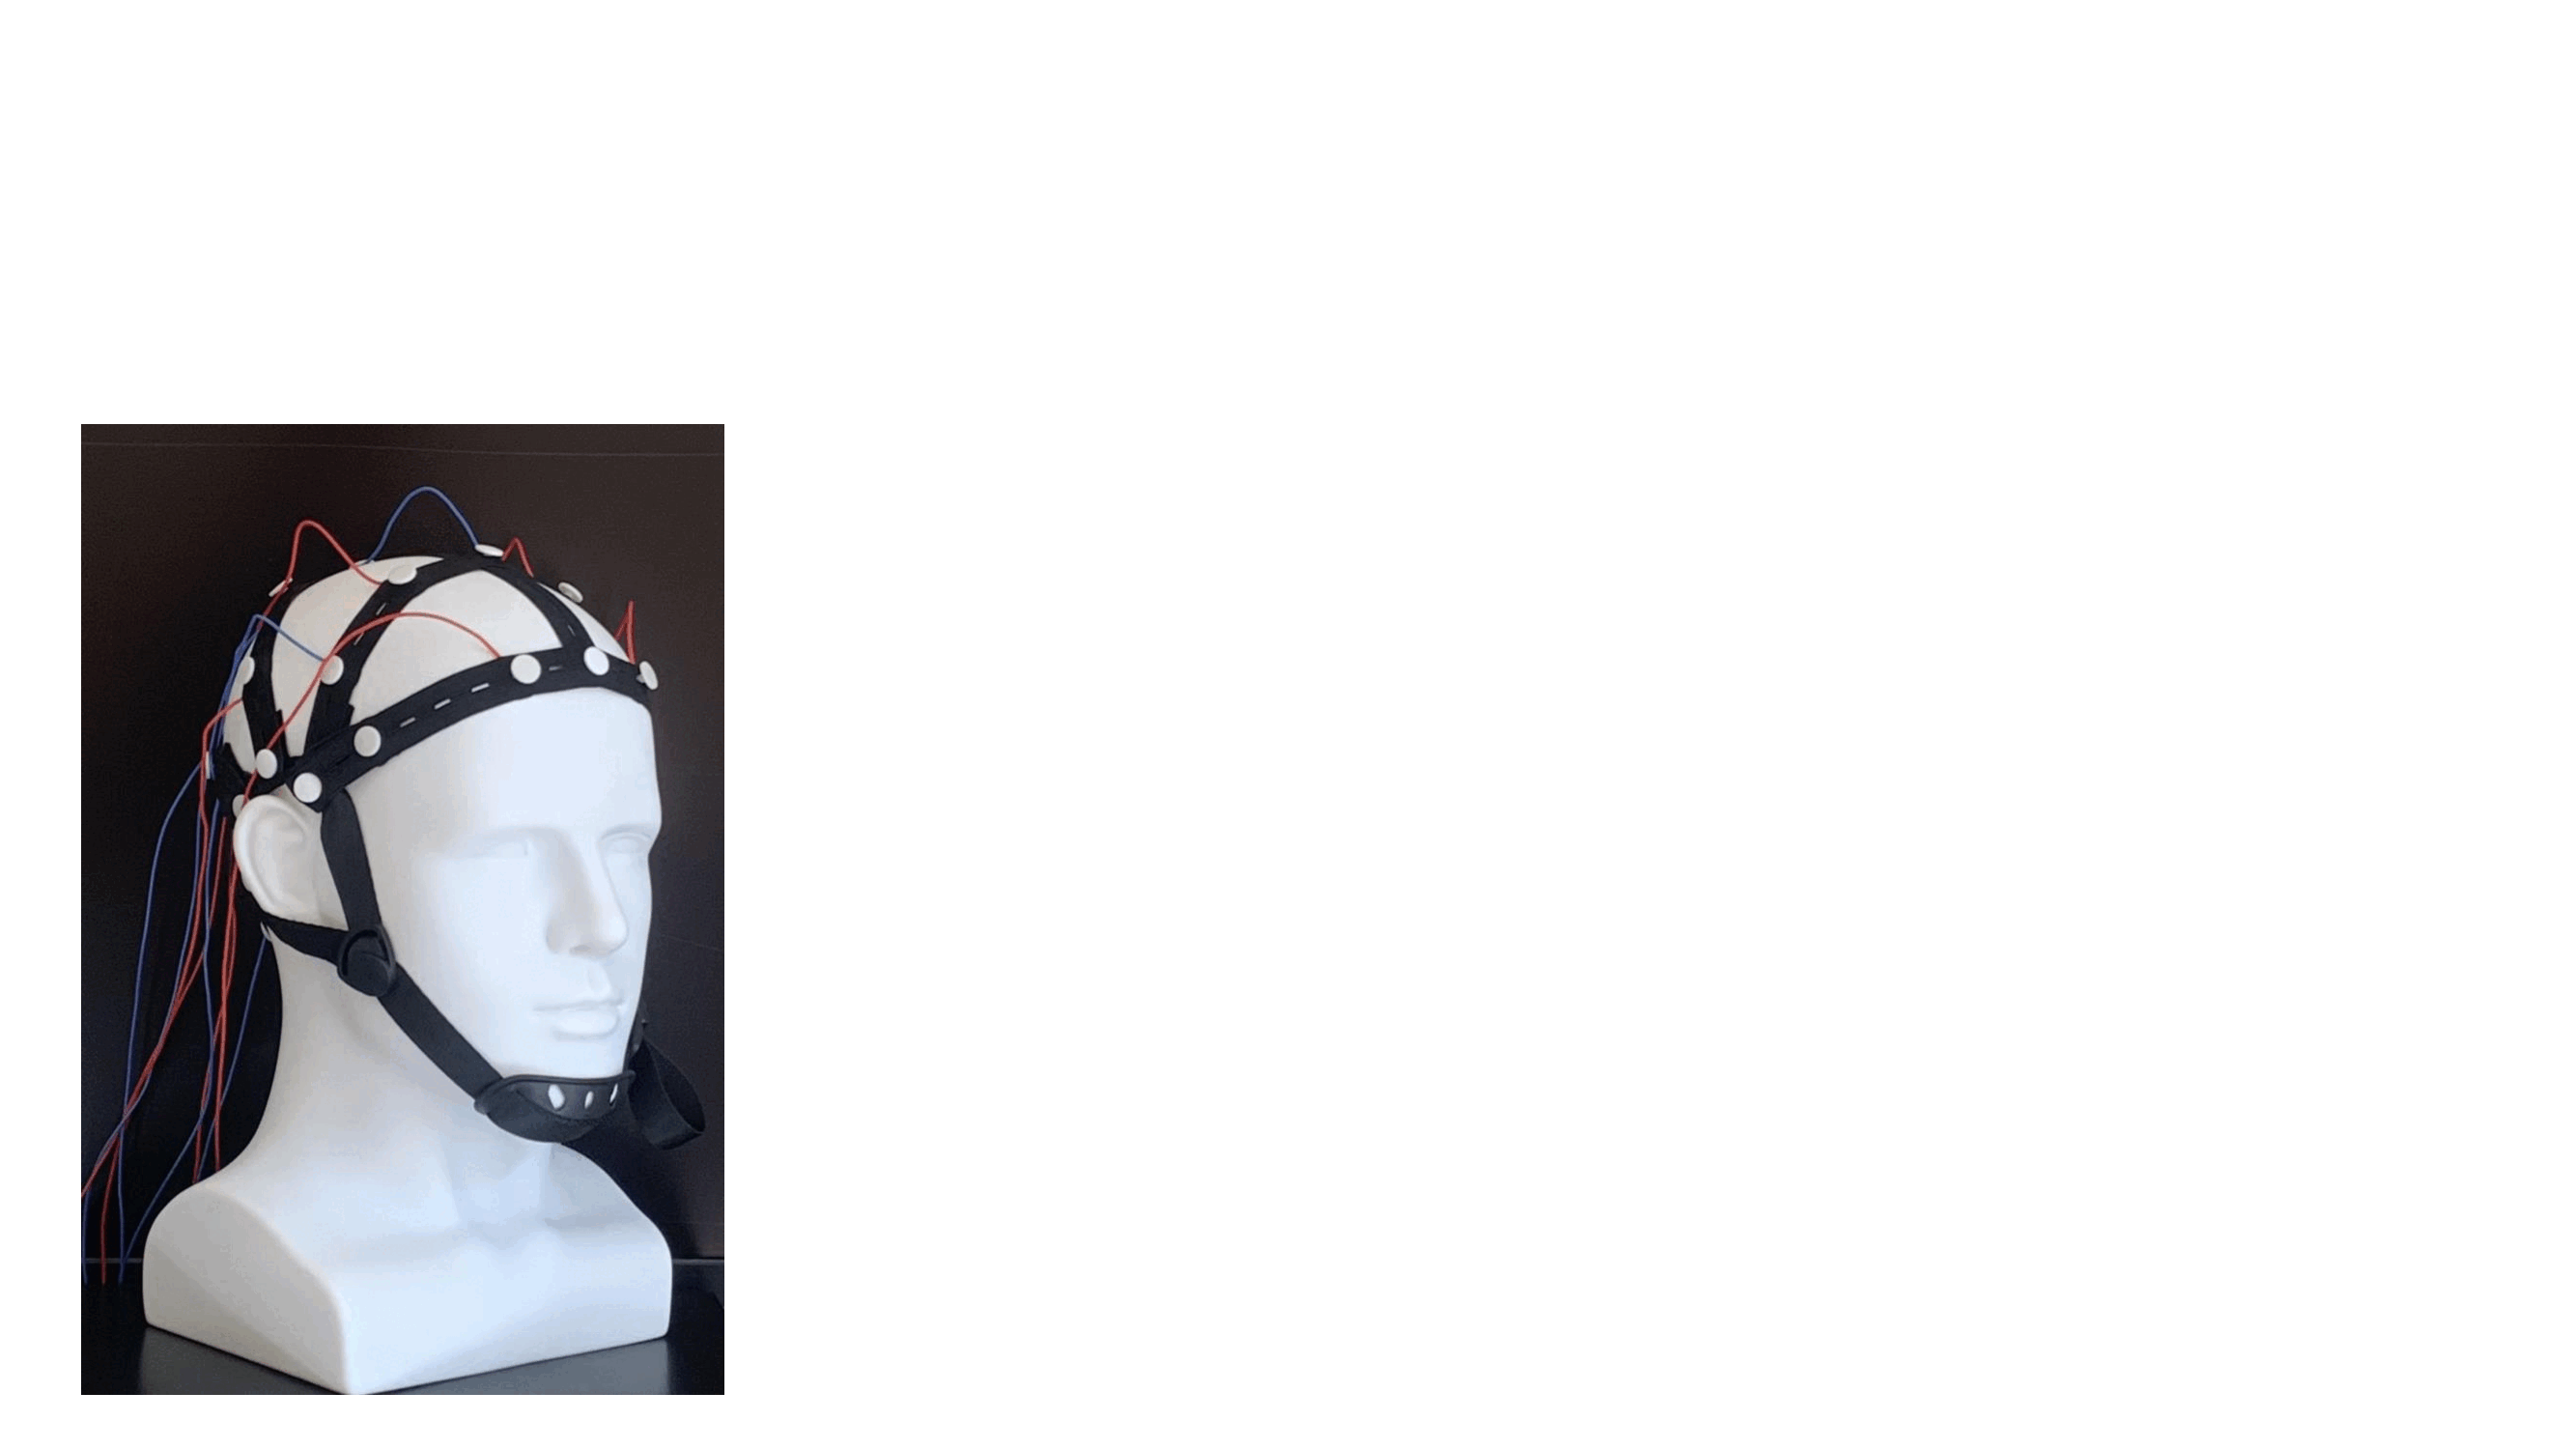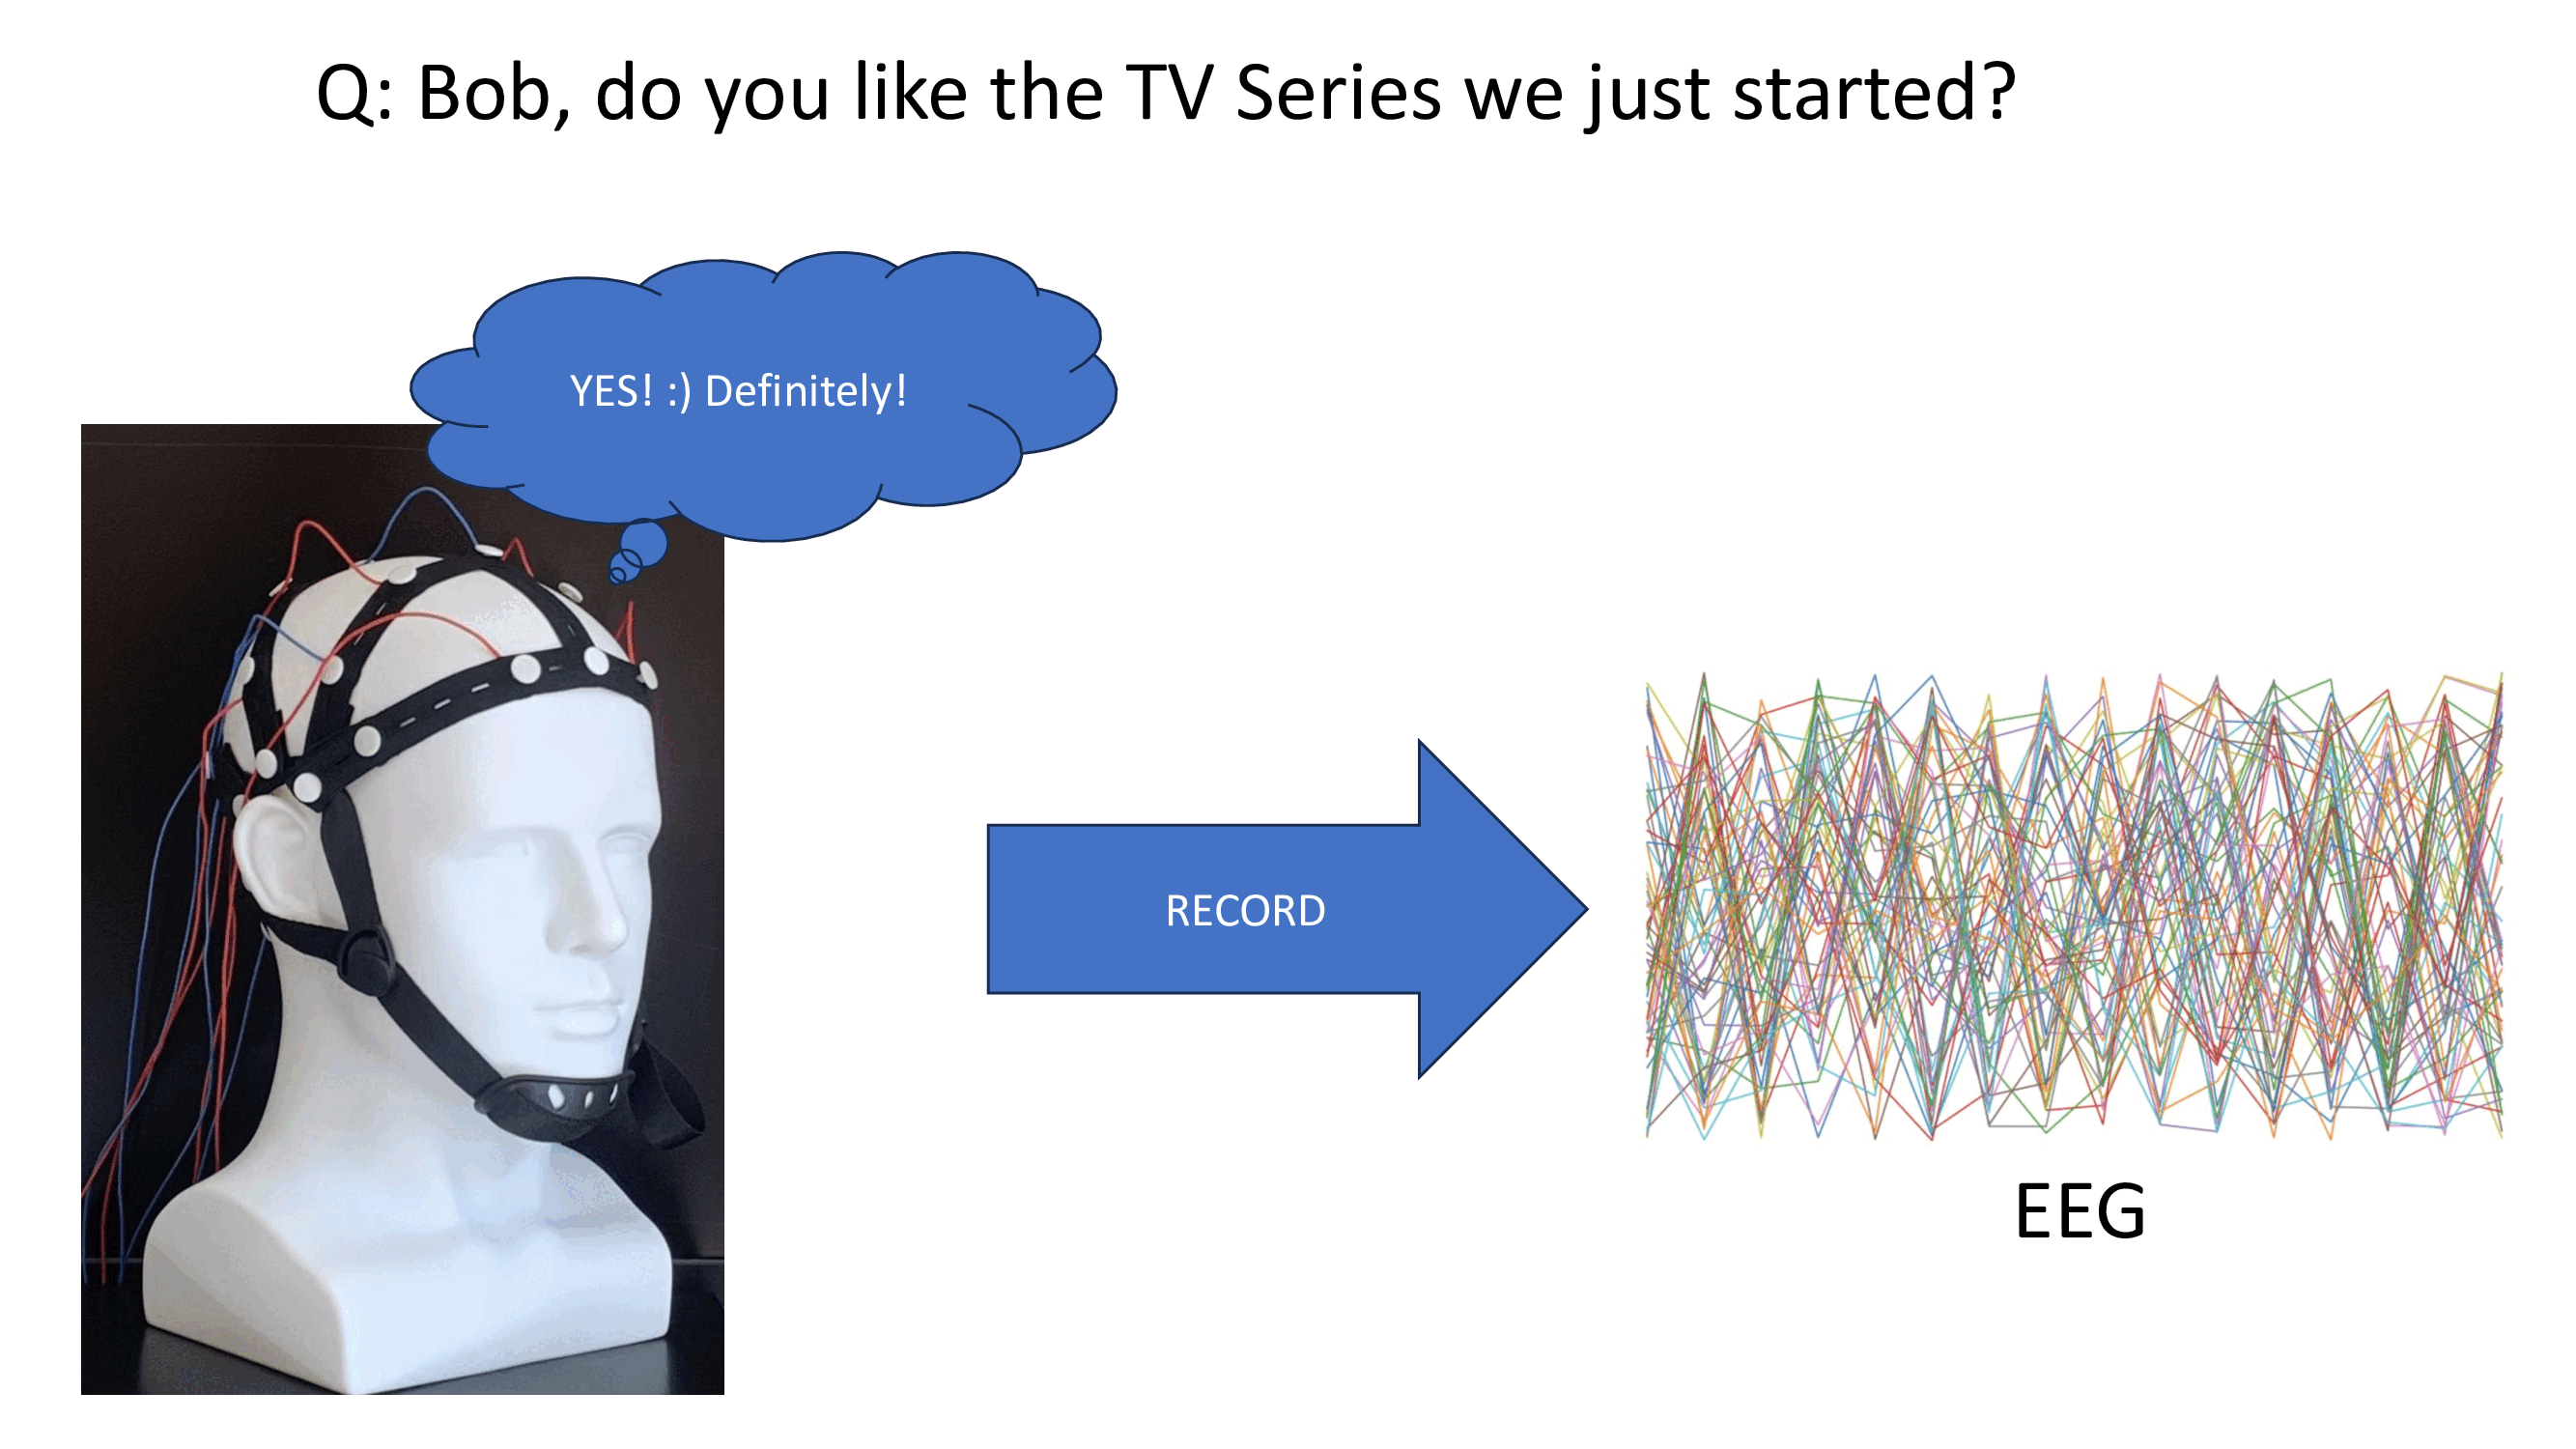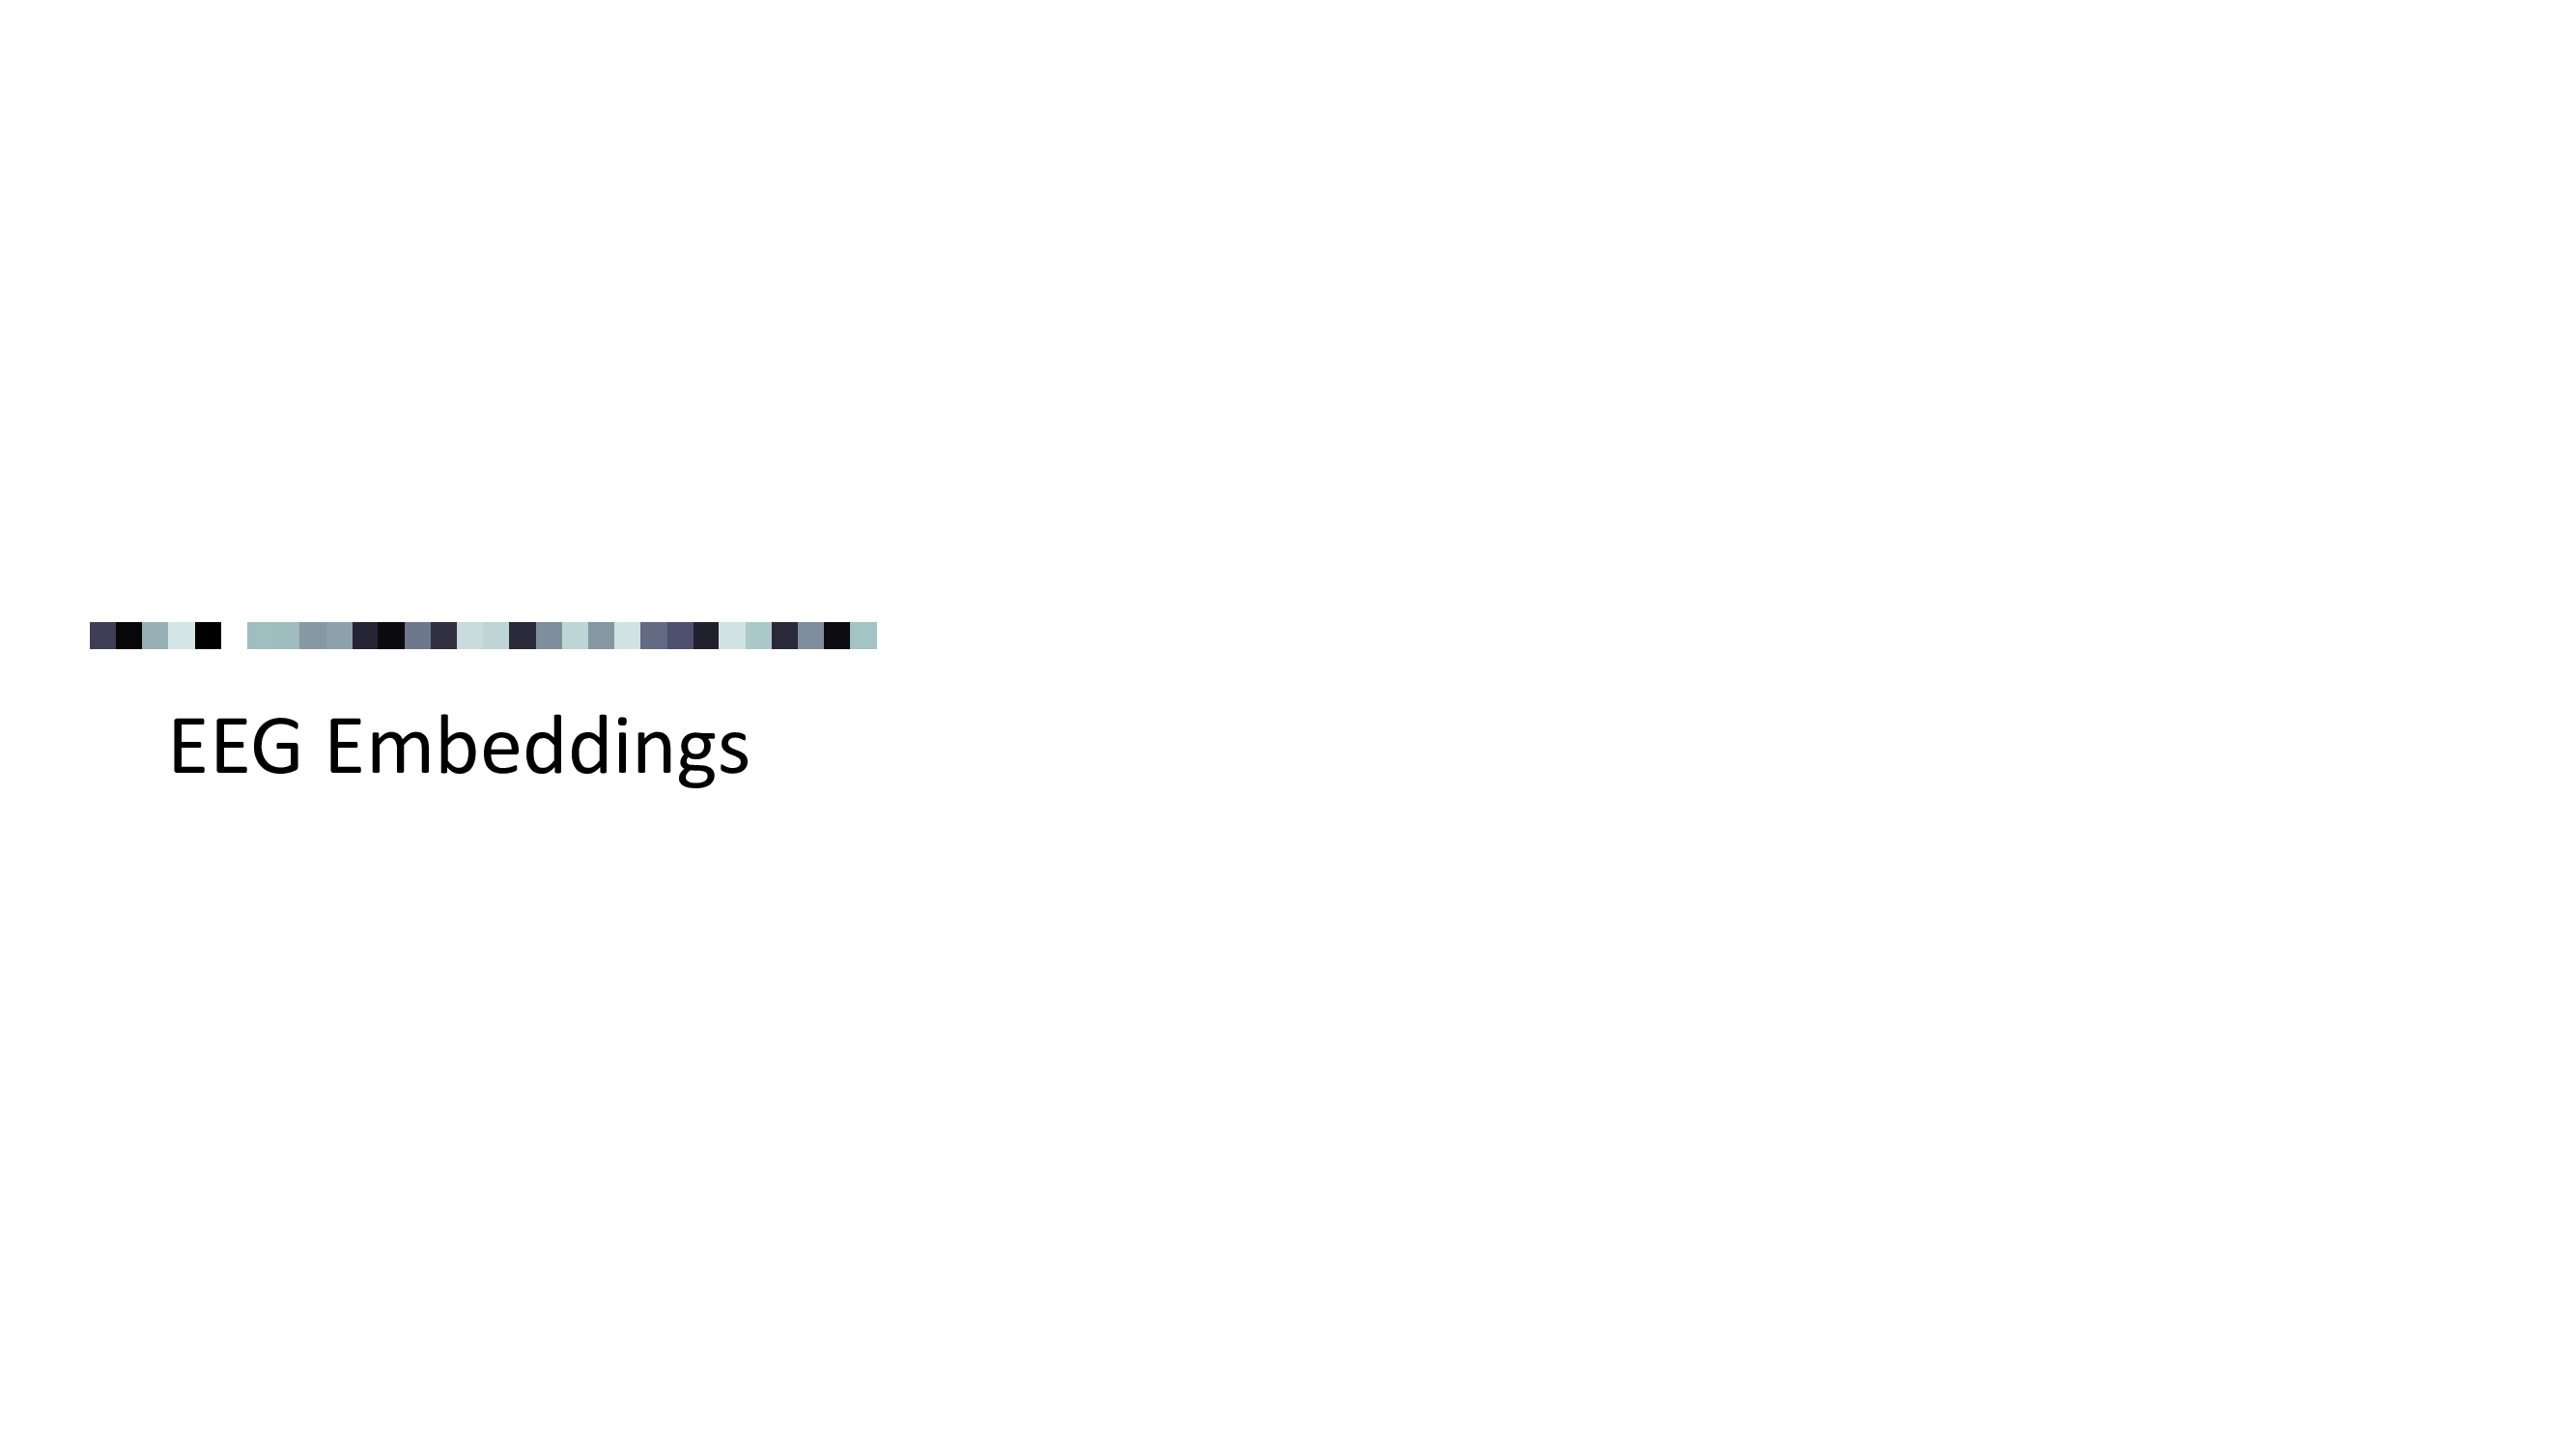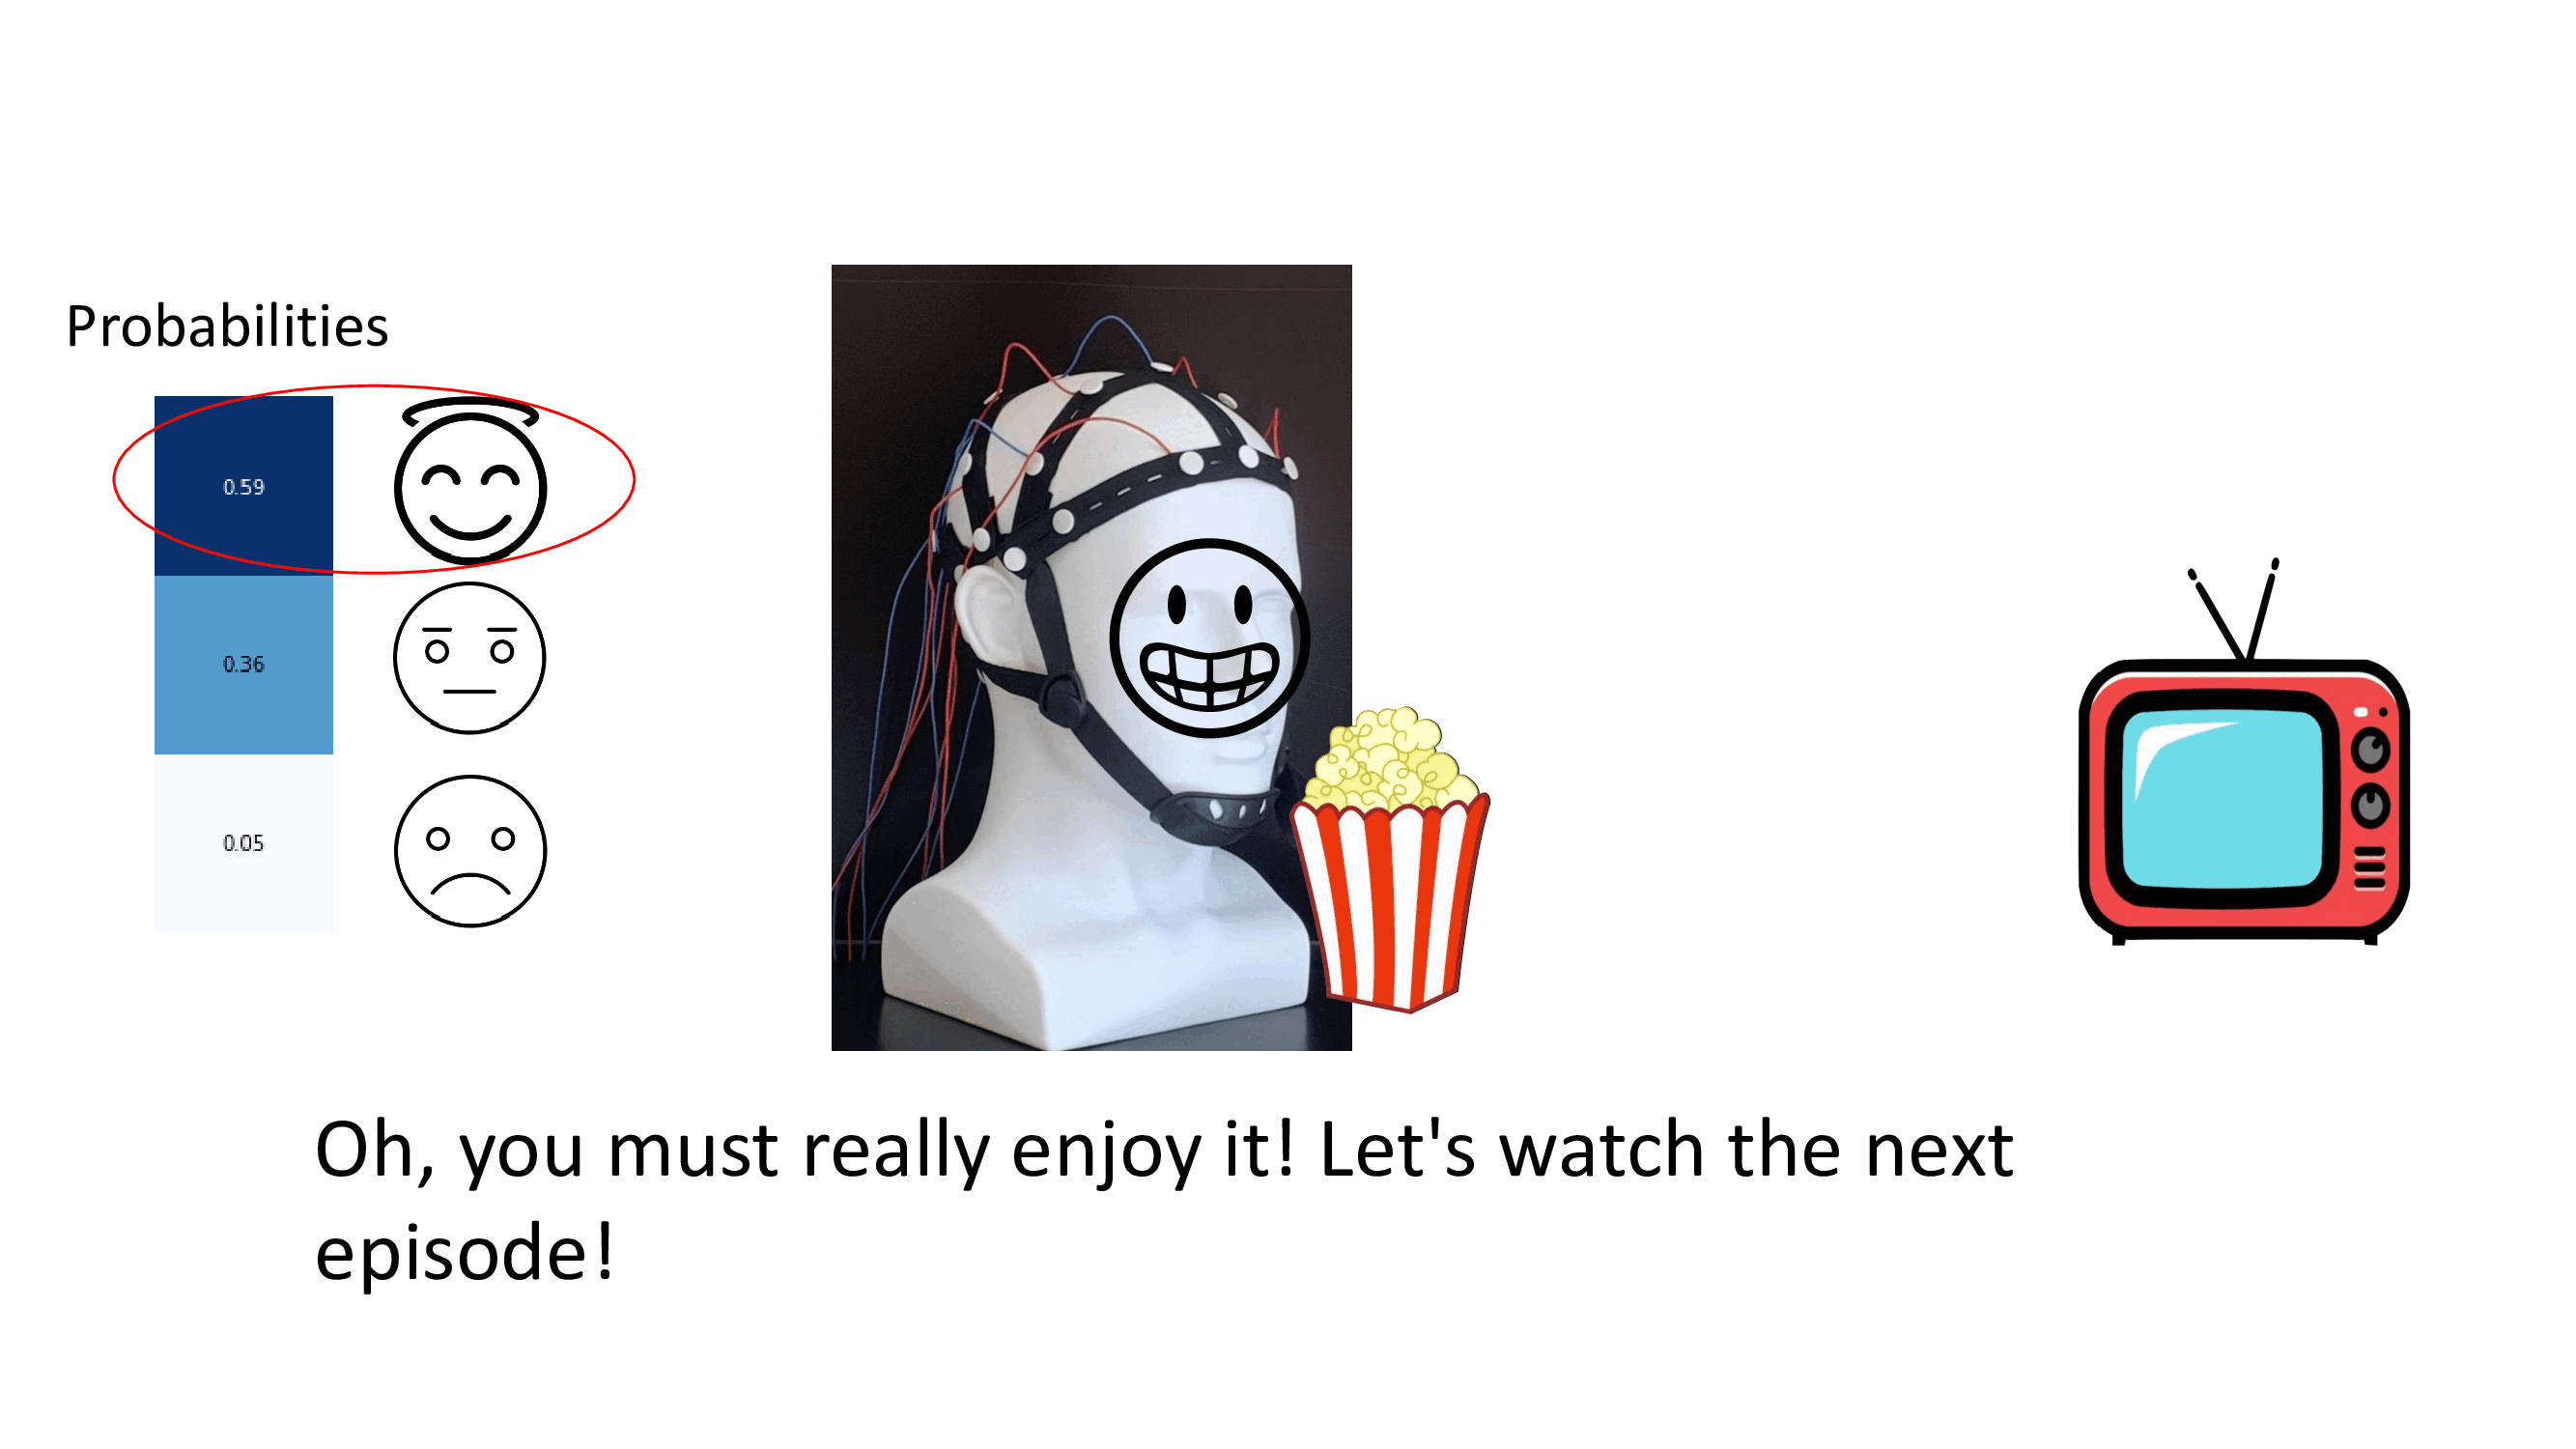
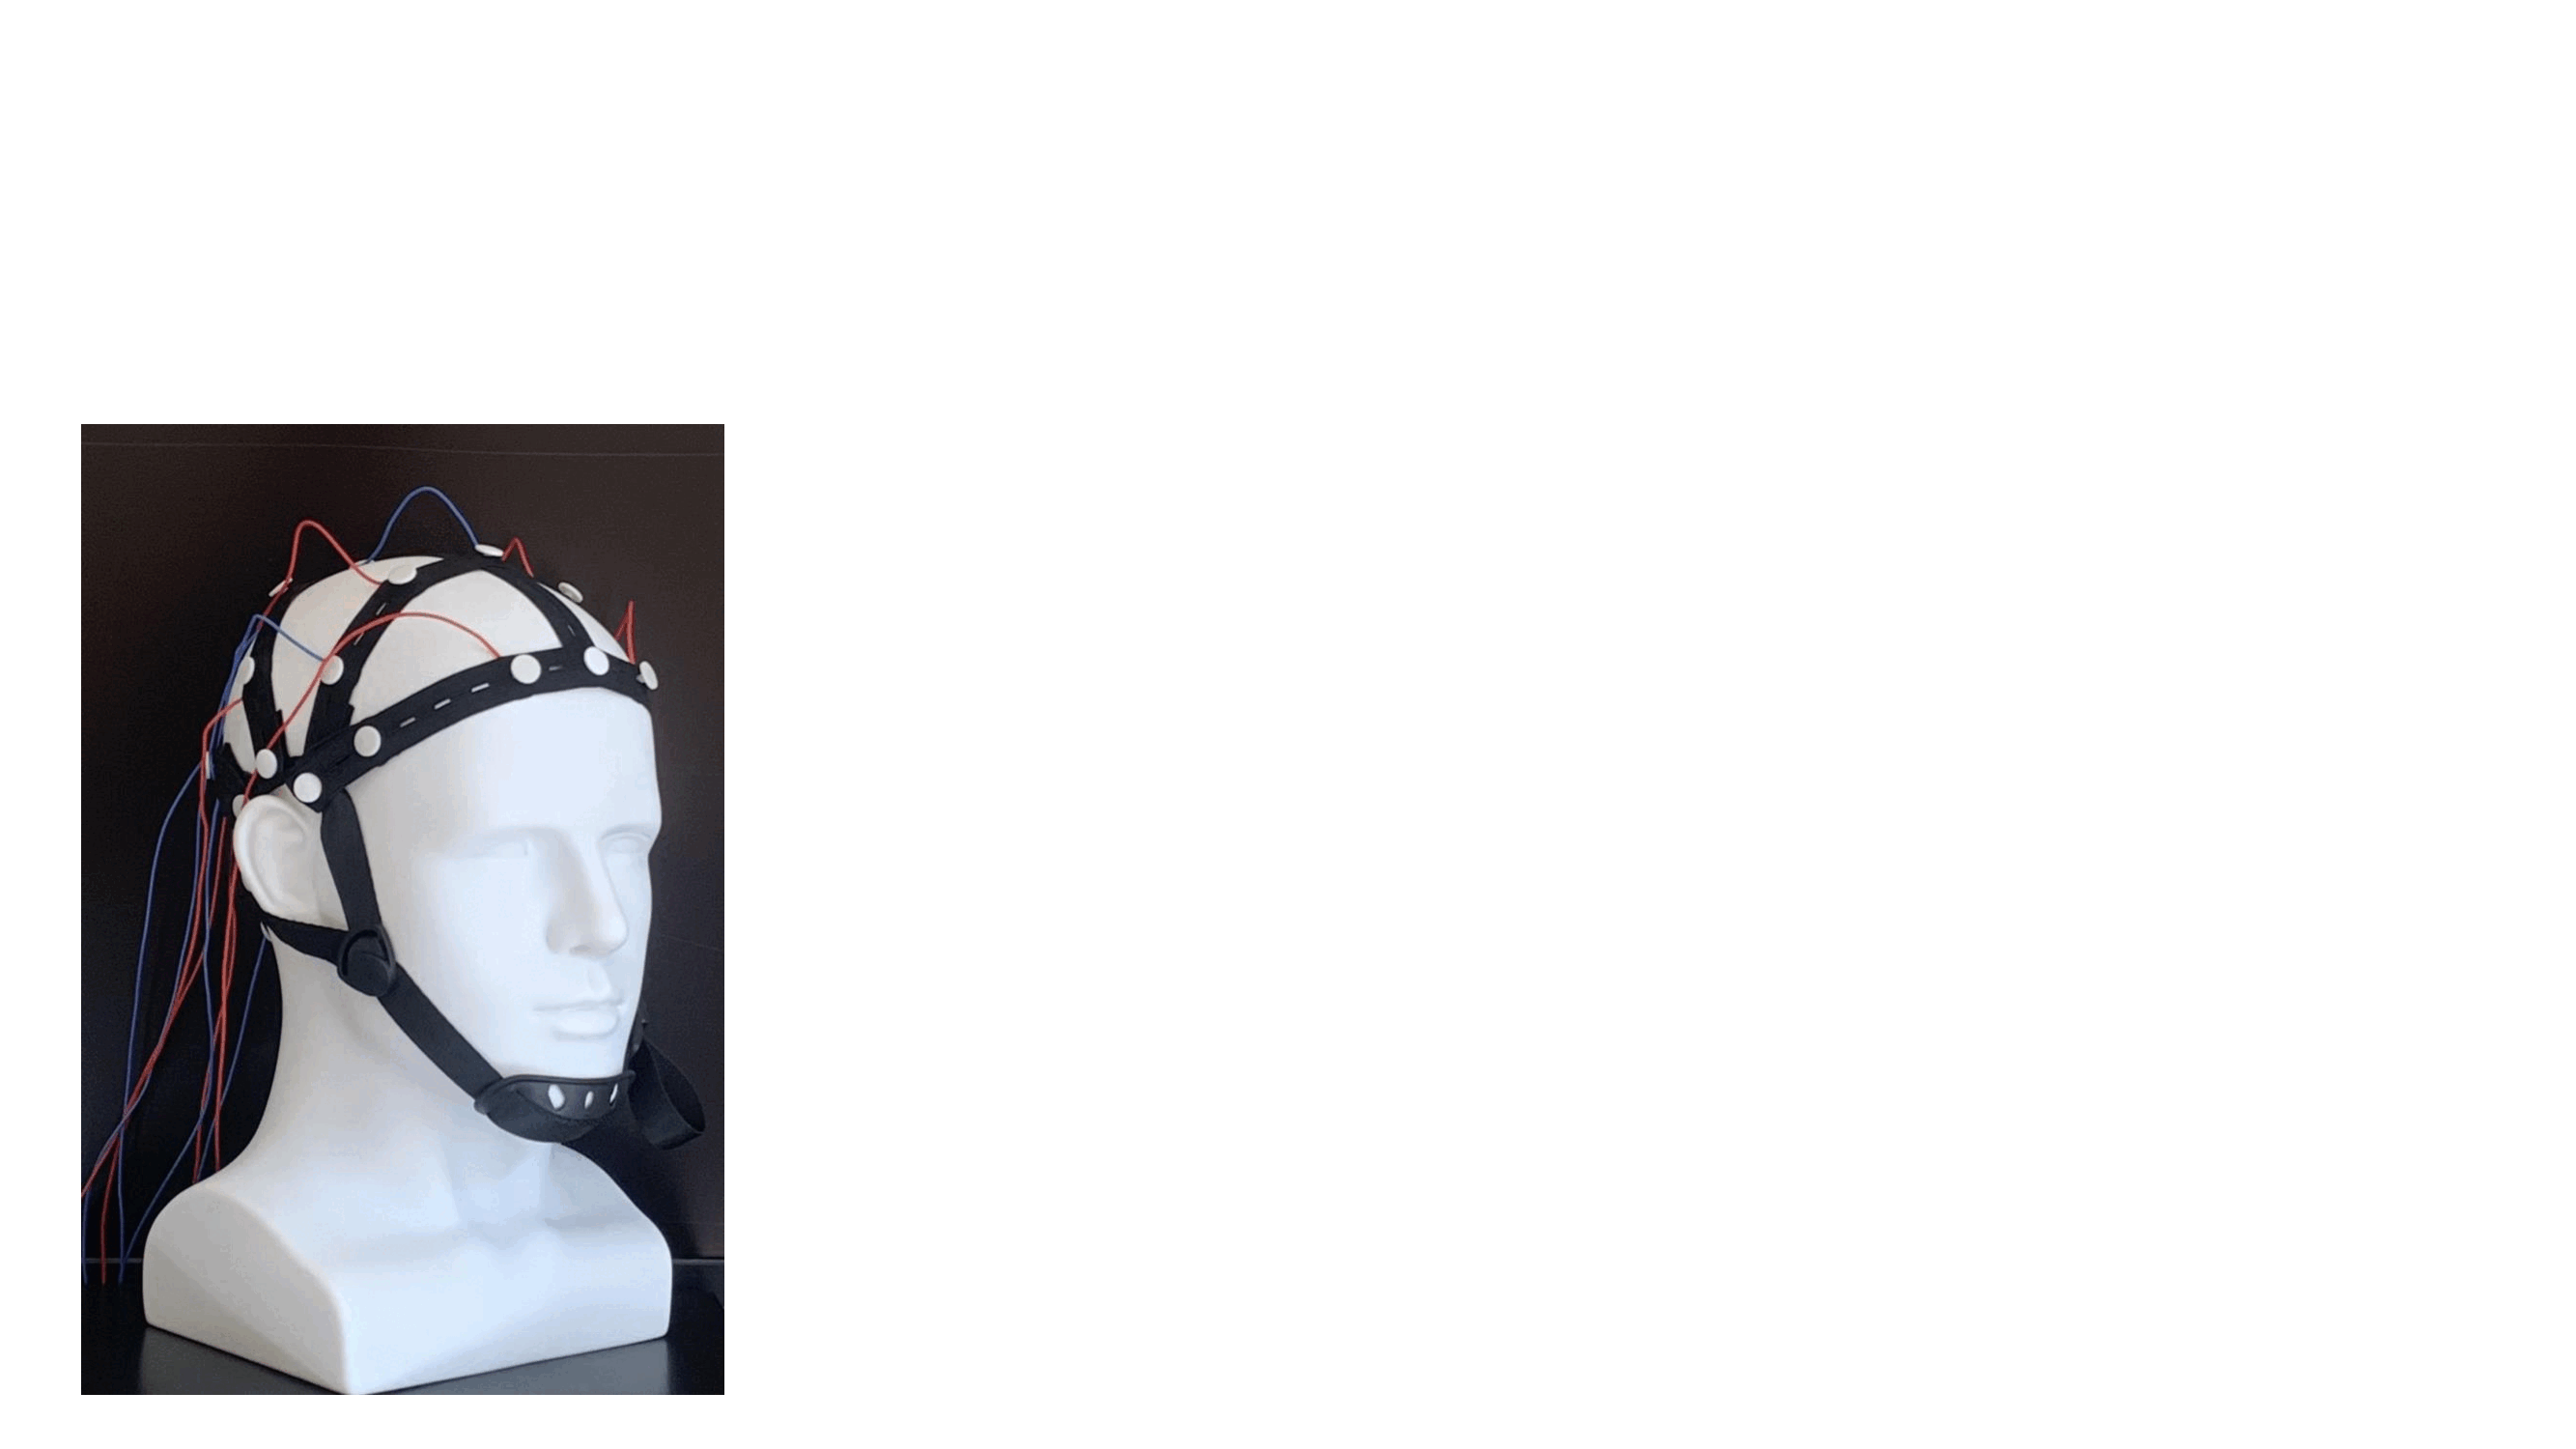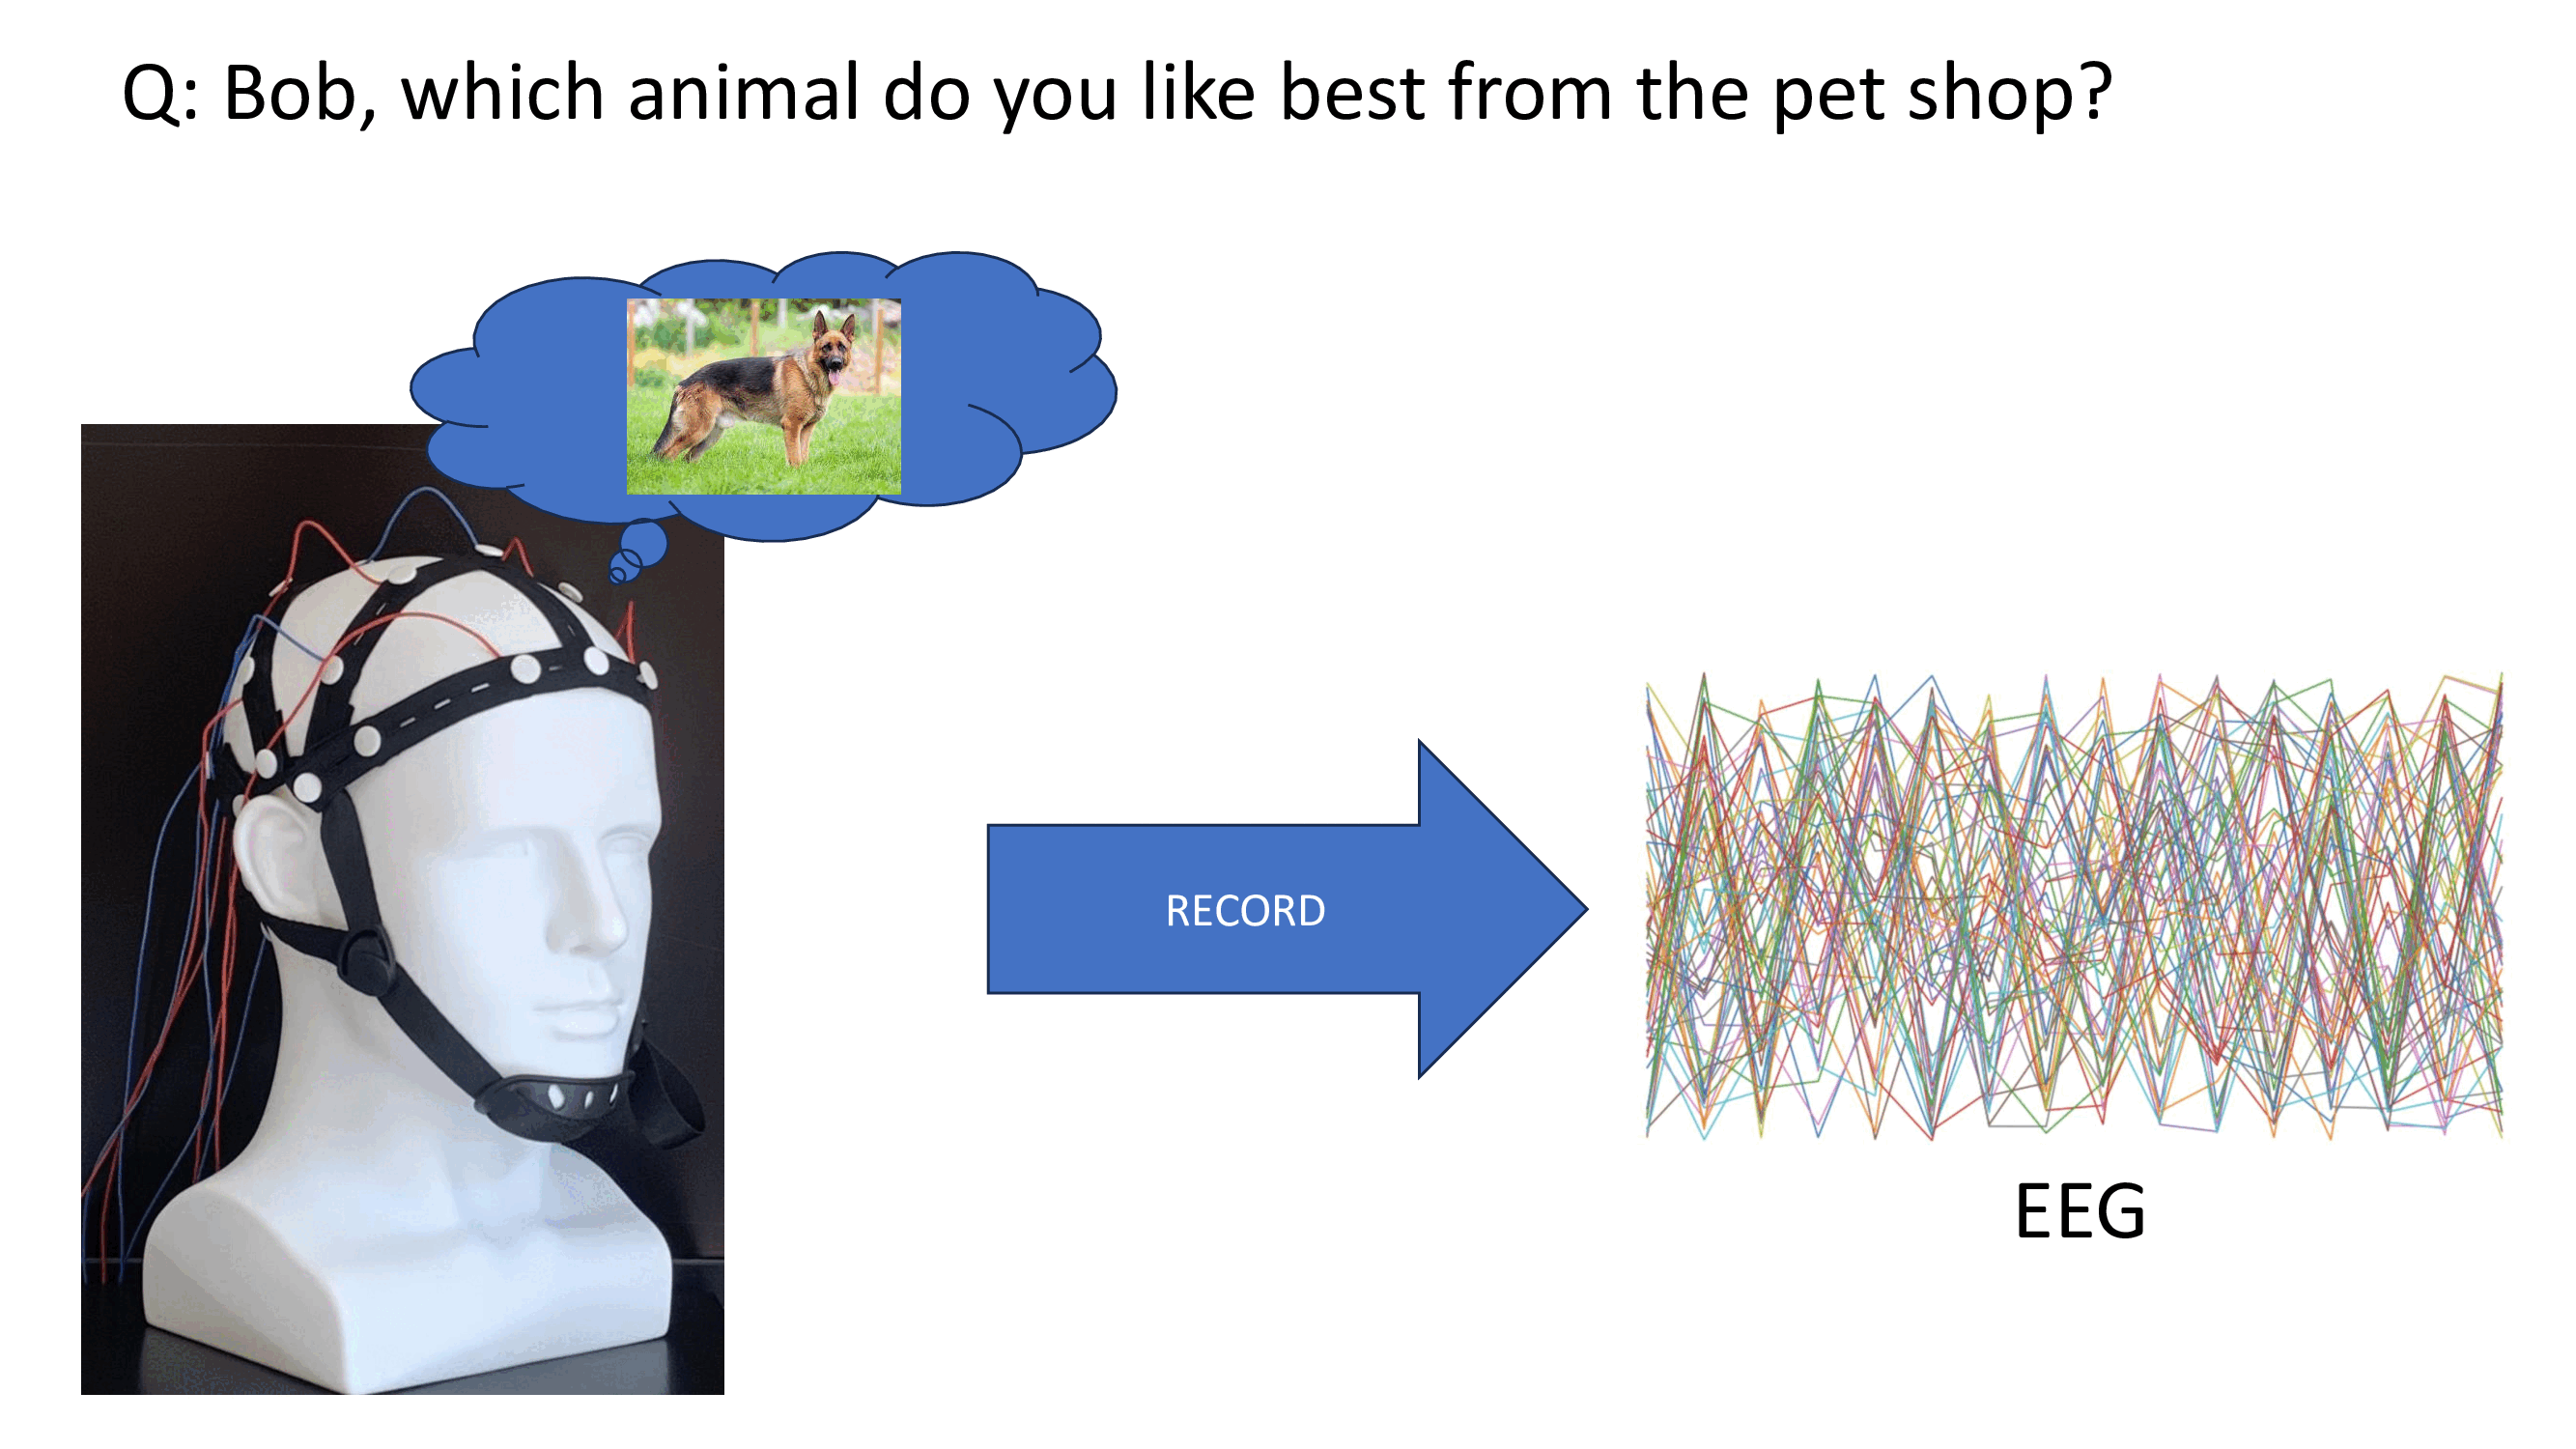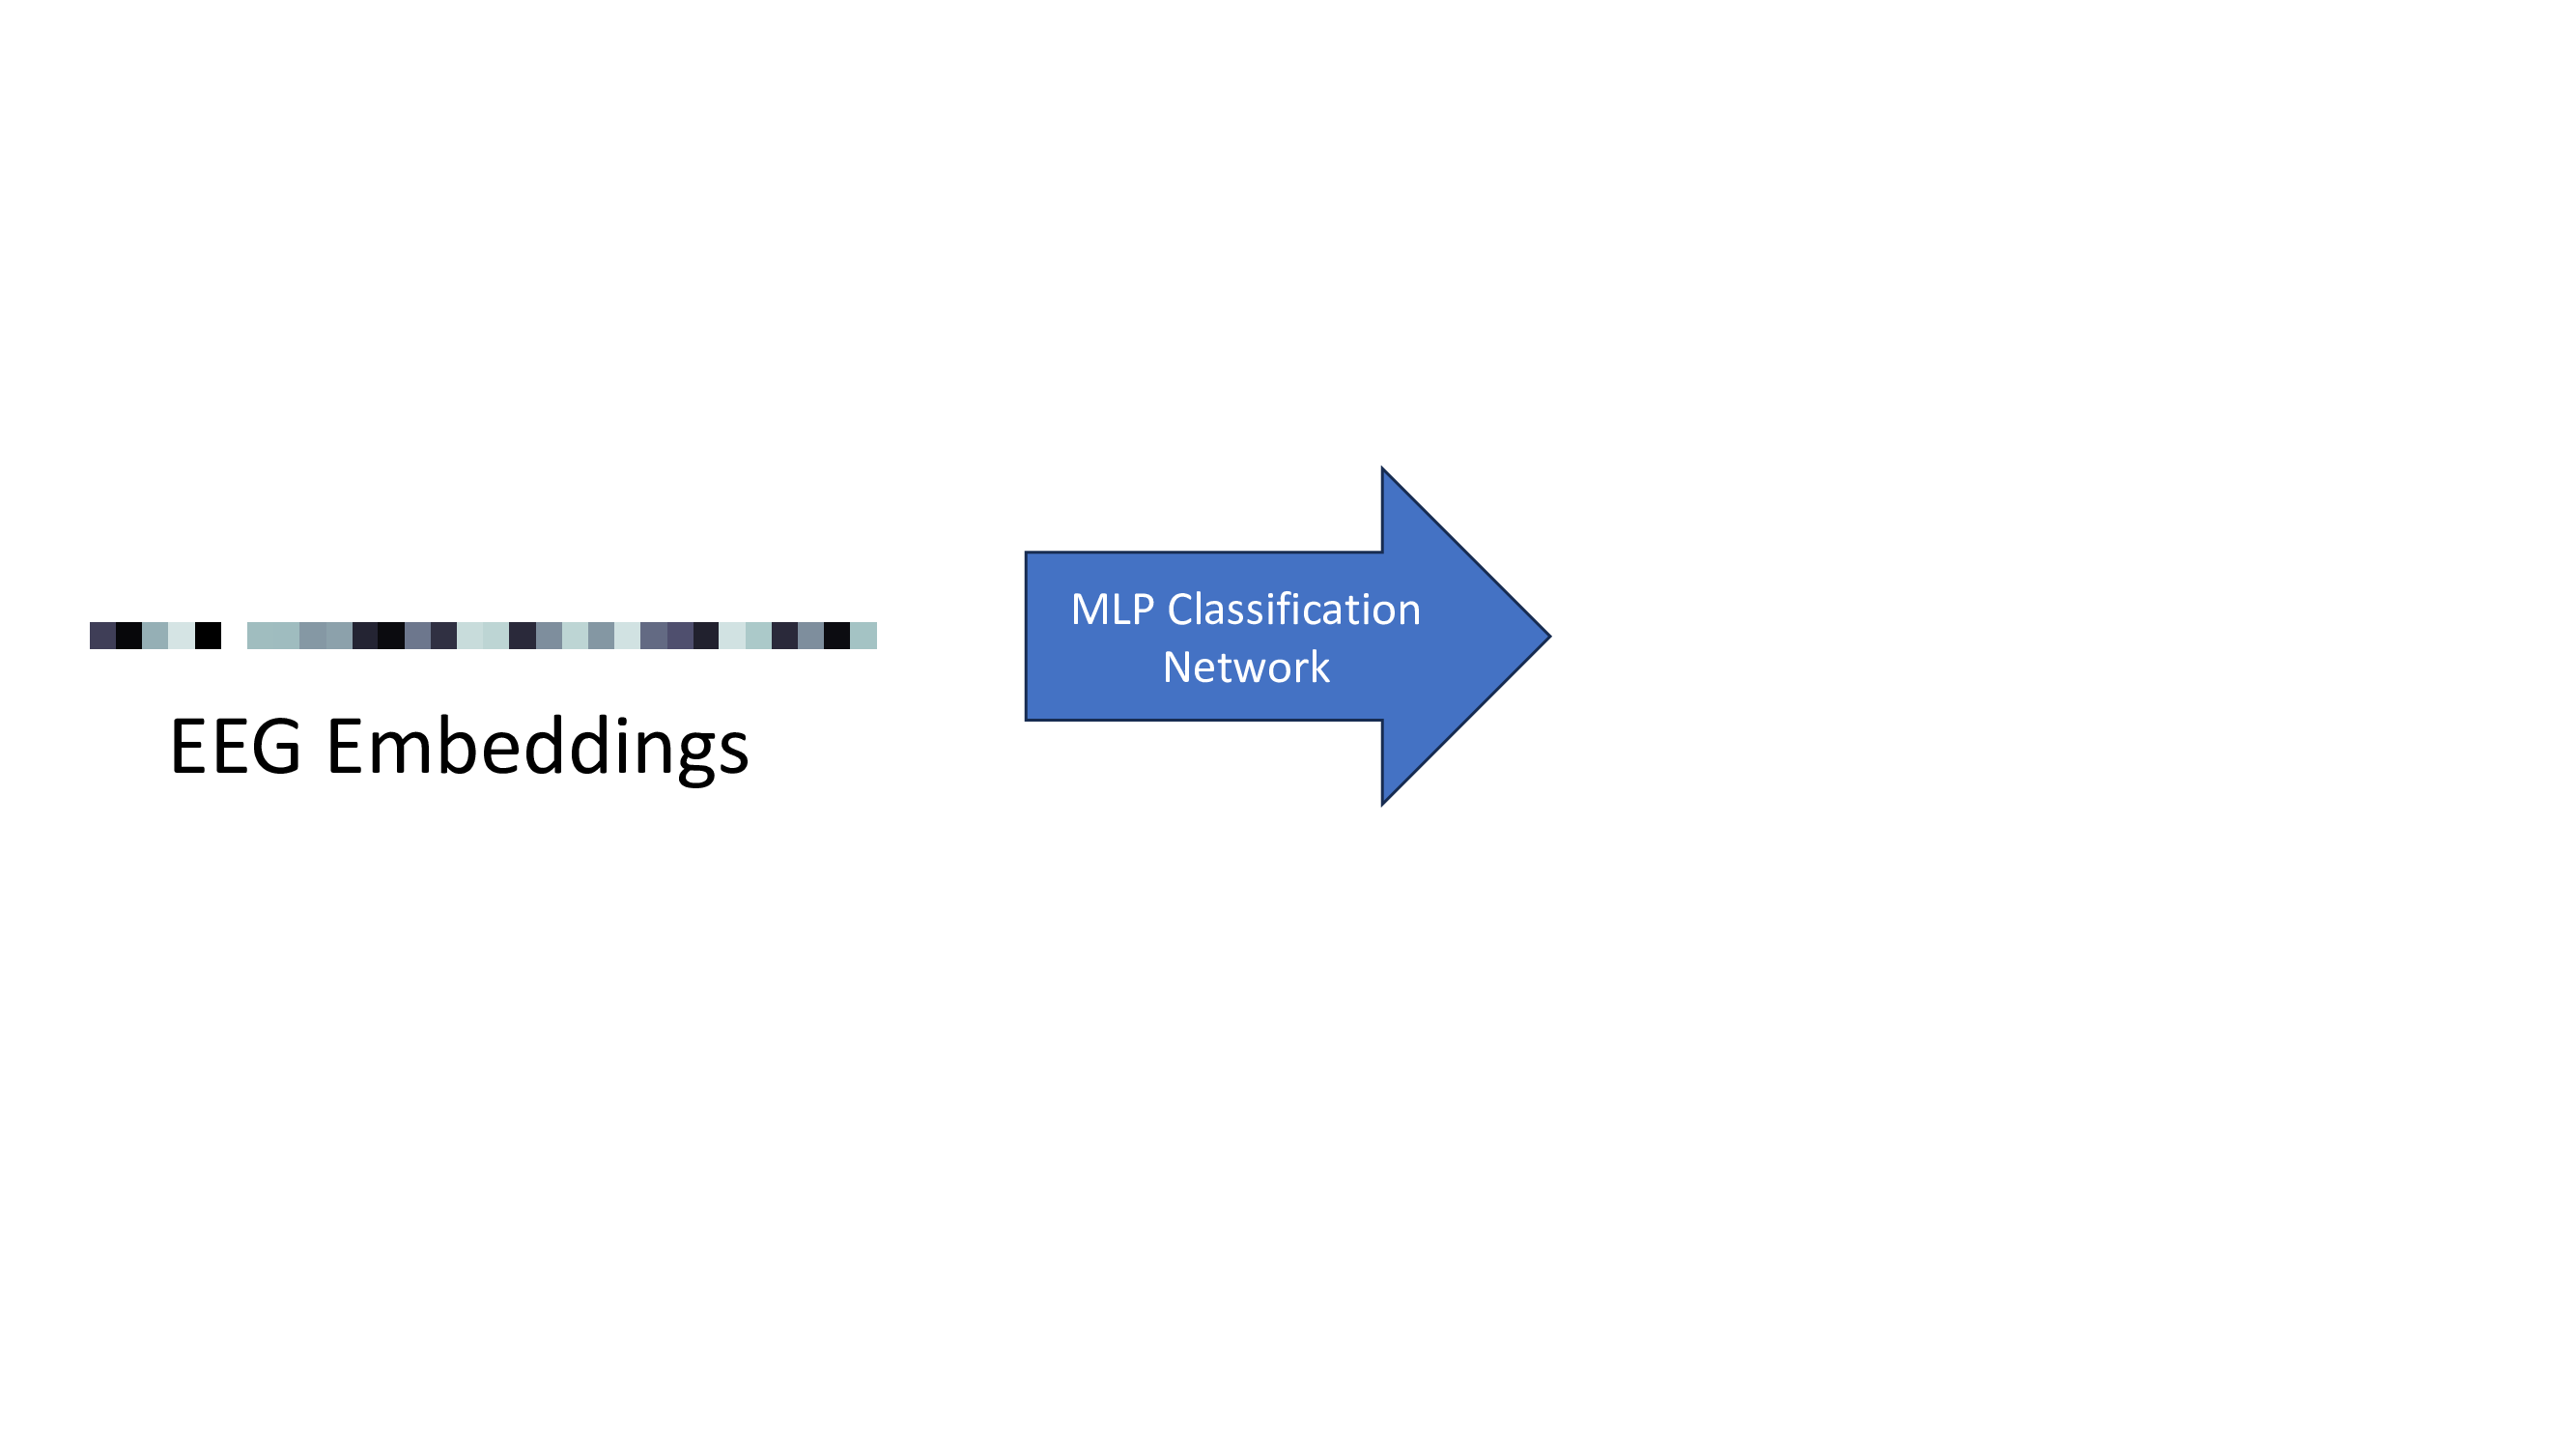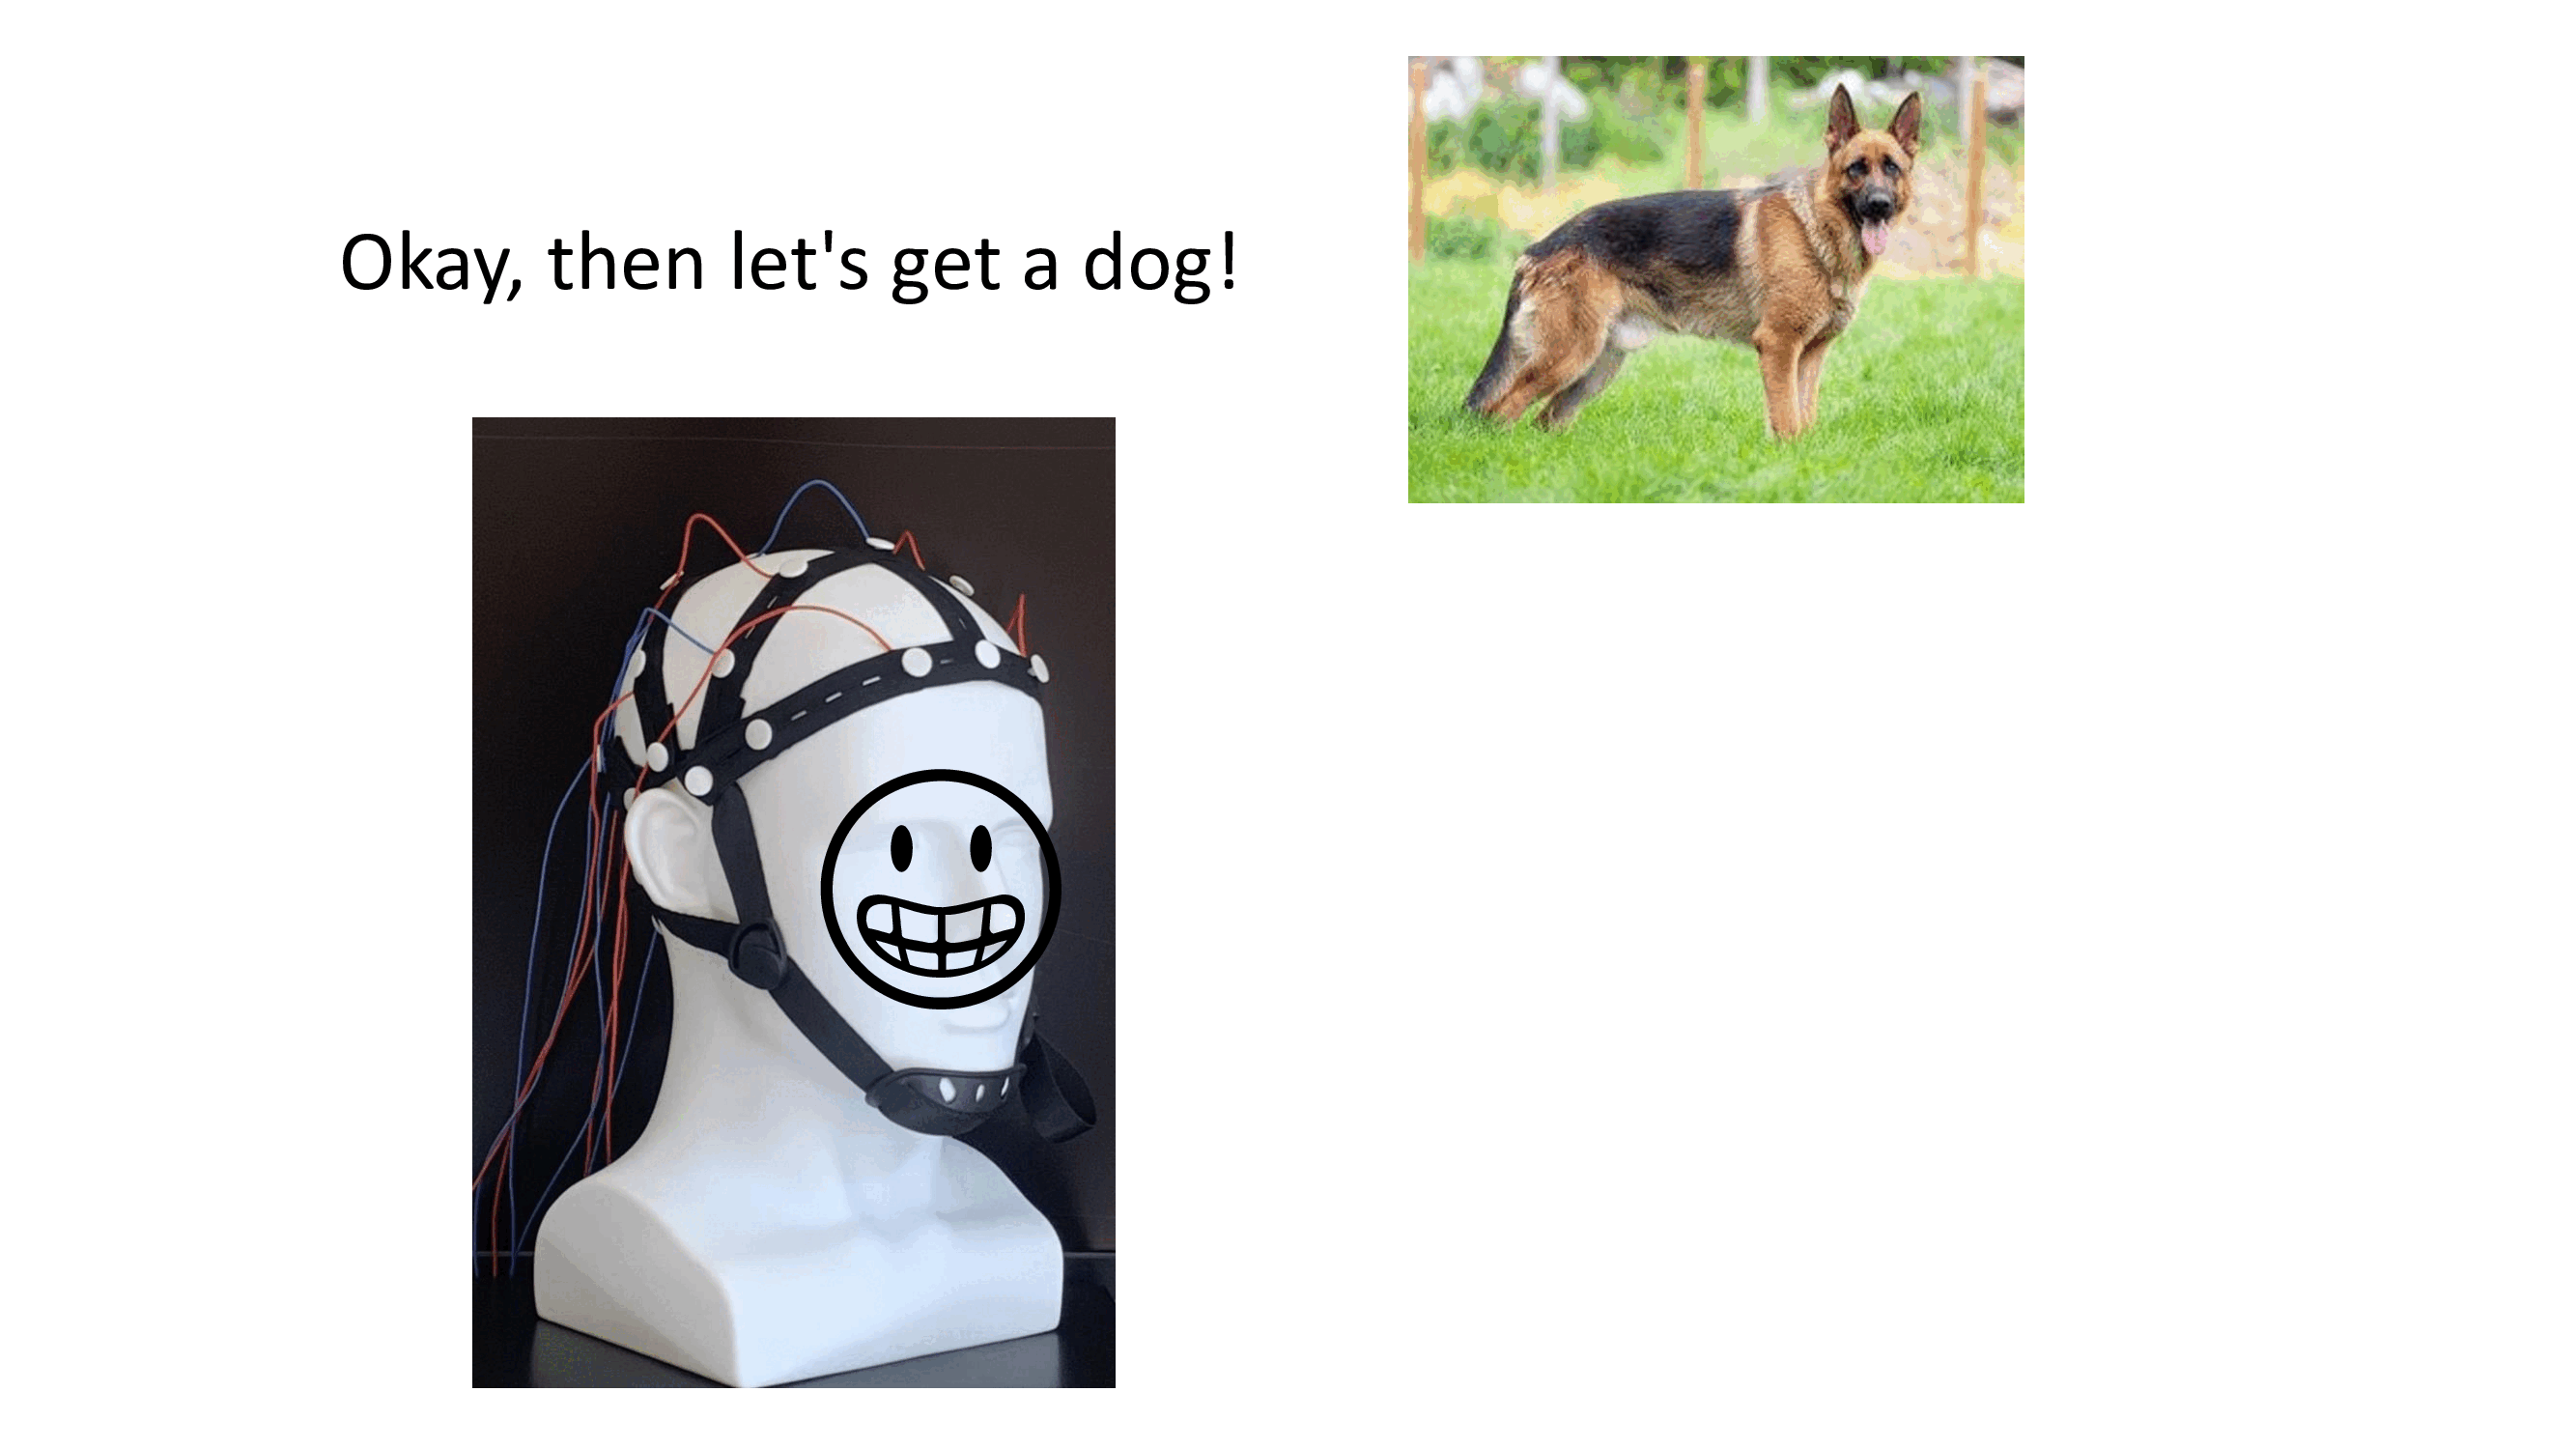
These GIFs below are intended to illustrate how we hope our model to be used in the real world. It also showcases the real world applications of every one of our tasks.
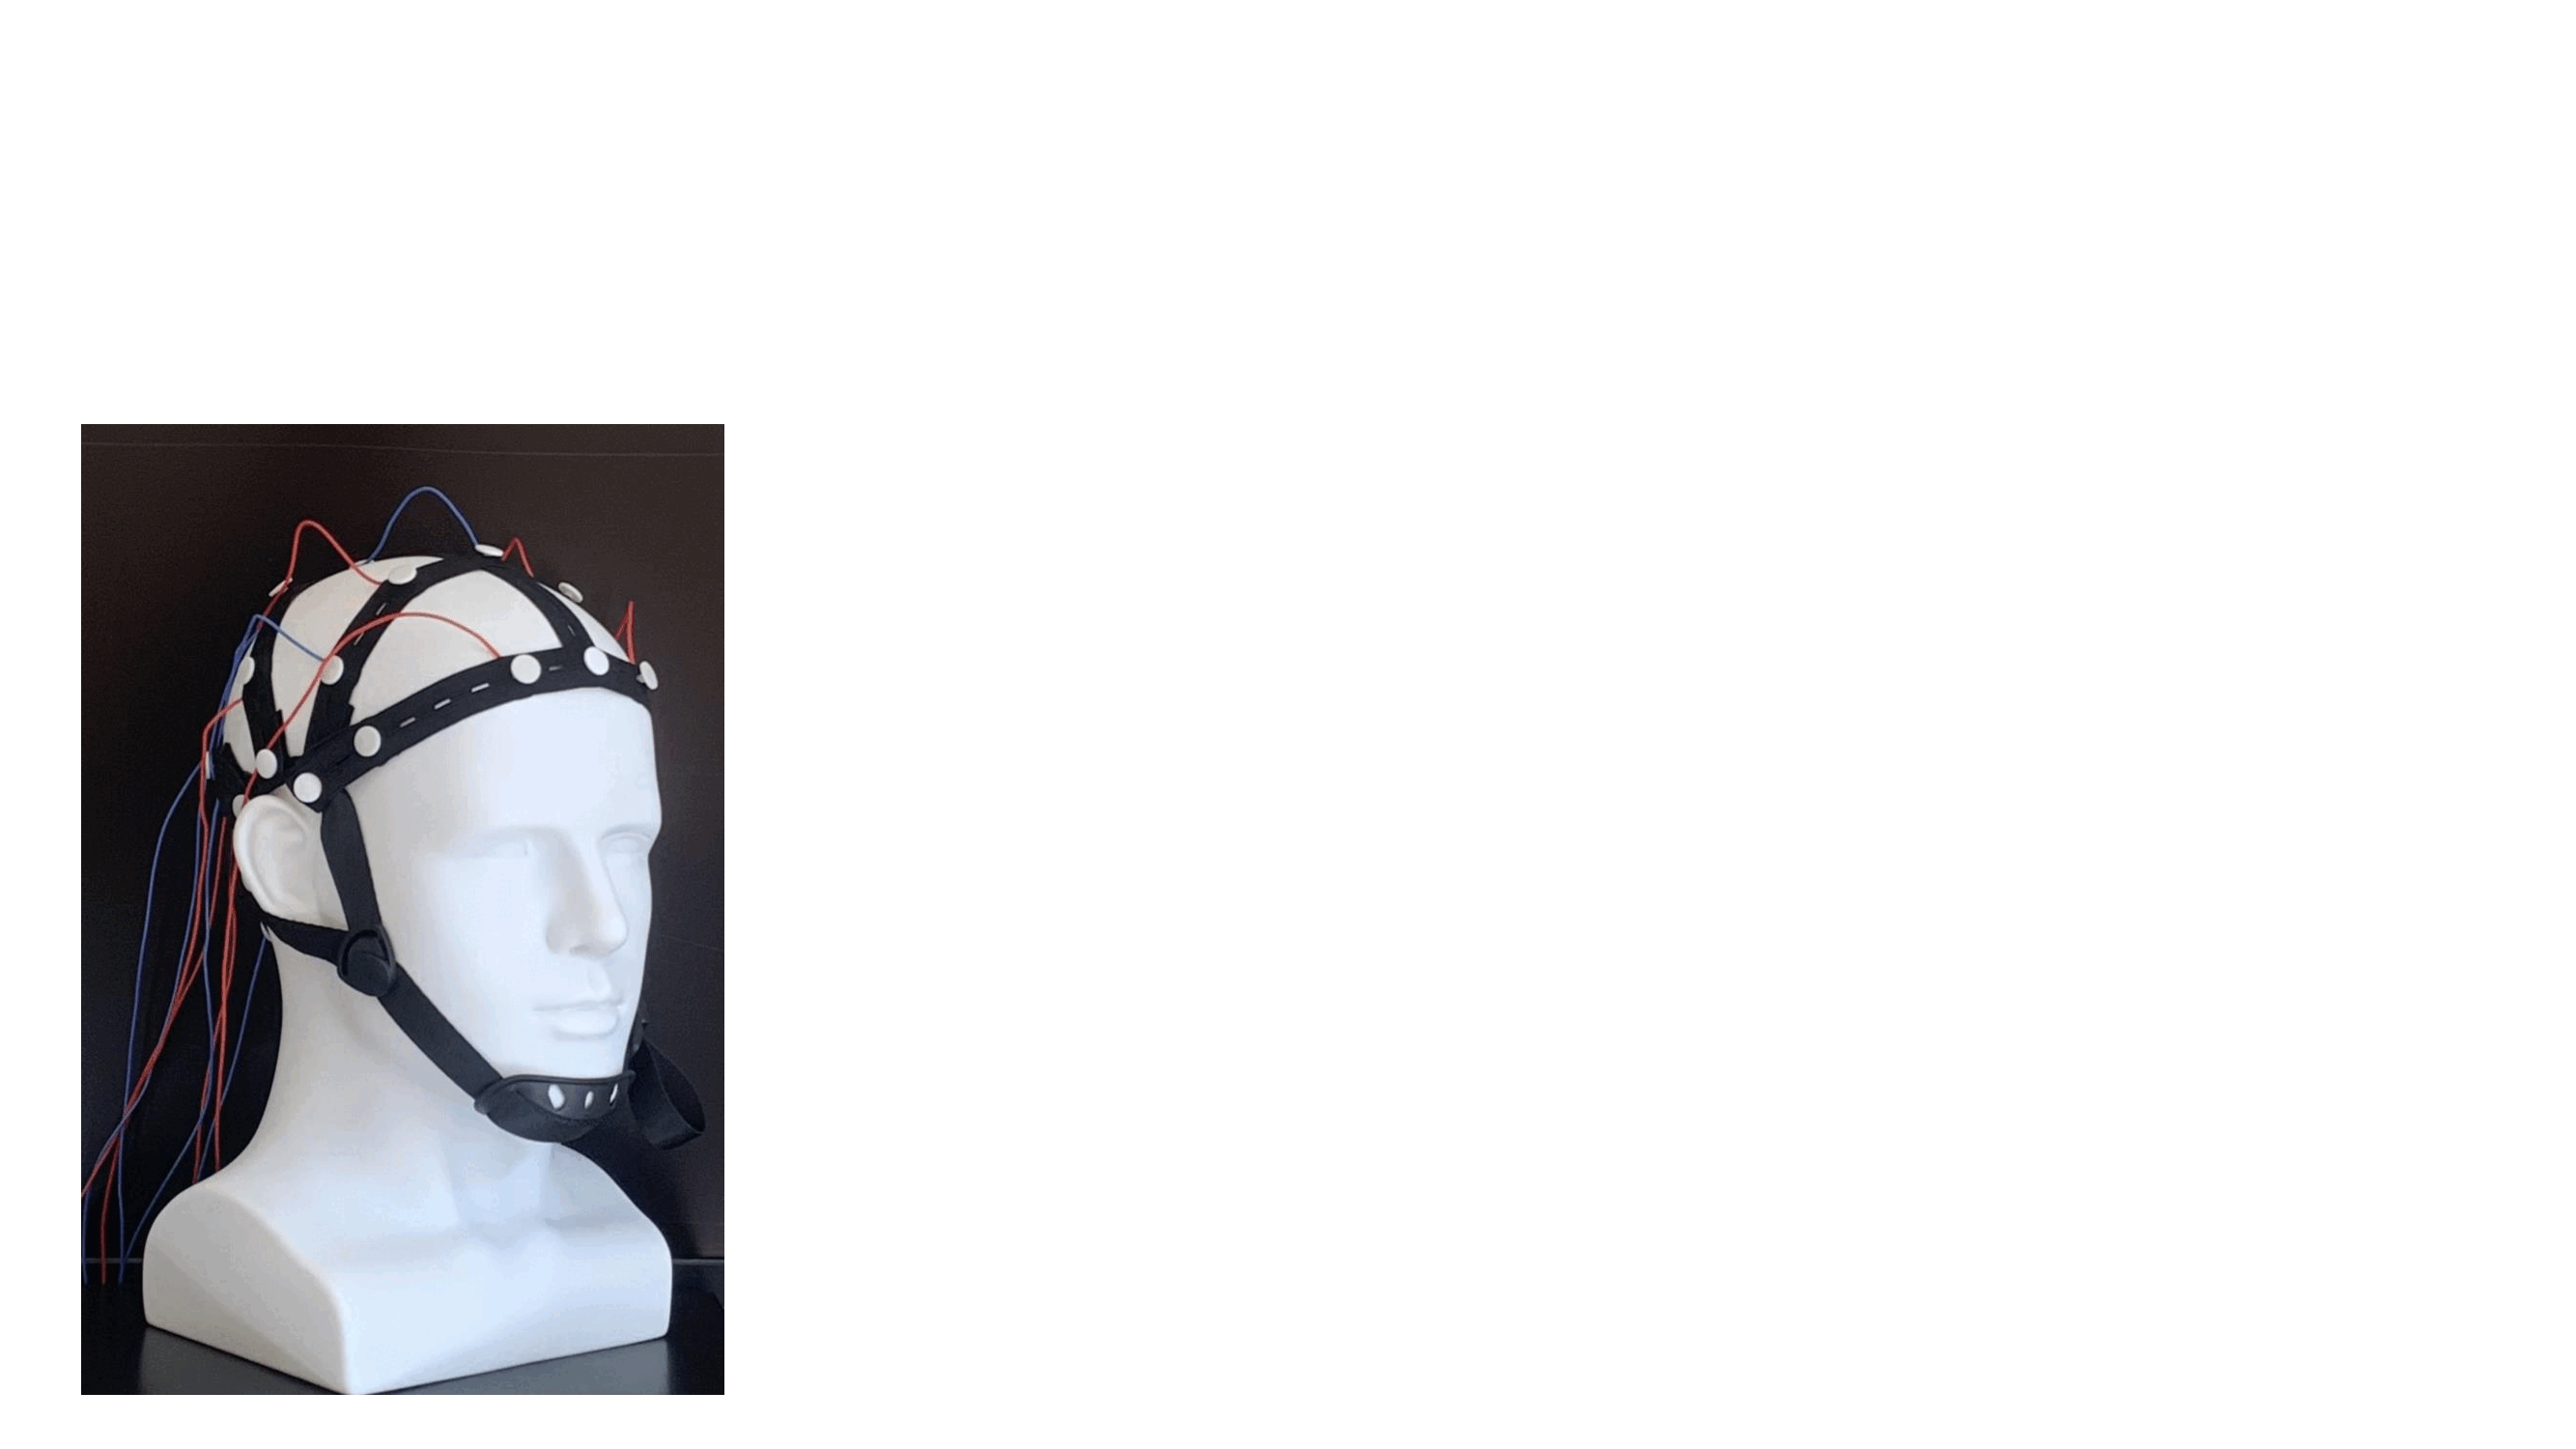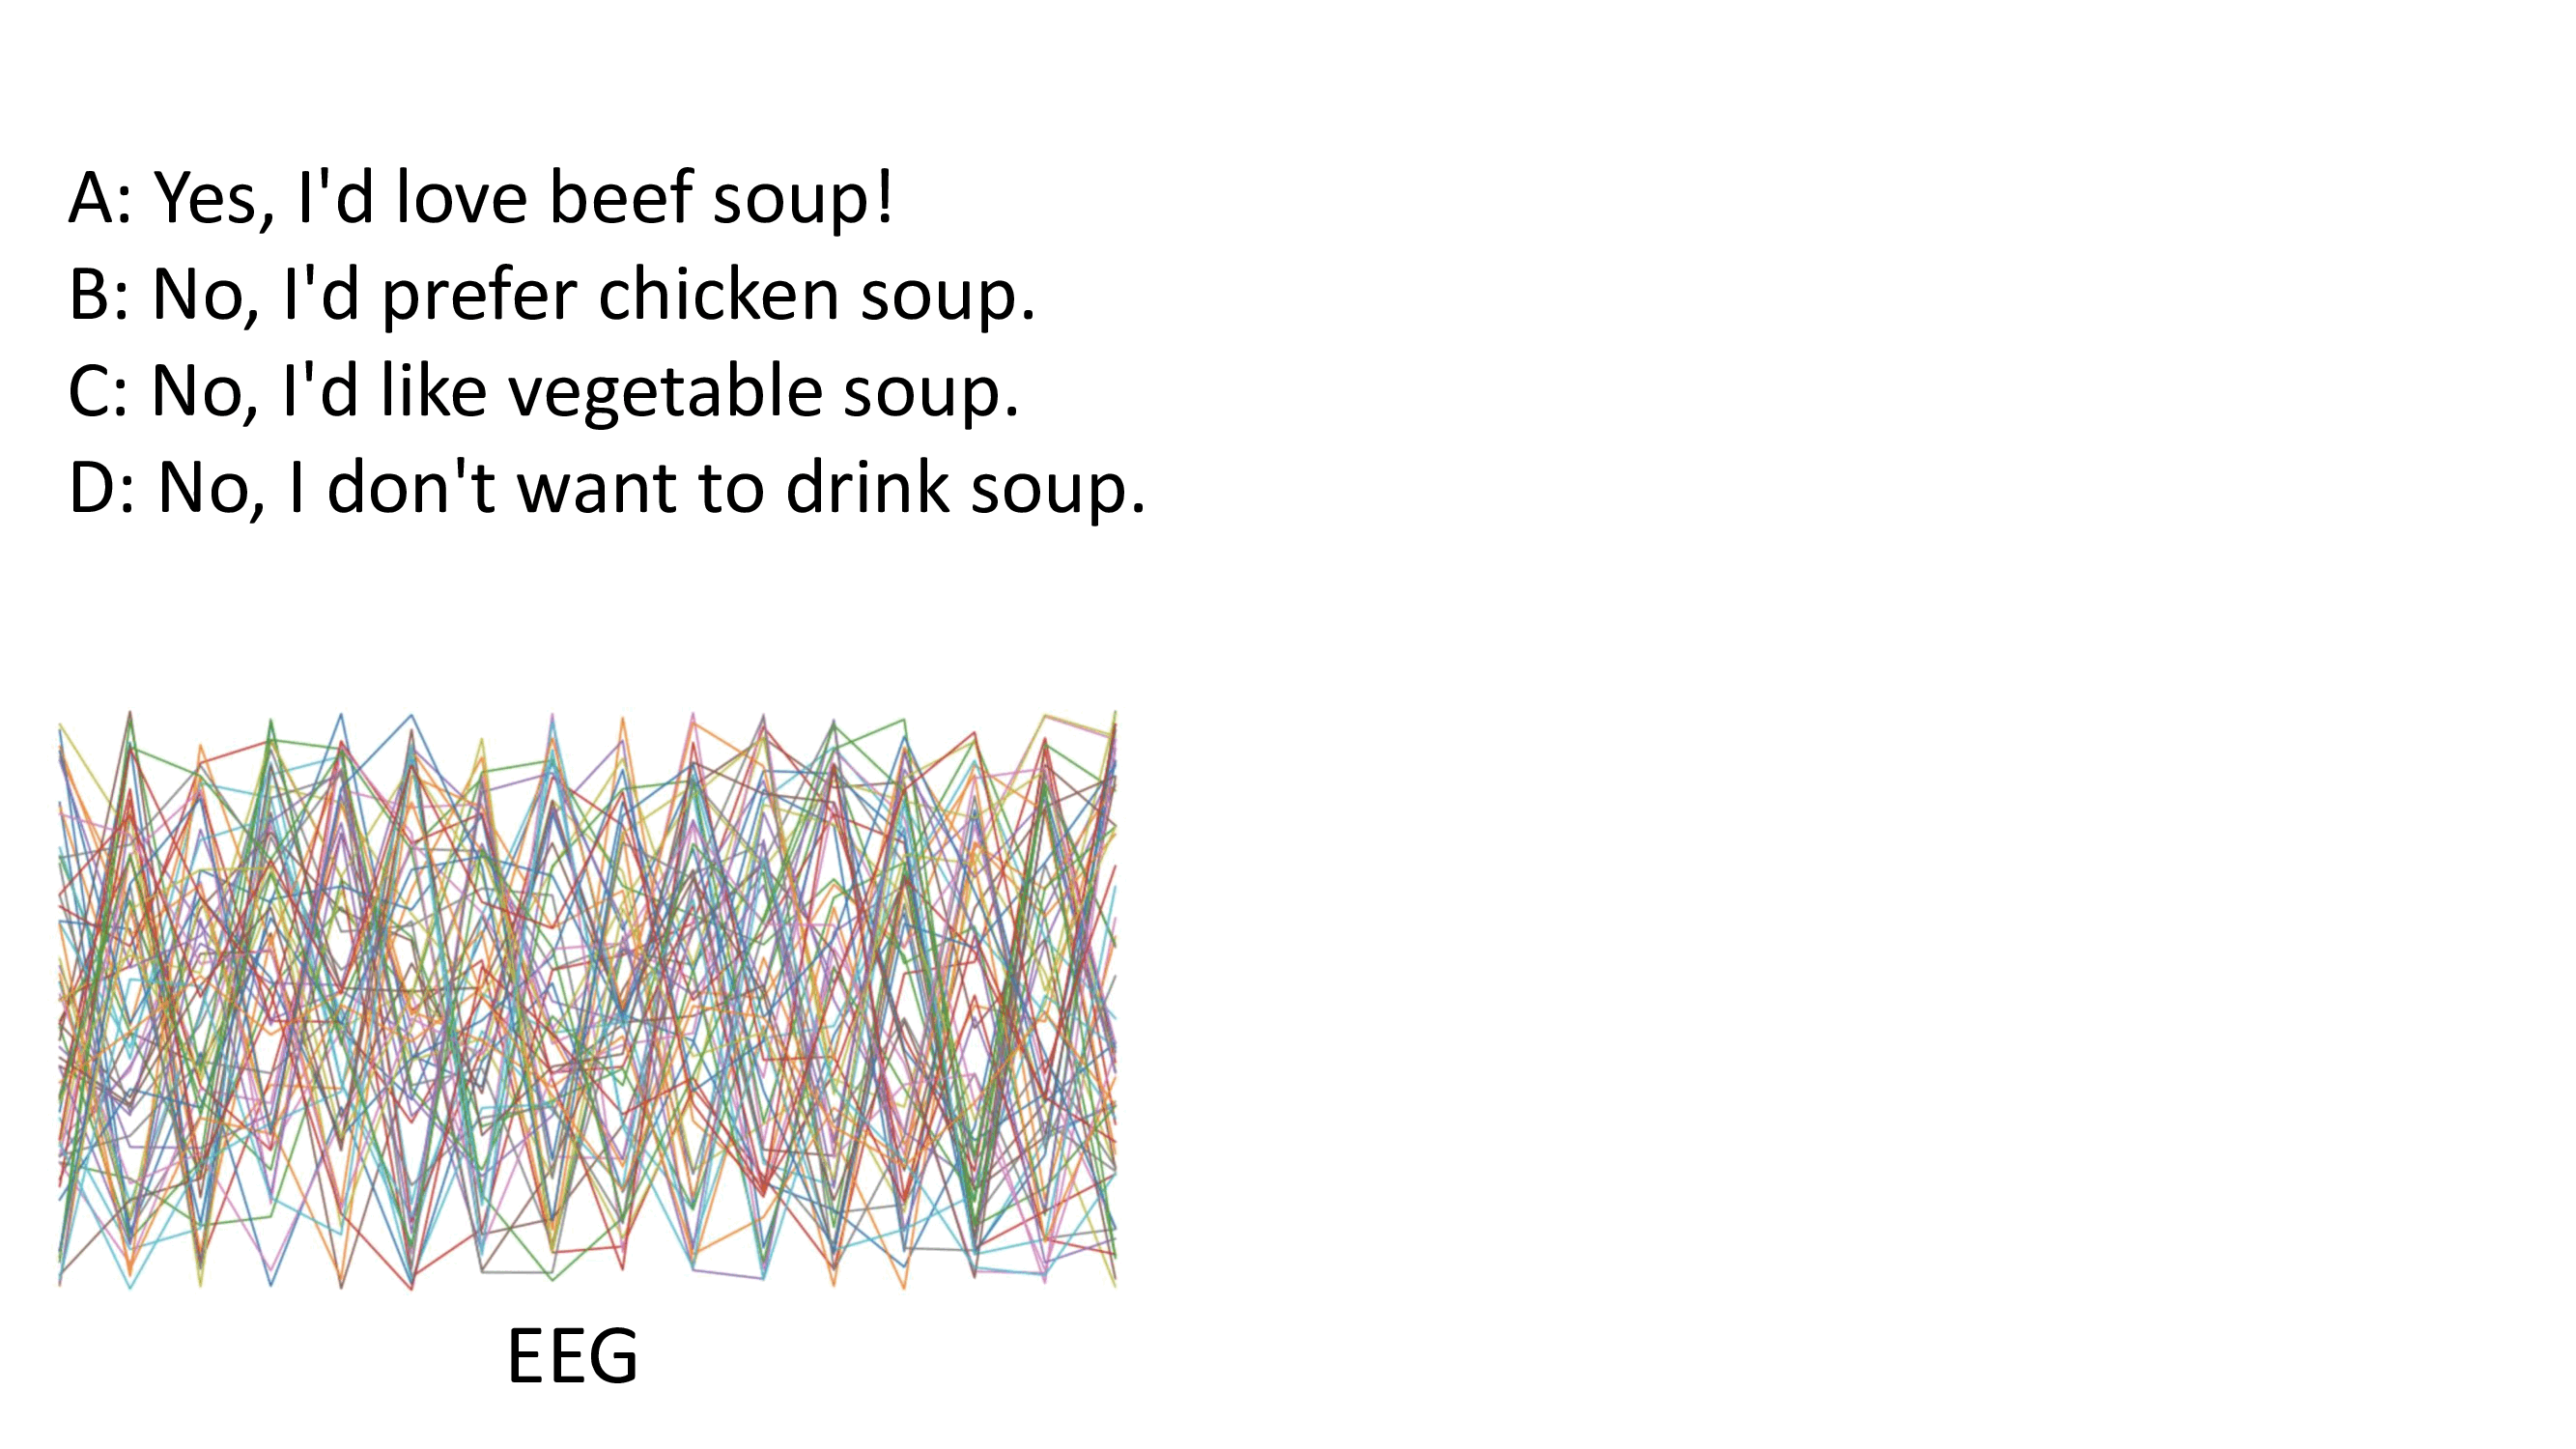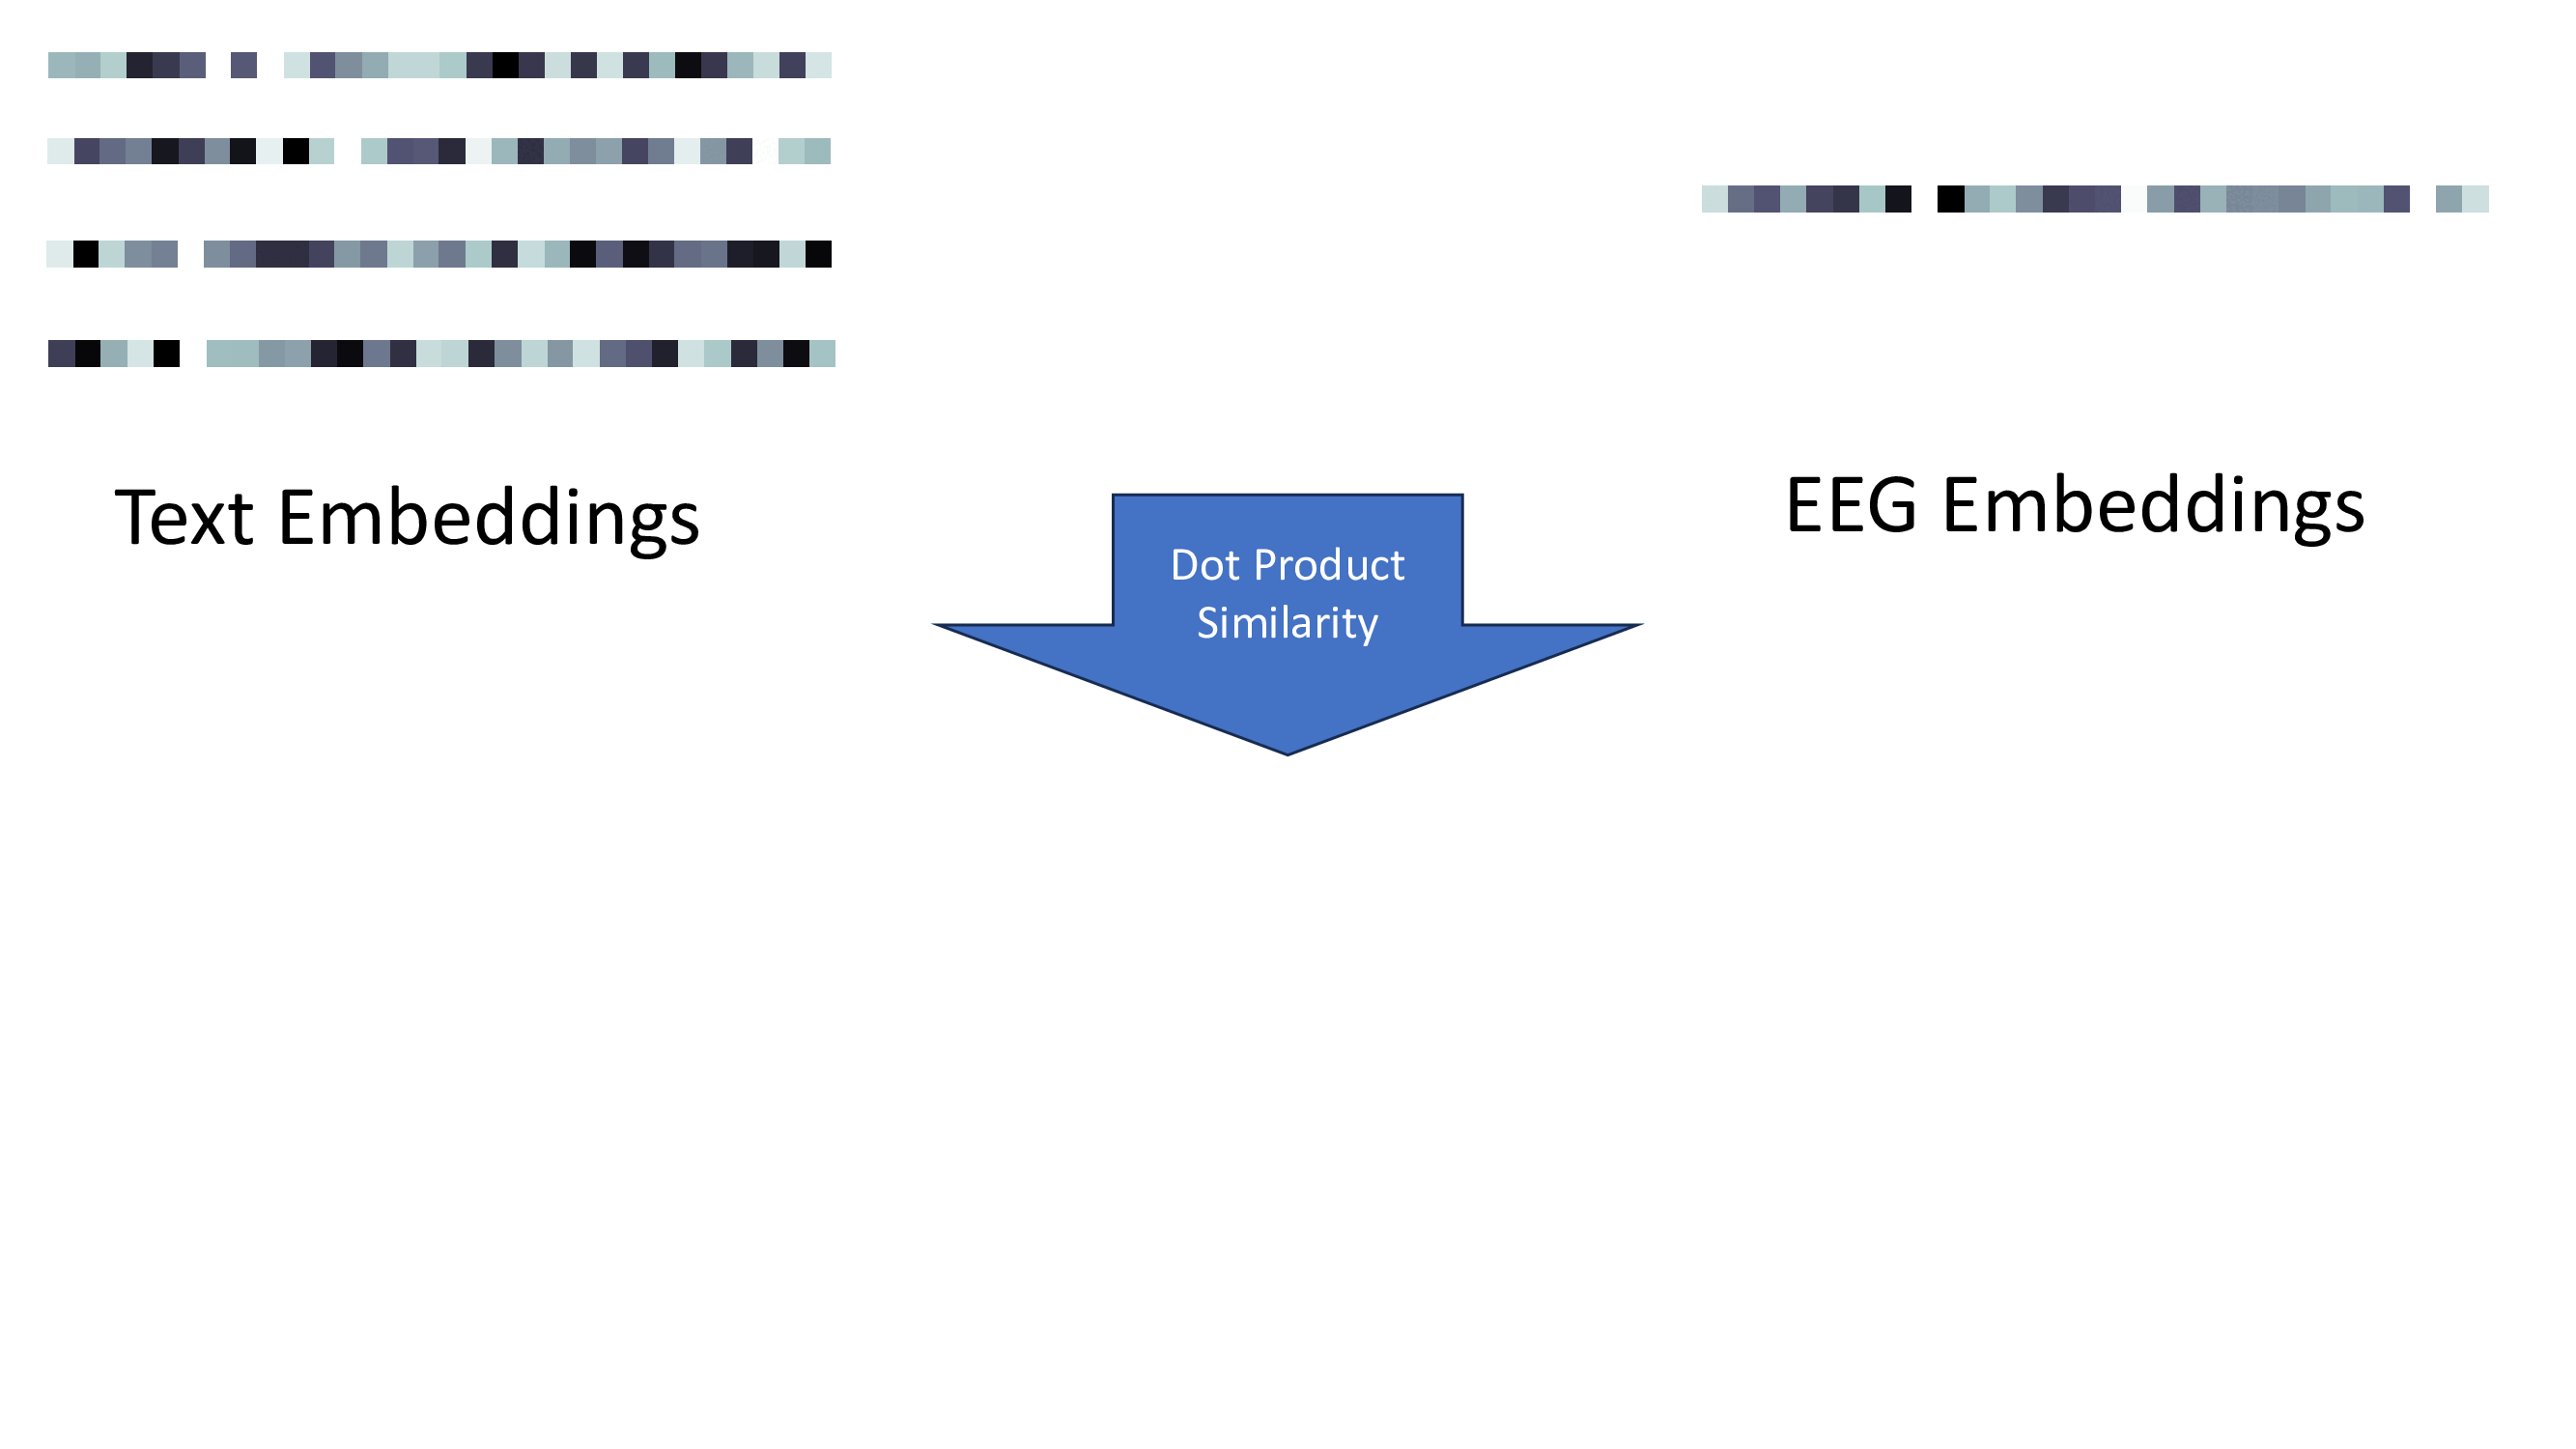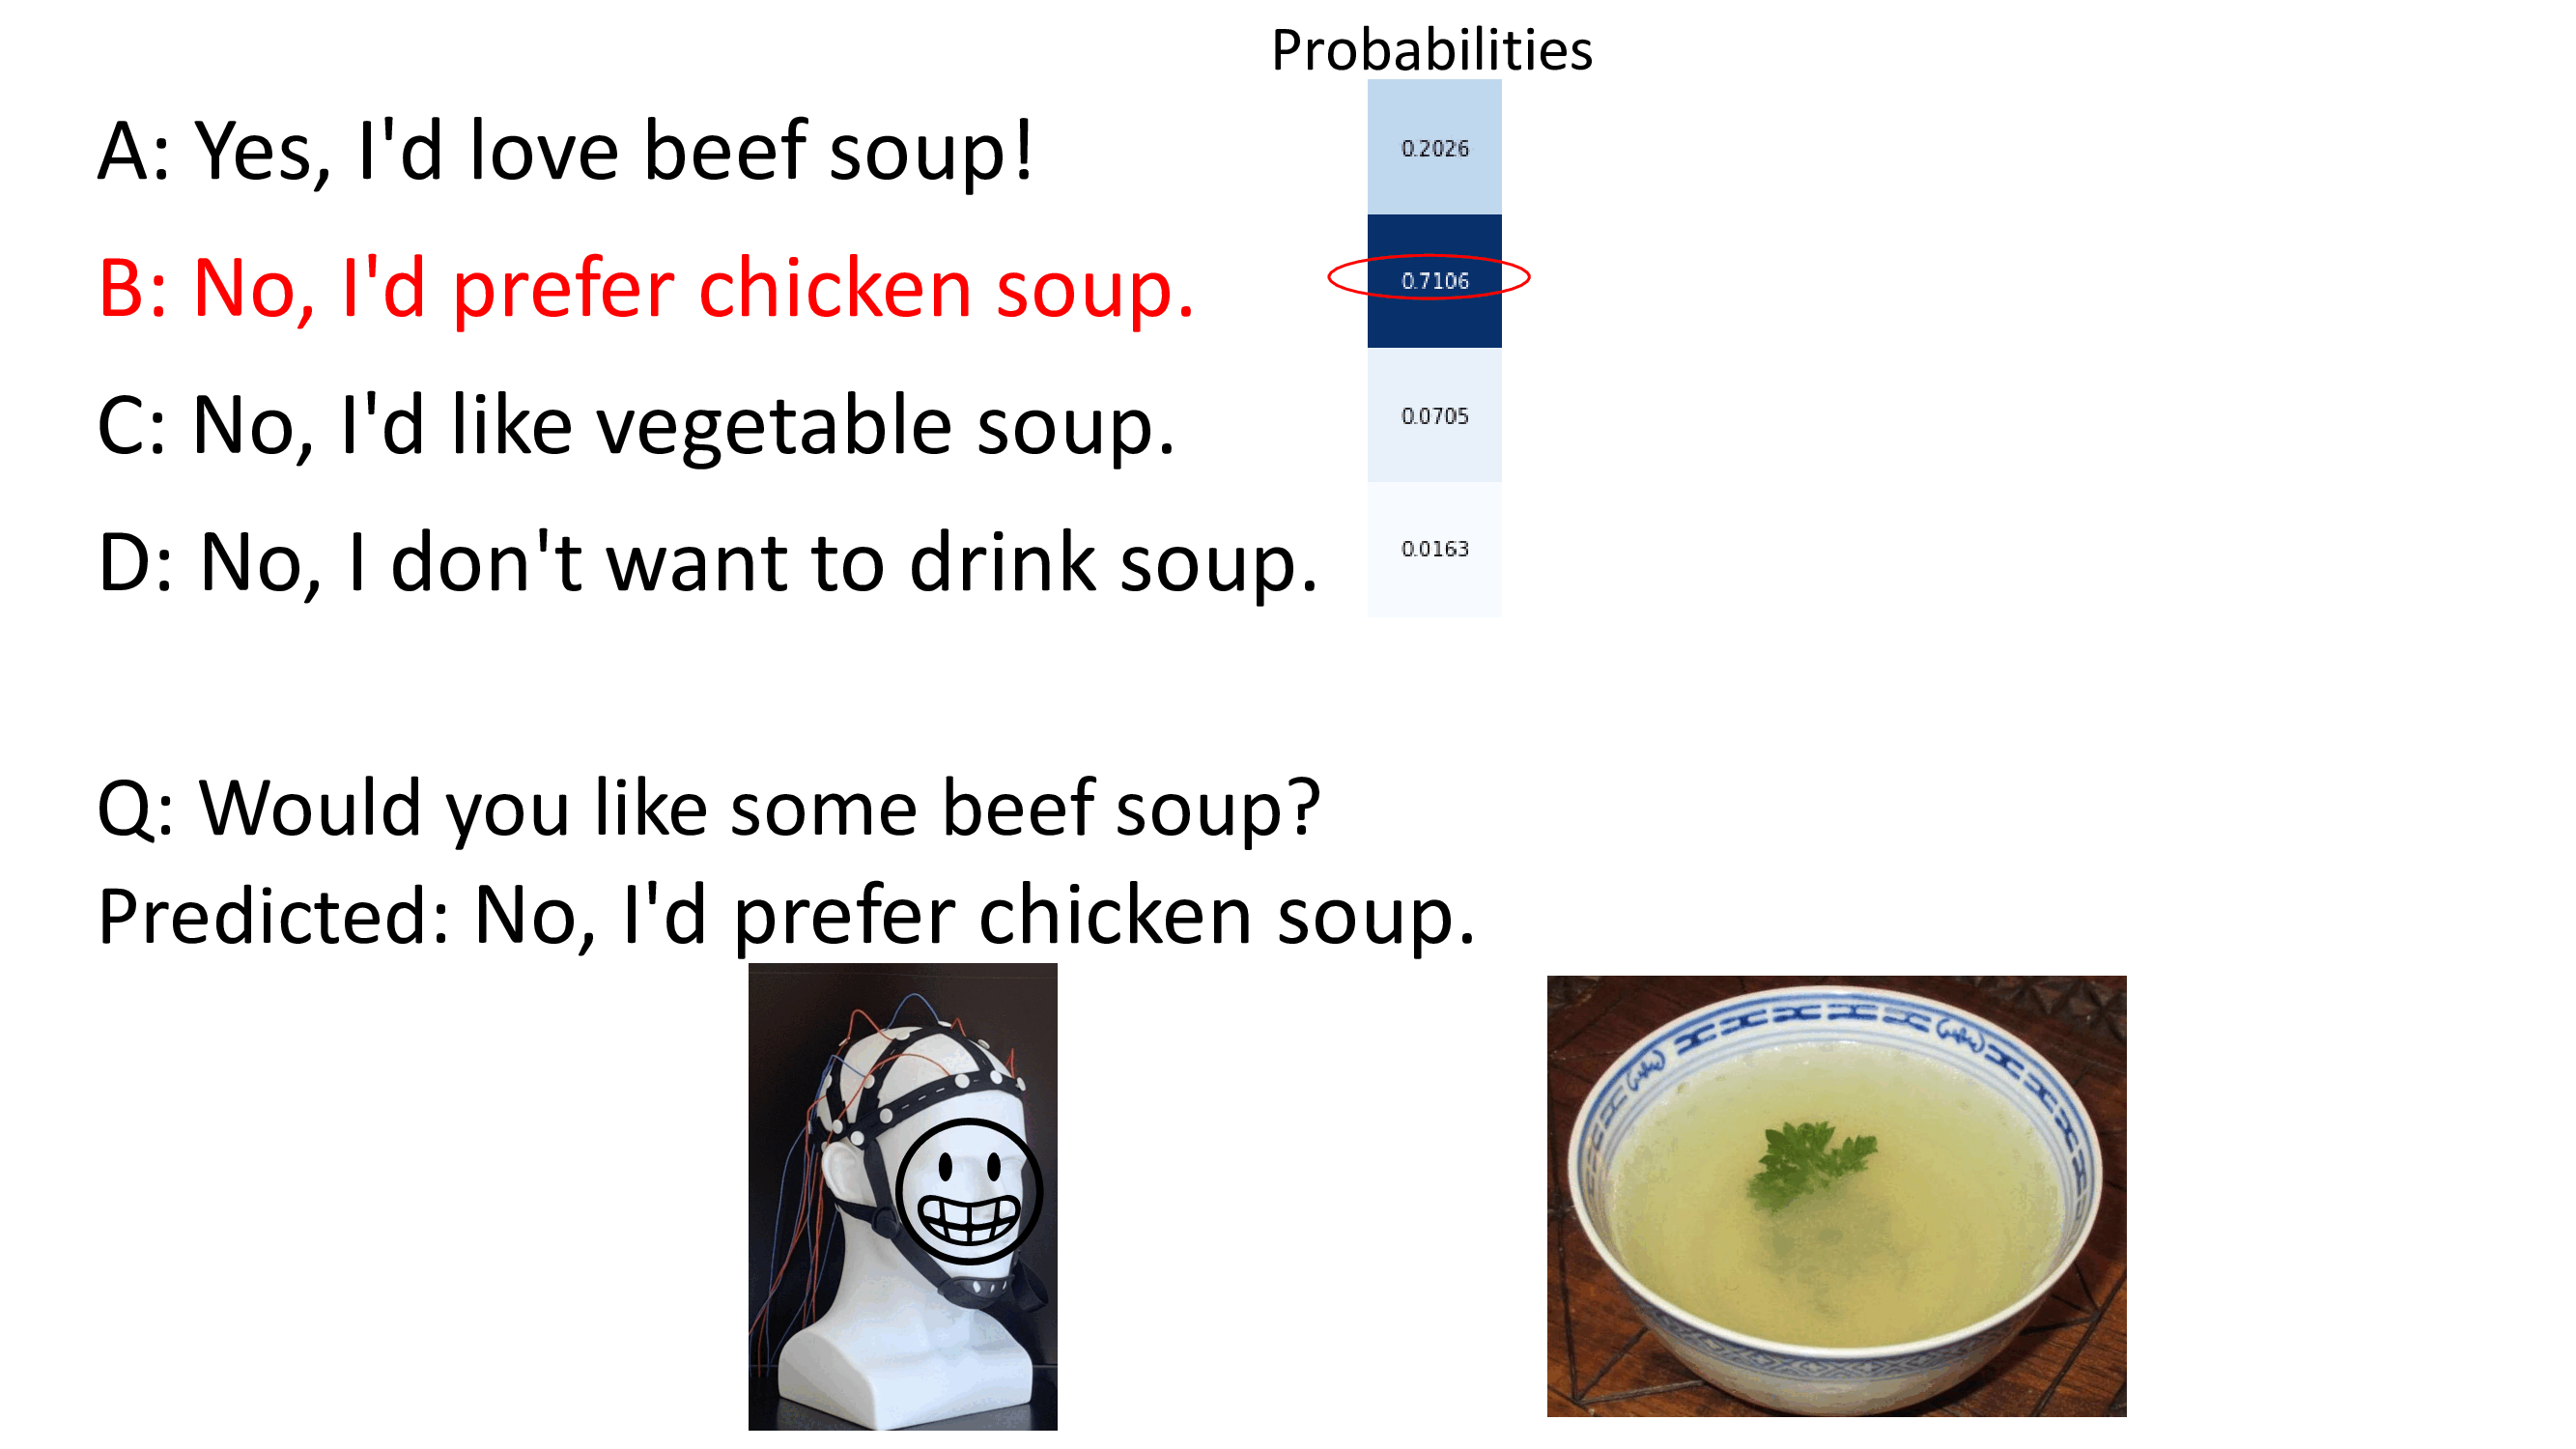
| Type | Count |
|---|---|
| Trainable | 104,394,283 |
| Pre-trained | 1,433,857,861 |
| Total | 1,538,252,144 |
| Task | Active Parameters |
|---|---|
| EEG-Text Matching | 107,747,072 |
| EEG-Image Matching | 107,747,072 |
| EEG-Text Generation | 521,778,688 |
| EEG-Image Generation | 973,566,148 |
| EEG-Image Classification | 112,470,528 |
| EEG-Sentiment Classification | 117,459,971 |
| Epochs | Phase | |
|---|---|---|
| Warmup (Pre-training Tasks) | N/A | |
| Pre-training | N/A | |
| Training | 50 |
| Epochs | Phase | |
|---|---|---|
| Warmup (Pre-training Tasks) | 15 | |
| Pre-training | 35 | |
| Training | 50 | |
|
LR Decay ( |
||
| ETM | N/A | |
| EIM | N/A | |
| TEXT-GEN | 0.5 | |
| IMG-GEN | 0.5 | |
| SENT-CLASS | 0.5 | |
| IMG-CLASS | 0.5 |
| Epochs | Phase | |
|---|---|---|
| Warmup (Pre-training Tasks) | 10 | |
| Pre-training | 60 | |
| Training | 50 | |
| Pretrain LR Scaler | ||
| 1-10 | Linear 0.2 |
|
| 11-15 | 1.0 | |
| 16-25 | 0.2 | |
| 26-35 | 0.04 | |
| 36-40 | 0.8 | |
| 41-50 | 0.16 | |
| 51-60 | 0.03 | |
| 61-70 | 0.6 |
| Task Abbreviation | Learning Rate | Optimizer | Batch Size | Temperature |
|---|---|---|---|---|
| ETM | 1e-5 | Adam | 256 | 20 |
| ETM | 1e-5 | Adam | 256 | 20 |
| TEXT-GEN | 5e-4 | Adam | 256 | N/A |
| IMG-GEN | 5e-4 | Adam | 32 | N/A |
| SENT-CLASSIFICATION | 5e-4 | Adam | 256 | 0.04 |
| IMG-CLASSIFICATION | 5e-4 | Adam | 256 | 0.04 |
| Task Abbreviation | Learning Rate | Optimizer | Batch Size | Temperature |
|---|---|---|---|---|
| ETM | 5e-5 | Adam | 256 | 20 |
| EIM | 5e-5 | Adam | 256 | 20 |
| TEXT-GEN | 5e-5 | Adam | 256 | N/A |
| IMG-GEN | 5e-5 | Adam | 32 | N/A |
| SENT-CLASSIFICATION | 5e-5 | Adam | 256 | 0.04 |
| IMG-CLASSIFICATION | 5e-5 | Adam | 256 | 0.04 |
| Task Abbreviation | Learning Rate | Optimizer | Weight Decay | Step Interval | Step Ratio | Batch Size | Temperature | ||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| ETM | 5e-5 | Adam | Default | Default | Default | Default | N/A | N/A | 256 | 20 | |
| EIM | 3e-5 | Adam | Default | Default | Default | Default | N/A | N/A | 256 | 20 | |
| TEXT_GEN | 1.7e-5 | AdamW | 0.83 | 0.94 | 2.87e-6 | 1.76e-6 | 0.92 | 10 | 0.4 | 256 | N/A |
| IMG-GEN | 3e-5 | AdamW | 0.8 | 0.9 | 5e-7 | 0.01 | 0.9 | 5 | 0.3 | 32 | N/A |
| SENT-CLASSIFICATION | 1e-5 | AdamW | 0.85 | 0.97 | 6.7e-7 | 6.3e-7 | 0.912 | N/A | N/A | 256 | 0.04 |
| IMG-CLASSIFICATION | 5e-4 | AdamW | 0.9 | 0.999 | 6.7e-7 | 6.3e-7 | 0.95 | N/A | N/A | 256 | 0.04 |
Some code from this repository has been borrowed from EEG-To-Text and thomwolf's implementation of parallel optimizers and loss functions. A sincere thank you to their wonderful work.
This research has been conducted while I was working a research internship at Carnegie Mellon University. The views and conclusions contained herein are mine and should not be interpreted necessarily as those representing that of Carnegie Mellon University, either expressed or implied.
As a final note, I would like to express their thanks to Microsoft Research for their hardware, and Carnegie Mellon University for their generous funding, which has been critical to ensuring the success of this project.