
This repository is complemntary of "FlashFloat" with JIT Kernels
The introduction of the NSA (Native Sparse Attention) mechanism in DeepSeek V3.2 has become pivotal for mitigating inference latency in long-context language modeling. While the NSA top-k indexer playing a critical role in reducing computational overhead for DeepSeek V32 long context sequence modeling task[1], DeepSeek V4 [2] [3], recently, further pushes the context window limit to 1 million tokens where selecting top-2048 dimensions in hybrid sparse attention along from upto 1-M context is a prohibitive bottlenect upto 0.1 ms per layer per query token for agentic workflow.
Leveraging the latest SGLang (2026.3) as the benchmark, we investigated the root causes of this latency bottleneck: kernels for conventional throughput-optimized GPU designs suffer from low device utilization in low-batch, yet long context decoding scenarios due to insufficient inter-block coordination [4]. For example, on-chip network have been maturely adopted for many years in processor hareware such as IPU, Cerebras and Groq, but only being introduced into Hopper since 2022. By exploiting the limited on-chip communication capabilities of the Hopper architecture (upto 8 blocks per cluster) through hardware-aware alorithm-hardware co-design, we achieve a 50% latency reduction in low-batch yet long context decoding scenarios, demonstrating the effectiveness of synergistic optimization and NoC for long-context inference:
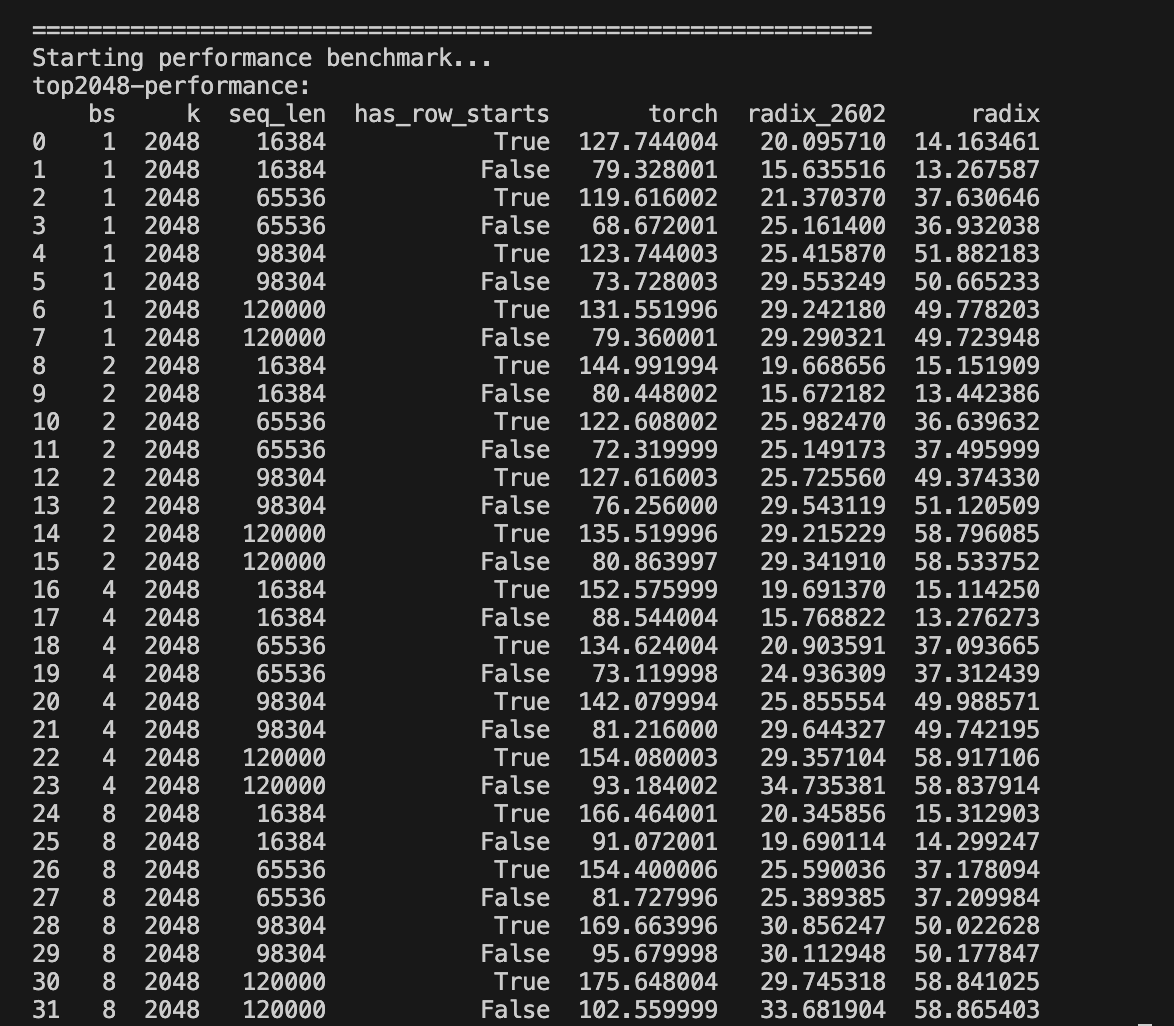
We hence propose Distributed Radix Sort via NoC to extremely reduce decoding latency in workload of low batch size, yet with upto 1-M context length.
-
First we compute historgram in parallel to reduce collision rates per block and then accumulate the histogram via NoC network before N-ways prefix sum and prove this is an effective method to reduce latency for a throughput oriented hardware design.
-
Second, we enhance the linear mapping properties for radix sort in NSA problem for reduction of radix sorting iterations; insteadd of traditional top 8/11/13 bits of IEEE FP32, FP16 format, we redesign the linear mapping such that
$bin(x) >= bin(y)$ , naturally deducing$x >= y$ .With this linear mapping design, we greatly reduced per block elements dropped in the threshold bin in redix sorting scheme and greatly reduce the residual numbers in later rounds.
This further facilitate cache friendly re-visiting over 1-M context length : we hence enable less SMEM in revisiting more elements.
- Finally, when remainder elements reduced to 8/16, we can simply use CAS operations to performa a neat parallel sorting in few cycles. This further reduce the latency overhead in the last round.
Previously, L2 cache was commonly used in NVGPU/AMD GPU to trackle the problem, for example in MoE Align Block Multi Block Execution Algorithm published 2025 [5], we tackle this problem by introducing mathematically equivalent unaligned parallel prefix sum. With distributed radix sort, we further prove that on-chip network can further reduce latency of our kernel, facilitating new design of algorithm and software for 1-M context.
[1] DeepSeek-AI V3.2 (2024). DeepSeek-V32 Technical Report; Accessed on April 26, 2026
[2] DeepSeek-AI V4 (2026). DeepSeek-V4 Technical Report; Accessed on April 26, 2026
[3] Dissecting DeepSeek V4 :https://www.zhihu.com/question/2030963929510310856/answer/2031157557008541232?share_code=1nP5rOshEmo63&utm_psn=2031815957111419327; Accessed on April 26, 2026
[4] SGLang 2026.4 (0.5.10.post2.dev419+g635e922eb), classical throughput optimized design of TopK : https://github.com/sgl-project/sglang/blob/c7878dbb6ddfc9c6721b9db20a876f2718b0e955/sgl-kernel/csrc/elementwise/topk.cu#L448; Accessed on April 26 2026
[5] MoE Align and Sort : https://huggingface.co/blog/yiakwy-xpu-team/efficient-moe-align-sort-design-for-sglang