Scan a tree for the Unicode that hides meaning — and never see it quoted back at you
Trojan Source bidi controls, invisibles, homoglyphs, mixed scripts, non-NFC text, spaces that are not the space


Useful? A star is how other developers find it — ★ GitHub · letools.dev/tools/unicode-le
A right-to-left override that makes a reviewer read an if guard that
is not there. A Cyrillic а in pаypal. A zero-width space between two
strings that a hash says are different and a person says are the same. A
no-break space where a split(' ') expects a space.
One command over a whole tree. Nothing is rewritten, and nothing it
prints can render as anything — findings carry U+XXXX, never the
character, and even a file name or a key that holds a bidi control comes
out as \uXXXX. A report that pasted one raw would reorder the terminal
of whoever read it. Because \uXXXX is JSON's own escape, a parser
still decodes the path back to the file it opens.
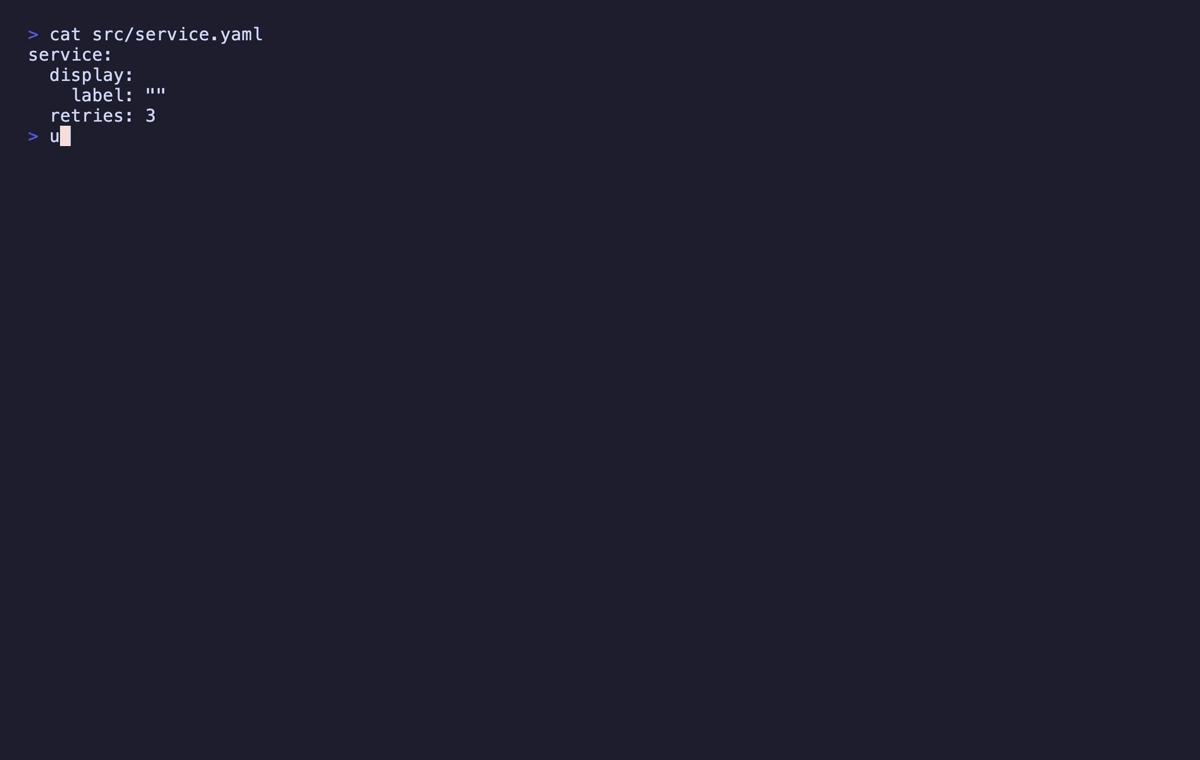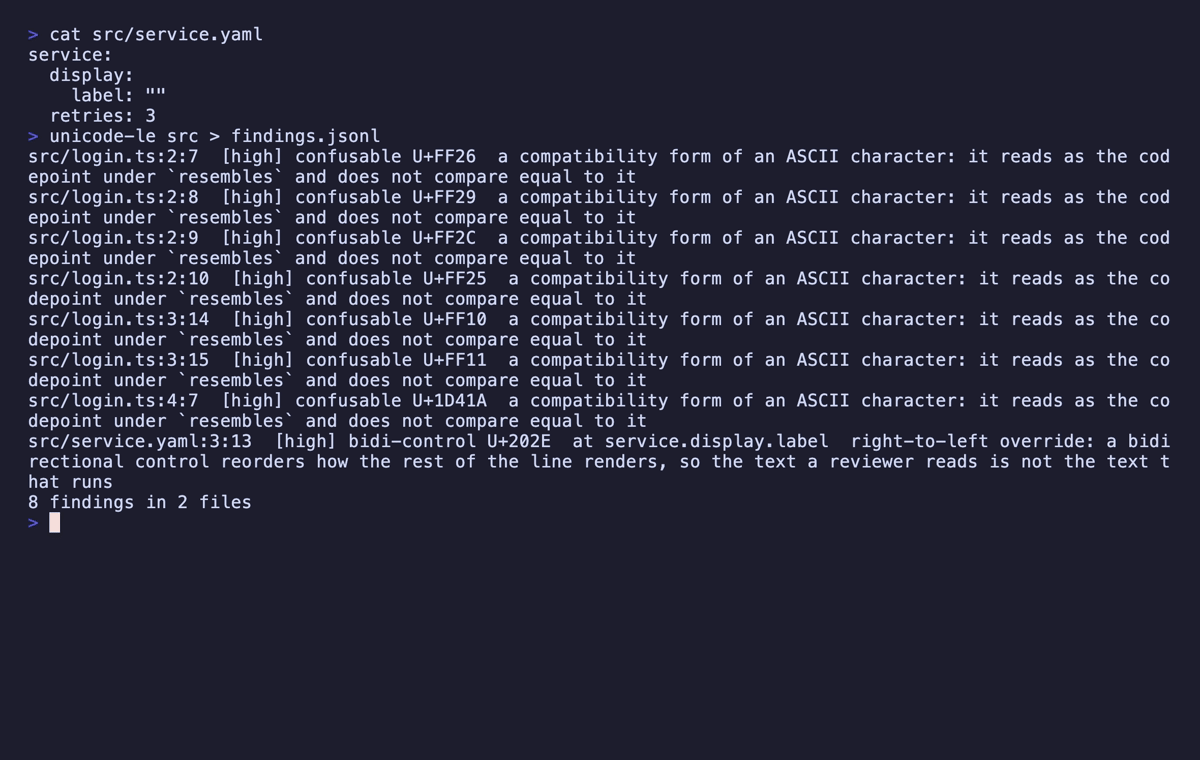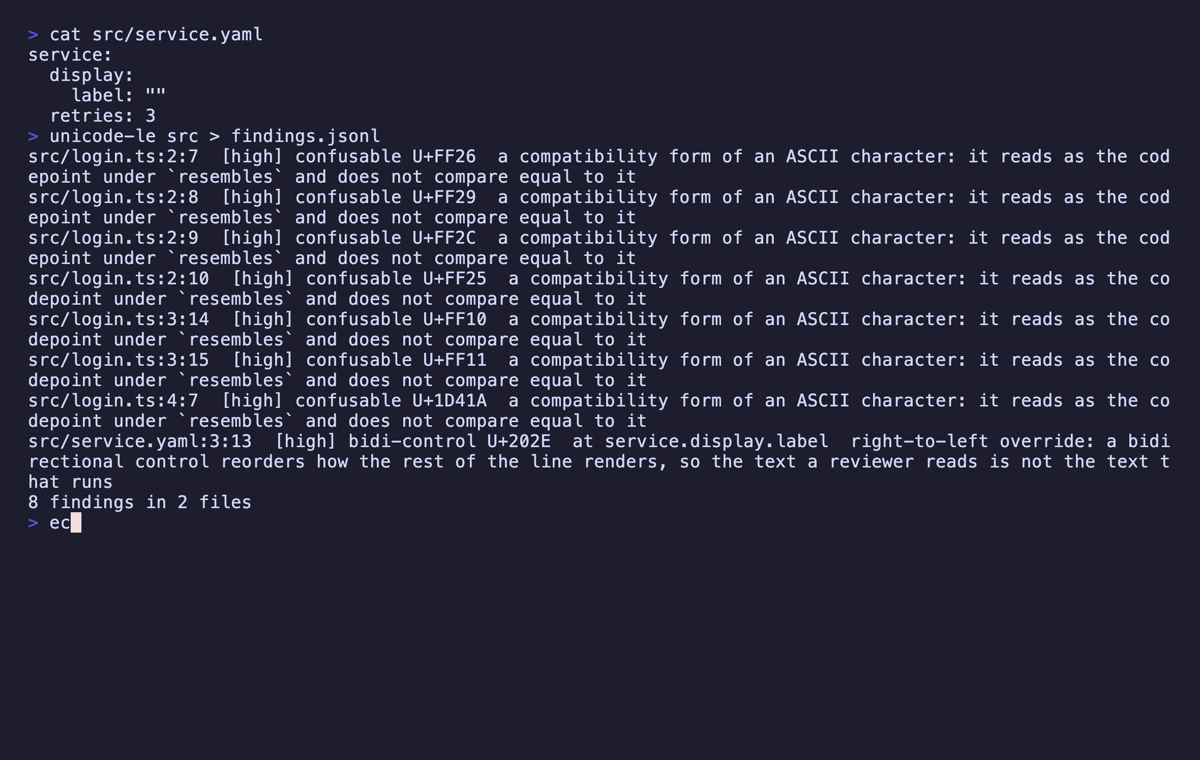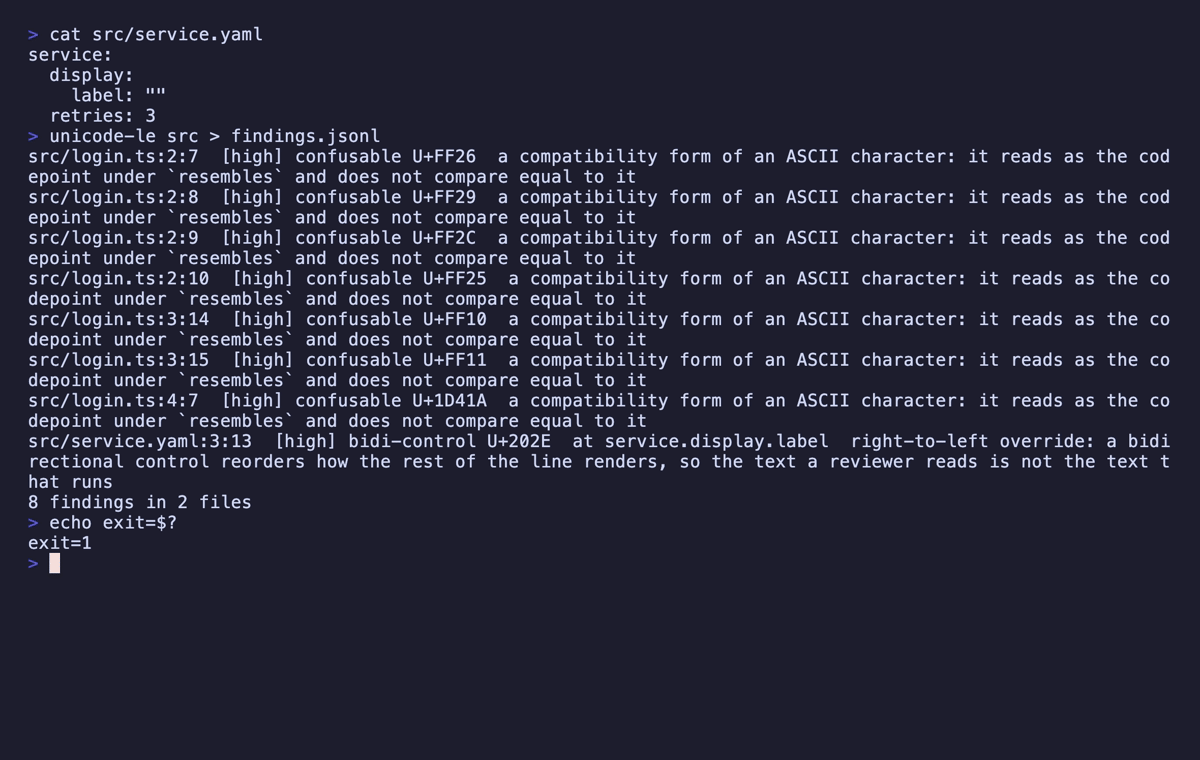
$ unicode-le src/
src/auth.ts:1:7  [high] mixed-script U+0430  one word written in Cyrillic and
  Latin: no single script accounts for it, which is how a name that reads as
  familiar is forged
src/auth.ts:1:8  [high] confusable U+0430  a Cyrillic character in a word that
  is not Cyrillic, and it reduces to the codepoint under `resembles`: the two
  are indistinguishable on screen
src/render.ts:1:16  [high] bidi-control U+202E  right-to-left override: a
  bidirectional control reorders how the rest of the line renders, so the text
  a reviewer reads is not the text that runs
3 findings in 3 files
# in CI, for the CVE and nothing else:
unicode-le --fail-on bidi .
Exit 0 clean, 1 findings, 2 the question was malformed. stdout is one JSON document; stderr is what you see above.
| Route | Command | Worth knowing |
|---|---|---|
| cargo | cargo install unicode-le |
Any platform, needs Rust 1.88+. |
| From source | git clone https://github.com/nolindnaidoo/unicode-lecd unicode-le/crate && cargo build --release |
The same build CI runs. |
No runtime, no network, nothing written.
This is the part that decides whether the tool survives contact with a real repository. A naive confusable check flags every letter of every Russian and Chinese string in your tree — thousands of findings on exactly the codebases that most need the check, so it gets switched off, and the Trojan Source screen goes off with it.
A word is judged, never a file. Привет is wholly Cyrillic and is
Russian. The Cyrillic а in pаypal sits in a word that is otherwise
Latin, and only that one is a finding. Japanese mixes Han, Hiragana and
Katakana in one word constantly, and UTS #39 knows that is Japanese.
A file plainly written in another script is refused, not guessed at.
Your zh-CN.json gets a refusal saying the confusable check did not run
on it and why — not four hundred findings. Every other check still did.
Naming the script judges it properly. --script Han says Han is
expected here, so a Latin product name inside a Chinese string is a
translation rather than a finding — while a Cyrillic letter in a Latin
word in that same file is still caught.
Reproduce it against the three translation fixtures the crate ships — Chinese, Russian and Japanese:
unicode-le fixtures/documents/{zh-cn,ru,ja}.json
unicode-le --script Han,Hiragana,Katakana,Cyrillic fixtures/documents/{zh-cn,ru,ja}.json| findings | refusals | |
|---|---|---|
| no script declared | 0 | 3 — intentional_script_context, naming the share it measured |
--script Han,Hiragana,Katakana,Cyrillic |
0 | 0 — every check ran |
Both numbers matter. The second says the checks ran and found nothing.
$ unicode-le locales/
locales/en.json:412:19  [high] bidi-control U+202E  at metrics.headline.eyebrow
  right-to-left override: a bidirectional control reorders how the rest of the
  line renders, so the text a reviewer reads is not the text that runs
A line number in a five-thousand-line catalogue is something you have to
go and look up. metrics.headline.eyebrow is the thing you were looking
for. JSON, YAML, TOML, INI, .env and CSV all resolve a key path;
anything else is scanned exactly the same way and reports the same
findings without one.
The format never decides whether a finding exists, only how it is addressed. A file whose format cannot be parsed still gets scanned, and a truncated document still yields the key paths it did manage to read.
One thing it does decide: inside a JSON string, \n is an escape and
not the letter n, so "Hello\nПривет" is no longer reported as a word
that mixes scripts. In a .txt file it still is, because there a
backslash is an ordinary character and C:\Привет is a path.
No --fix. No normalization. No stripping. The form your text is in is
reported; what to do about it is a decision with context this tool
does not have — your NFD fixture may be NFD on purpose, and a test that
pins a decomposed sequence breaks the moment something helpfully
composes it.
It also cannot prove text safe. A confusable pair added after Unicode 16.0 is not in the tables it stands on. Silence is not a clearance.
| kind | severity | what |
|---|---|---|
bidi-control |
high | The Trojan Source class, CVE-2021-42574. U+202A–U+202E, U+2066–U+2069, U+061C. |
confusable |
high | A homoglyph: Cyrillic а for a, Greek ο for o, full-width F, mathematical 𝐚. Reports what it resembles. |
mixed-script |
high | One word that no single script accounts for. |
invisible |
medium | Zero-width space, joiner and non-joiner, word joiner, soft hyphen, an interior BOM, the Mongolian vowel separator. |
unassigned-or-private-use |
medium | Private-use, unassigned, noncharacter. |
non-nfc |
low | A line that is not in Normalization Form C, with the form it is in. |
unusual-whitespace |
low | No-break space, ideographic space, and the rest of the spaces that are not the space. |
Severity does not rank bidi-control above the other two highs — three
levels cannot say "this one is the CVE". --fail-on bidi does.
| reason | when |
|---|---|
binary_or_undecodable |
a NUL byte, bytes that are not UTF-8, or a file it could not read |
encoding_unknown |
a UTF-16 or UTF-32 byte-order mark |
intentional_script_context |
the file is written in an undeclared non-Latin script |
No encoding is ever guessed. Read a UTF-16 file as UTF-8 and every second byte looks like a NUL: a tool that guessed would report a file full of invisible and unassigned characters that are not in it. A confident, detailed, fabricated answer is the worst thing a security screen can produce.
Refusals do not fail the run. --strict makes them exit 2, for a
pipeline that wants to insist the scan covered what it was pointed at.
  --kind <kind>     bidi, invisible, confusable, mixed-script, non-nfc,
                    whitespace, unassigned (repeatable, comma-separated)
  --script <tag>    a non-Latin script this tree is expected to contain,
                    by Unicode name or ISO 15924 tag: Han, Cyrillic, Hani
  --fail-on <what>  any (default) or bidi
  --strict          exit 2 if any file was refused
  --stdin           read one document from stdin
  --hidden          walk hidden files and directories too
  --no-ignore       walk files that .gitignore excludes
unicode-le mcpTwo tools over stdio:
detect_unicode_risks— a document in, findings out. No filesystem. Worth pointing at explicitly: a model that reads a file itself has already swallowed the bidi controls in it. What comes back from here isU+XXXXand English, so the answer cannot carry the attack into a commit message or a review comment.unicode_le_scan— files or directories in, the same report the CLI writes.
Both return { ok, data, diagnostics, meta }, where ok means the check
ran — never that the answer was yes.
unicode-security (UAX #39
— confusable skeletons, script sets, mixed-script detection),
unicode-script (UAX #24) and
unicode-normalization
(UAX #15), all from unicode-rs. UAX #39 is a data standard and its tables
move with every Unicode release; copying them into this crate would be a
maintenance debt, not a feature. What this crate adds is the layer none
of them have: walking a tree, refusing an encoding, locating a risk at a
line and column, and knowing when not to answer. See
SPEC.md.
| What | Where |
|---|---|
| What this tool is allowed to say — scope, output contract, refusals, non-goals | SPEC.md |
| How the code is written and held together — architecture, invariants, the gates | AGENTS.md |
| What changed | CHANGELOG.md |
| The tool's page, and the other fifteen | letools.dev/tools/unicode-le |
Sixteen single-purpose tools for the work in front of every model. Each ships a Rust CLI and an MCP server. One page: letools.dev
Get it out
- String-LE — Extract every string in a codebase, with its position, so a person can read them
- Numbers-LE — Extract every hardcoded number in a codebase, so a person can check them
- Units-LE — Extract every quantity with its unit, normalized, and refuse the ambiguous ones by name
- Dates-LE — Extract every date and timestamp, and the exact instant each one resolves to
- IDs-LE — Extract every UUID, ULID, NanoID, ObjectId and Snowflake, and decode the time inside
- IPs-LE — Extract every IP address, CIDR block and MAC, normalized and classified by scope
- URLs-LE — Extract every URL in a codebase, with its protocol and exact position
- Paths-LE — Extract every file path in a codebase, and say whether it still points at anything
- Colors-LE — Extract every color in a codebase, and say which ones are not in your palette
Check it
- Regex-LE — Find every regex in a codebase, and report which can be driven into catastrophic backtracking
- Versions-LE — Find where one dependency is constrained differently across a repository's manifests
- i18n-LE — Identify the i18n library a project uses, then audit its catalogs by that library's rules
- Scrape-LE — Check whether a page is scrapeable before the scraper is written, and say when it cannot tell
Guard it
- Secrets-LE — Find hardcoded credentials in a codebase, and never print one into the report
- EnvSync-LE — Compare the dotenv files in a tree, and say which keys are missing from which
- Unicode-LE — Find the Unicode that hides meaning — bidi controls, invisibles, homoglyphs, mixed scripts
Each stands on its own: no shared crate, no published core. Where two of them agree, it is because the same answer was right twice.
Contact — nolindnaidoo.com · GitHub · LinkedIn
Rust — pixelcoords and pixelactions are one loop: pixelcoords answers where, pixelactions acts there. Their own tools, their own voice — not part of the LE family.
- pixelcoords — Freeze your screen, mark regions, get pixel-exact coordinates and crops pixelcoords.dev · crates.io · docs.rs
- pixelactions — Consume human-verified coordinates, perform the interaction, confirm it landed pixelactions.dev · crates.io · docs.rs
MIT — see LICENSE.